Just landed here? This post is the pilot’s first pass. It grew out of two tests before it — five self-hosted image models drawing the same character sheets and eight self-hosted voice models in Arabic and English — and it continues in pass 2, where the reference pictures, the chant, the lip-sync test and the finished films are. The whole series is listed at the end.
This is the third post in our test of self-hosted models for an animated family series inspired by Emirati culture. The first two picked the image model, FLUX.2 [klein] 9B, and the voice model, Audar-TTS V1 Turbo. This one covers a single night on three of our GPUs. First, three open video models animated the same two shots of the pilot. Then the whole pilot, 24 shots and about three minutes, was drafted from script to finished cut, once in Arabic and once in English.
Every model in this post ran on our own GPUs. No cloud API was used for any image, voice or video.
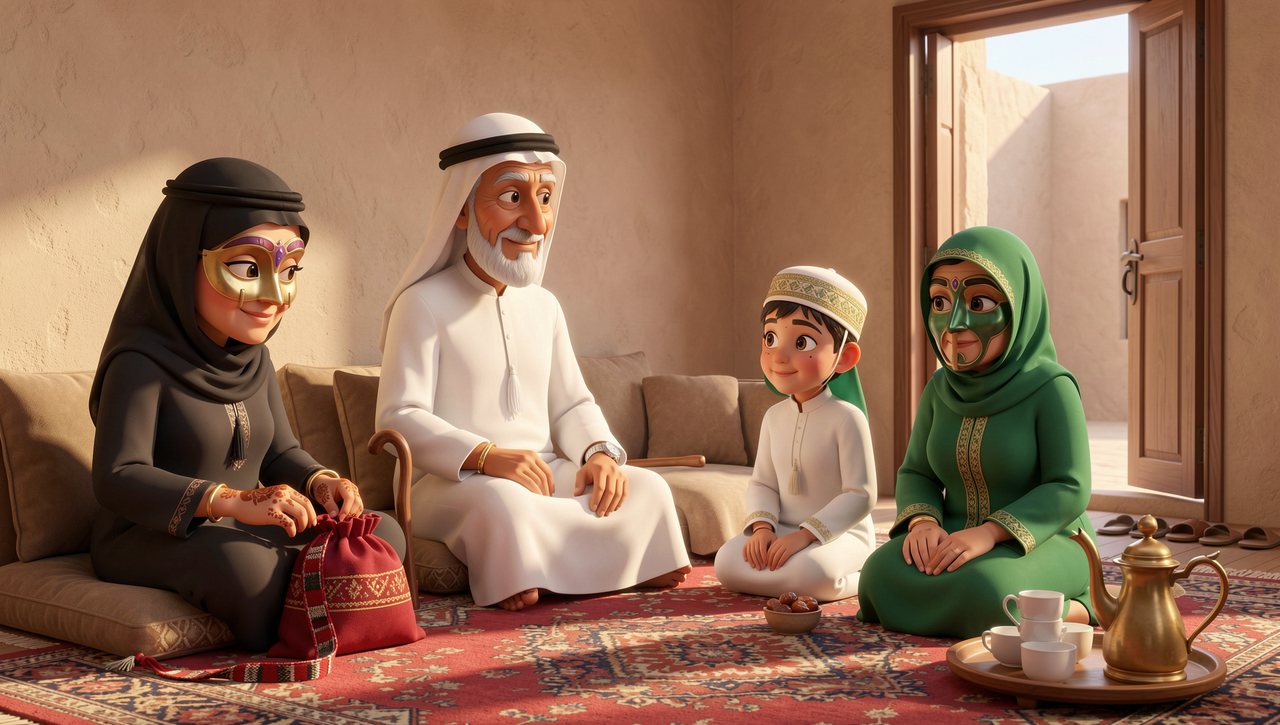
The pilot is a short story about Hag Al Laila, the mid-Sha’ban evening when children go from door to door singing and neighbours fill their cloth bags with nuts and sweets. A grandmother, Yadda, sews a khareetah (the drawstring bag) for her granddaughter Noora. Noora is too shy to sing alone, and her older brother Salem thinks he is too grown-up to go, until his grandmother reminds him what a grown-up does.
This is a draft made to learn from, not a finished film. The sections below show every picture, voice take and clip the night produced, including the defects, so the next pass can fix them.
The result: the pilot drafted in two languages
Both cuts are 3 minutes 8 seconds long: the 24 shots joined at their planned lengths, with the voices placed where each character speaks and a soft instrumental music bed underneath. The Arabic cut carries English subtitles. There is no ambient sound, sound effects or colour pass yet, and the two chant shots have music but no singing.
Watch these as a first assembly. The dialogue, the pacing and most of the performances are there; the most visible problems are in the group shots, where a character’s details land on the wrong person, and in a few clips where an extra person or object appears. Every shot is listed further down with its takes and what is wrong with it, so the next pass can go shot by shot.
The music bed: six takes to choose from
The first two shots have no dialogue, so the first version of the cuts opened on 13 seconds of silence. ACE-Step v1 3.5B, running on one RTX 5090, generated six instrumental takes from one prompt (gentle warm Middle Eastern family film score: oud, qanun, soft riq and frame drum, light strings, tender, nostalgic, calm), 200 seconds each, in about 15 seconds per take once loaded.
Each take was checked for level and, with speech recognition over the whole 188 seconds, for any voice-like passage: five of the six produced recognisable ‘words’ somewhere, which this model tends to invent even when asked for no vocals, and take 6 produced none, so take 6 is in the cuts. What speech recognition cannot tell is whether a take is musically right, so all six are here to choose from by ear. The bed sits about 9 dB under the dialogue and ducks further while anyone speaks; the English words were still recognised 92% of the time with it underneath.
The GPUs
- Two NVIDIA GeForce RTX 5090 (32 GB VRAM), in one workstation, one ComfyUI server per card.
- One NVIDIA RTX PRO 6000 Blackwell Workstation Edition (96 GB VRAM), in a second machine.
Each card ran one job at a time. The times in this post are execution times per job as ComfyUI recorded them (or our render farm’s log where ComfyUI’s record was lost), including loading the model for the first job on a card.
Part 1: three open video models on the same two shots
The clips in this part are silent on purpose. This test compared motion and whether the characters stay the same people, so no voice went into any of them, and the soundtrack LTX-2.5 makes up on its own is unusable noise, so it was removed. The dialogue, with lip sync, is in Part 2 and in the two cuts above.
Before rendering the whole pilot we wanted to see how the open video models handle this look and these characters. We took two shots: the wide opening shot of the majlis with all four characters, and a close-up of Noora. Each got a keyframe from FLUX.2 [dev] and from FLUX.2 [klein] 9B, and three video models animated each keyframe with the same motion prompt. No audio went in, so this test is about motion and about whether the characters stay the same people as they move.
The settings
- Keyframes: FLUX.2 [dev] (50 steps, on the NVIDIA RTX PRO 6000 Blackwell Workstation Edition (96 GB VRAM)) and FLUX.2 [klein] 9B (4 steps, on an NVIDIA GeForce RTX 5090 (32 GB VRAM)), 1920×1088, two seeds each.
- LTX-2.5 distilled: 1920×1088 at 24 fps, the full shot length (169 frames for 7 s, 121 for 5 s), on an NVIDIA GeForce RTX 5090 (32 GB VRAM).
- HunyuanVideo 1.5 720p I2V (cfg-distilled): 1280×720, 121 frames at 24 fps, 50 steps, on an NVIDIA GeForce RTX 5090 (32 GB VRAM).
- Wan 2.2 I2V A14B (fp16, high-noise and low-noise experts): 1280×720, 81 frames at 16 fps, 40 steps, on the NVIDIA RTX PRO 6000 Blackwell Workstation Edition (96 GB VRAM).
- No audio, no reference images, no LoRA, one seed per clip. Wan and Hunyuan make one generation of about 5 s, so their clips of the 7-second wide shot are short by design.
Shot 1: the majlis, all four characters, 7 s
The wide shot is the hard case for a text-only keyframe: four characters, each described in full, in one prompt. FLUX.2 [dev] got the casting right in both of its takes, with four people and the battoulah on the grandmother, but it drew the battoulah as a mask over her mouth and aged the girl in one take. FLUX.2 [klein] 9B, the model we chose for its look, put the mask on the children and added a fifth person. The first FLUX.2 [dev] keyframe was drawn again on its own after our Bangalore machine stalled during the night, which is why its clips arrived last.
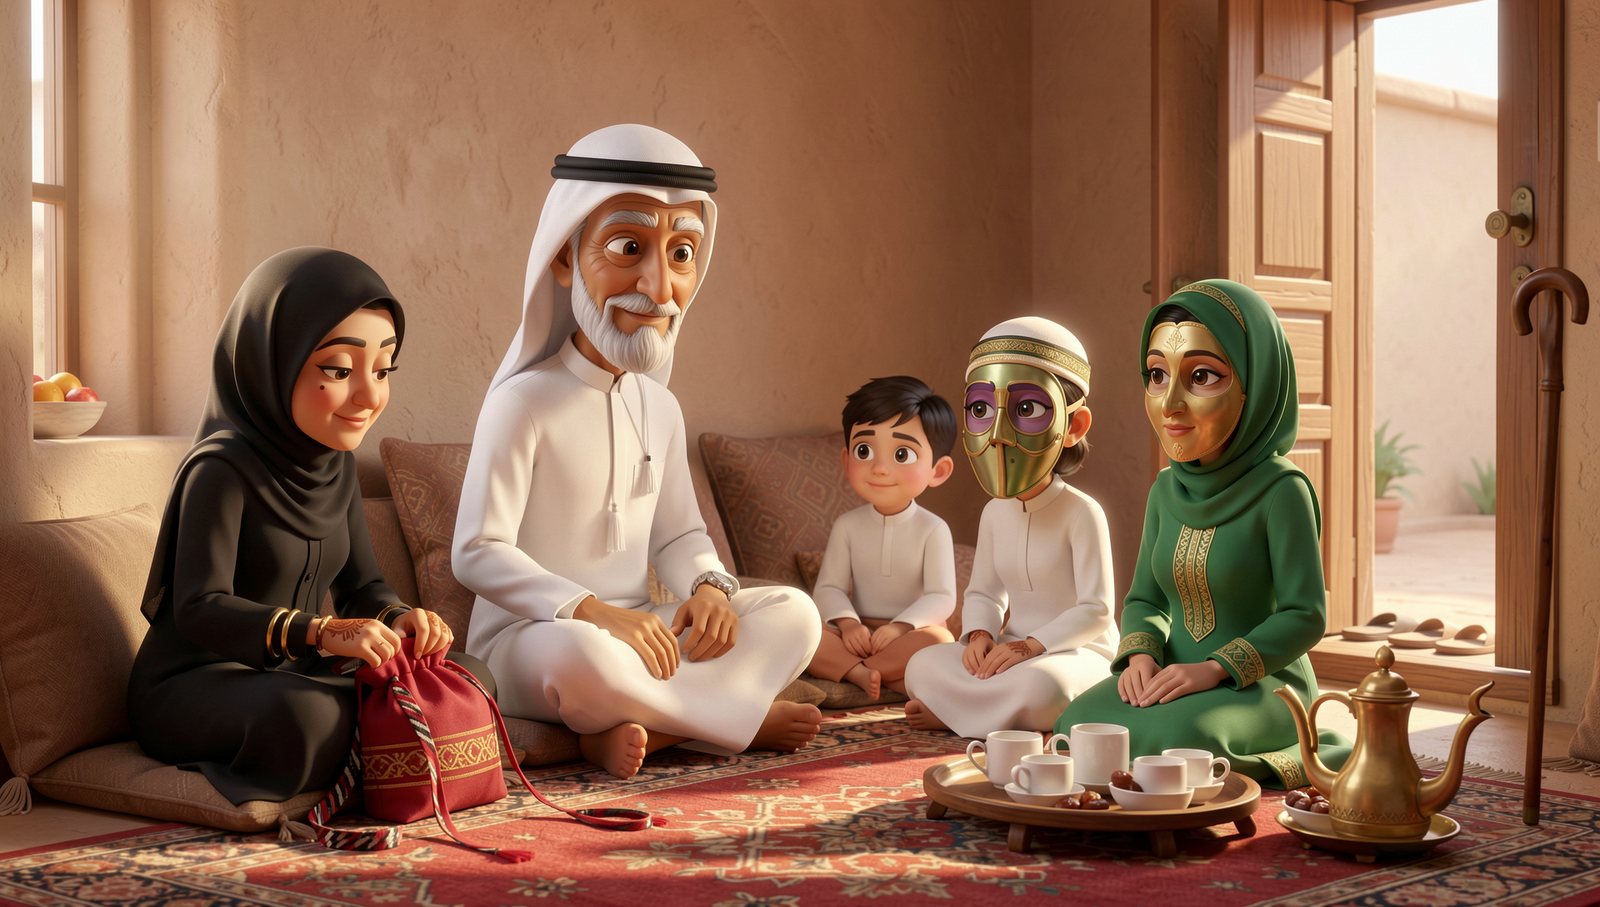
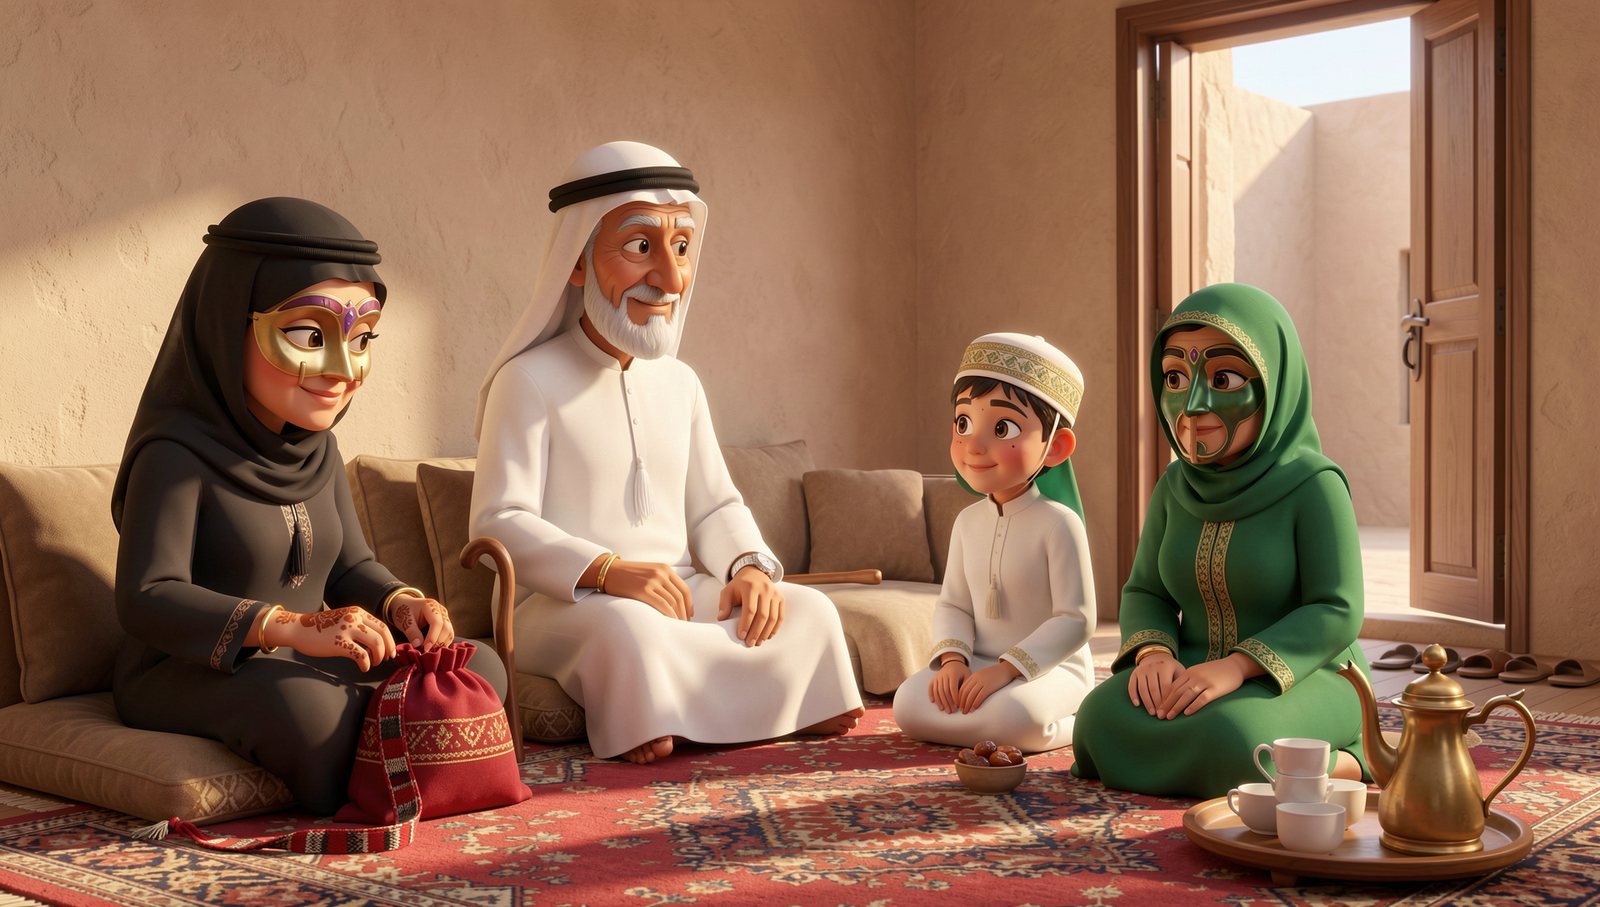
LTX-2.5 keeps every face and costume steady for all 7 seconds and makes the slow push-in the prompt asks for. The people barely move, apart from small head turns. The problem is in the keyframe, not the motion: it has five people, not four, and the battoulah face mask on two of the children instead of the grandmother.
HunyuanVideo 1.5 makes the strongest camera move of the three: a clear, smooth push-in. The faces hold, with small drifts in the grandfather’s face, and the drawstring moves. It outputs 720p, and it inherits the keyframe’s wrong casting.
Wan 2.2 is the most stable: nothing drifts, and the grandmother’s hands keep working the thread. It ignores the push-in, though, and the camera barely moves. It renders 81 frames at 16 fps, about 5 seconds of the 7-second shot.
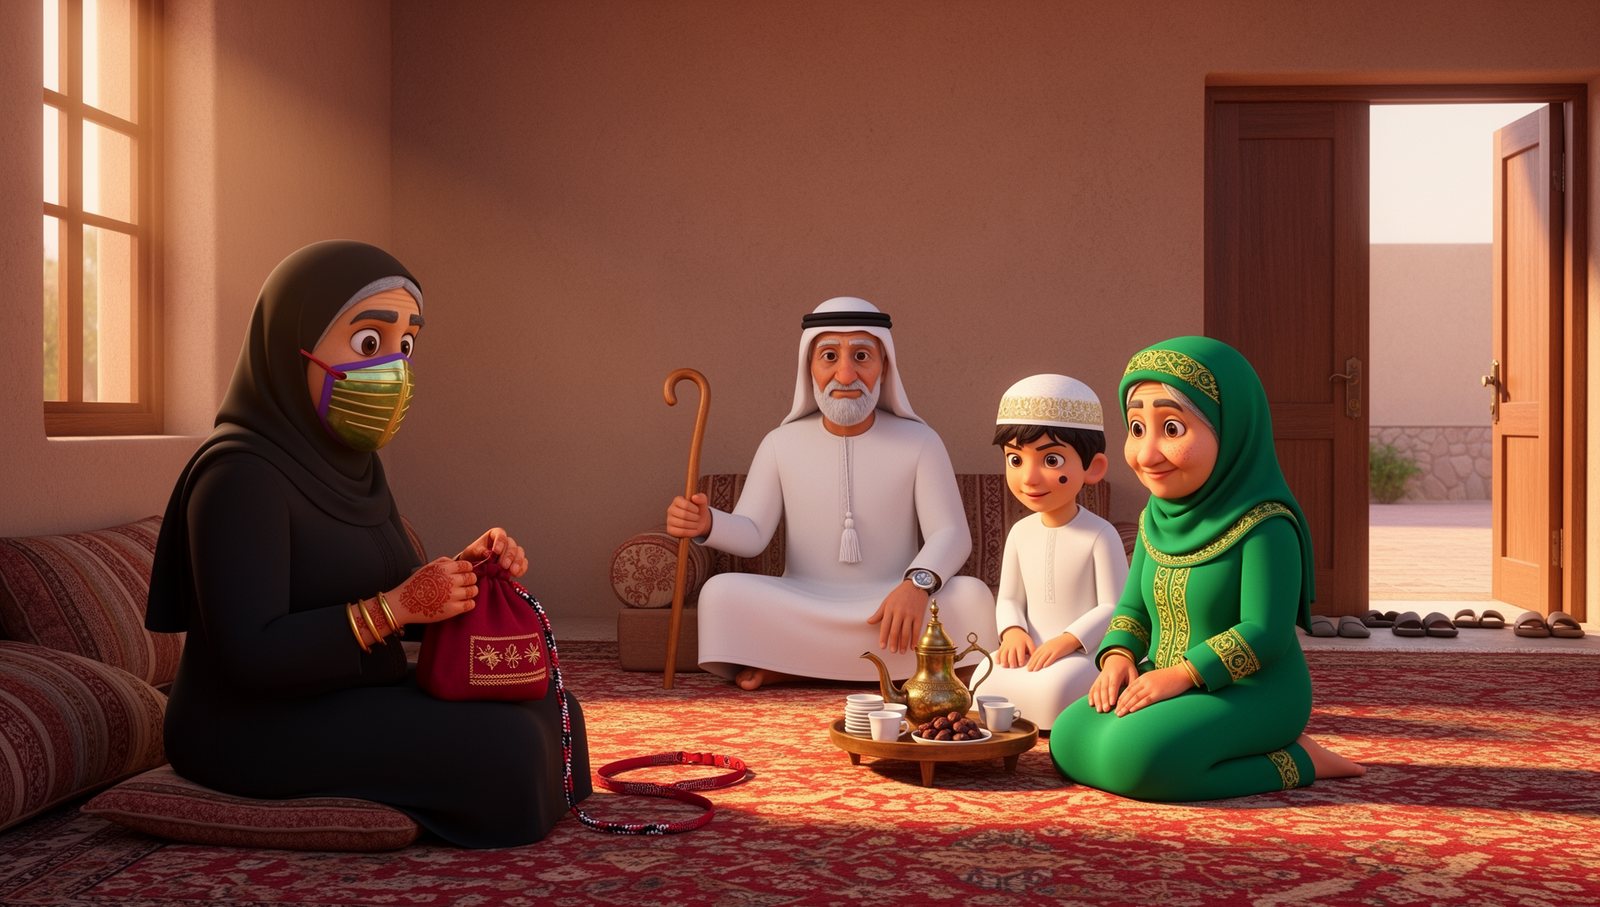
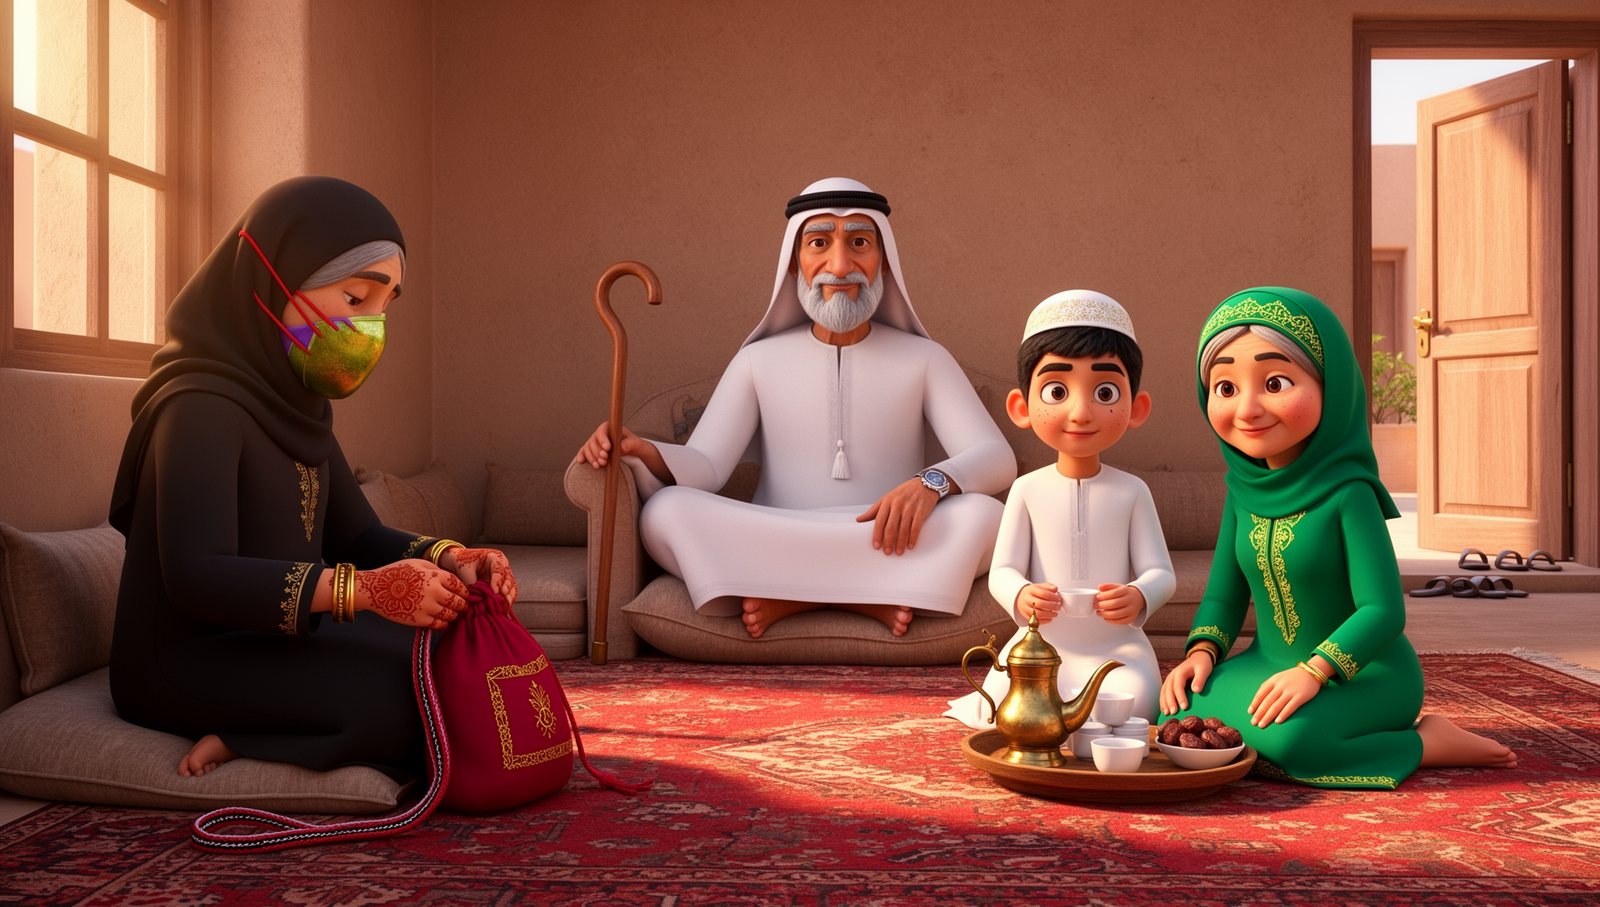
From the FLUX.2 [dev] keyframe, with the right four people, LTX-2.5 keeps everyone consistent, but its push-in heads for the wrong place: instead of moving slowly toward the grandfather at the head of the room, it swings toward the grandmother and ends on a large close-up of her mask, dropping Noora from the frame.
From the same FLUX.2 [dev] keyframe, Hunyuan makes the move the prompt describes: a steady push-in toward the head of the room, ending on the grandfather with Salem and Noora beside him, with the grandmother passing out of frame at the left. Everyone stays consistent. Of all the clips of this shot, it follows the direction best.
Wan 2.2 on the FLUX.2 [dev] keyframe behaves as it did on the klein one: rock-steady characters and small natural movements, the grandmother sewing and the children shifting, but almost no camera move.
Shot 9: Noora's close-up, 5 s
The close-up is the easy case for the keyframe, one character, and the harder case for acting: Noora’s smile fades, she twists the drawstring, glances up and speaks quietly. Both image models drew her well; the differences are in how each video model plays the moment.
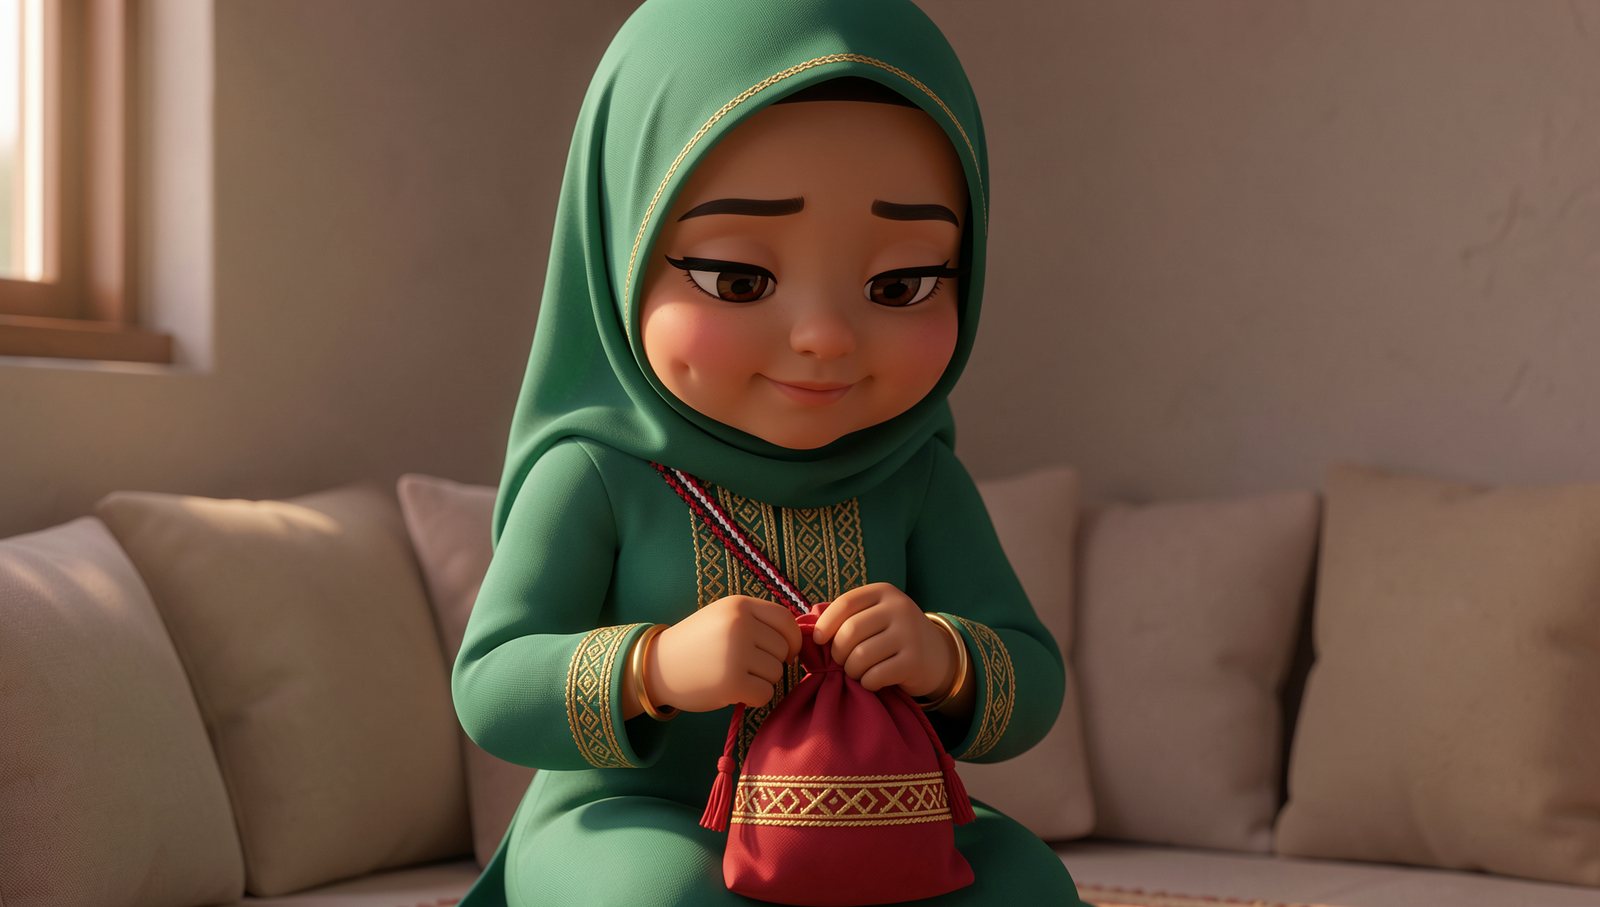
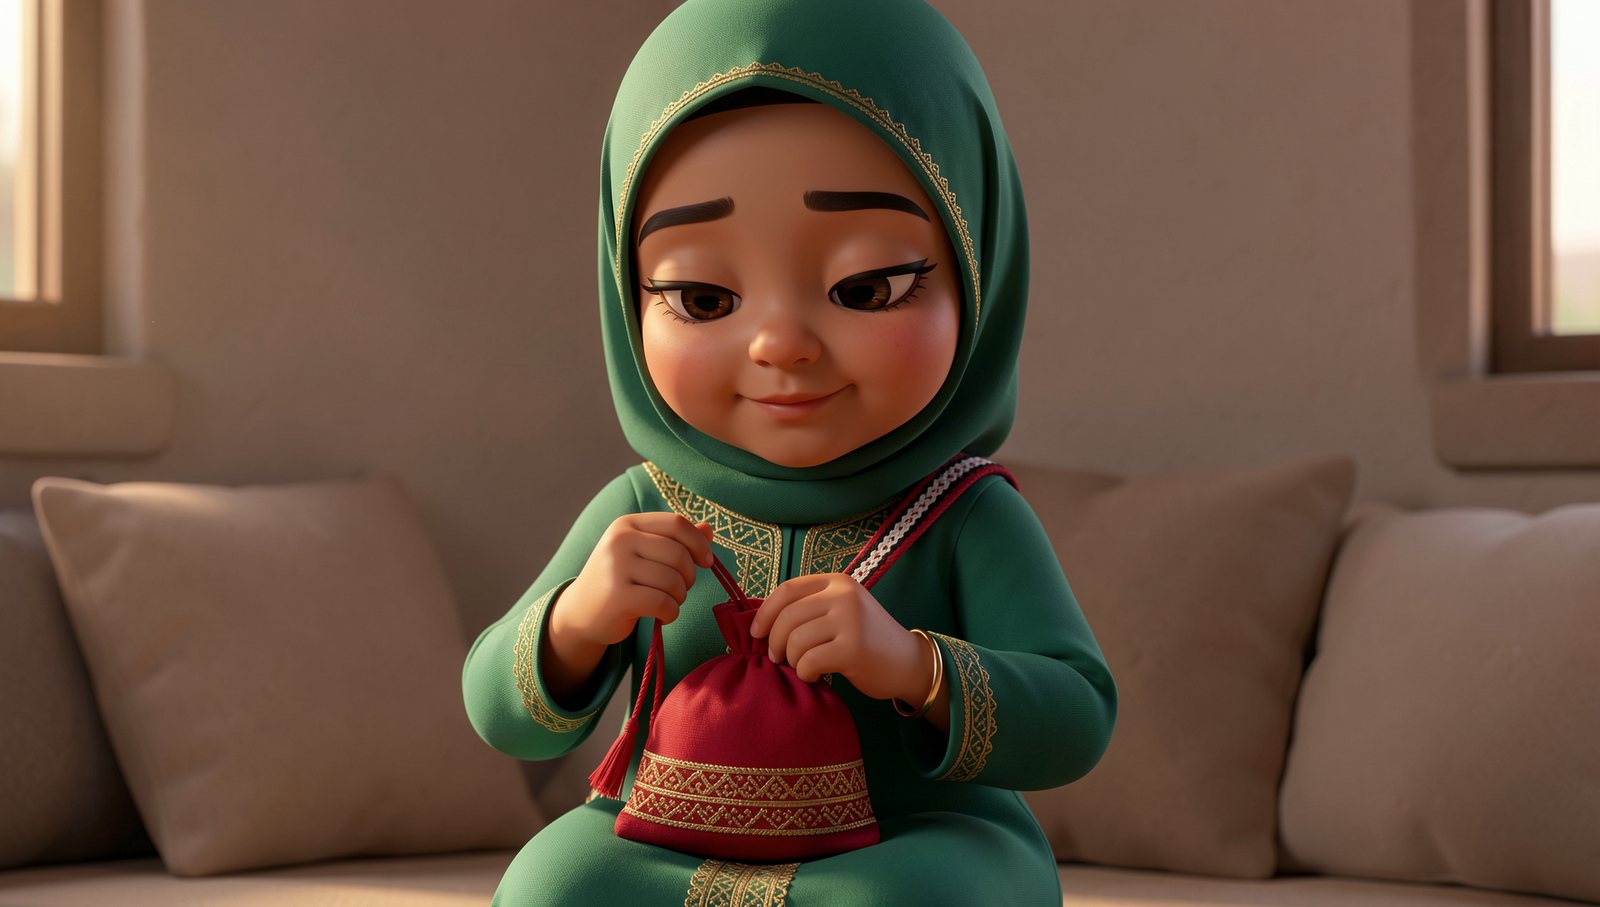
From the klein 9B close-up, LTX-2.5 moves Noora’s eyes, brows and mouth expressively and keeps her head covering in place. She speaks, as the motion prompt says, although no audio went in. Her face is a little rounder from one moment to the next, and the keyframe gives her a small mole that belongs to her brother.
From the klein 9B close-up, Hunyuan pushes in hard, from waist-up to her face alone, and her worried expression and quiet speech suit the moment. The face stays the same girl, but the push goes well past ‘very slight’, and her hands and the bag leave the frame.
From the klein 9B close-up, Wan 2.2 again keeps the framing gentle and the girl steady: she looks up, speaks a few soft words, and her face, head covering and bag hold through every frame. The dimples and the stray mole from the keyframe stay put, so nothing drifts, and the performance is small and believable.
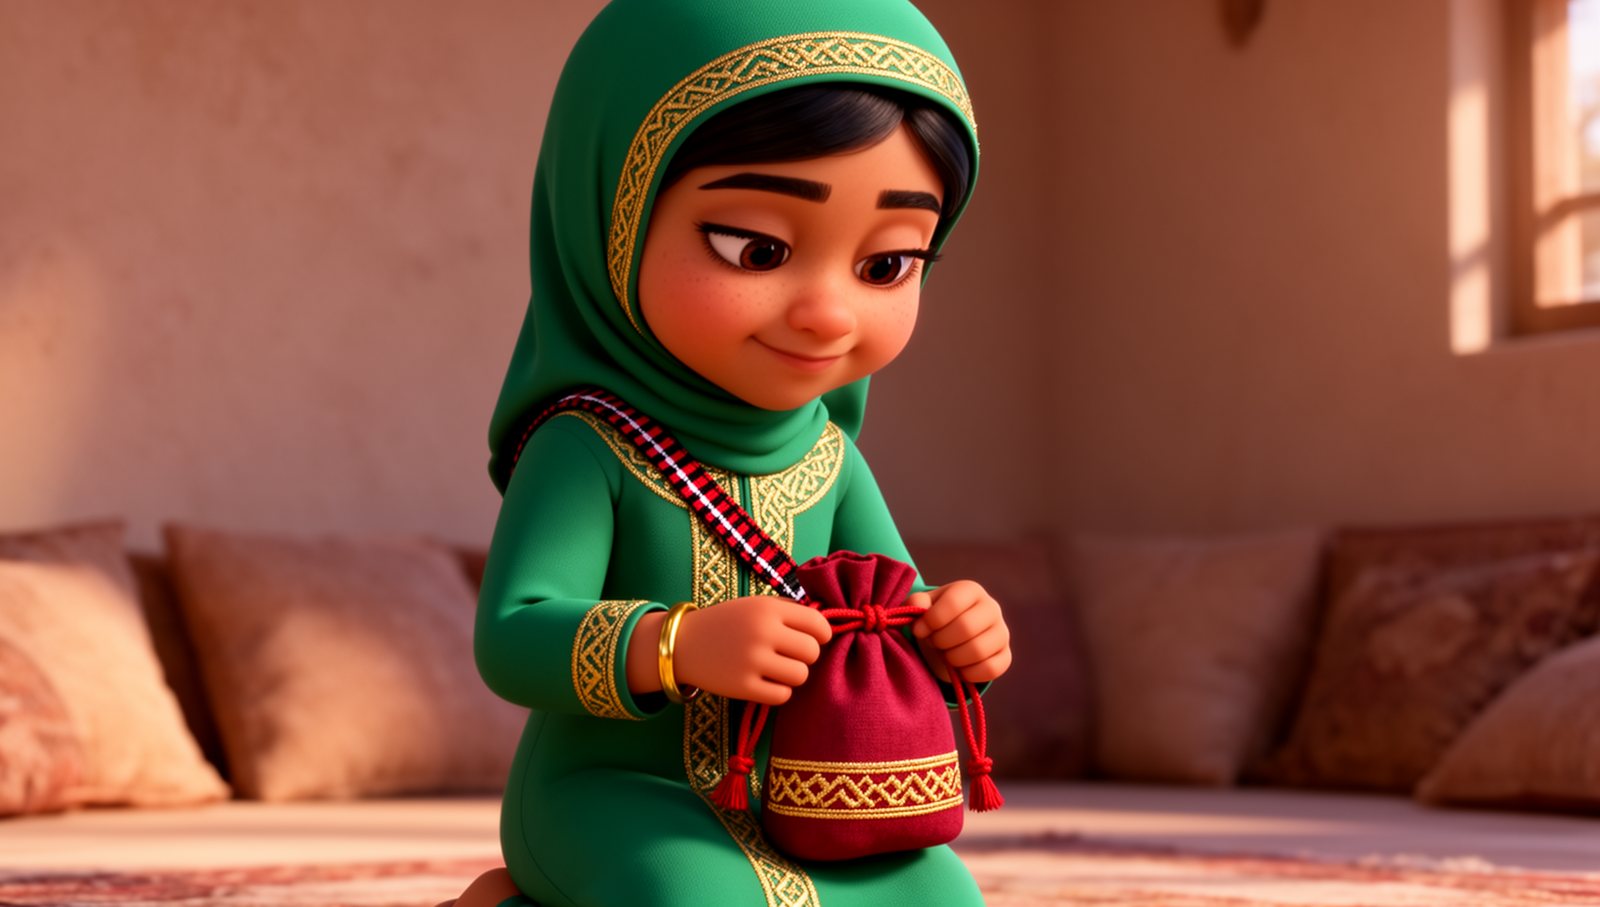
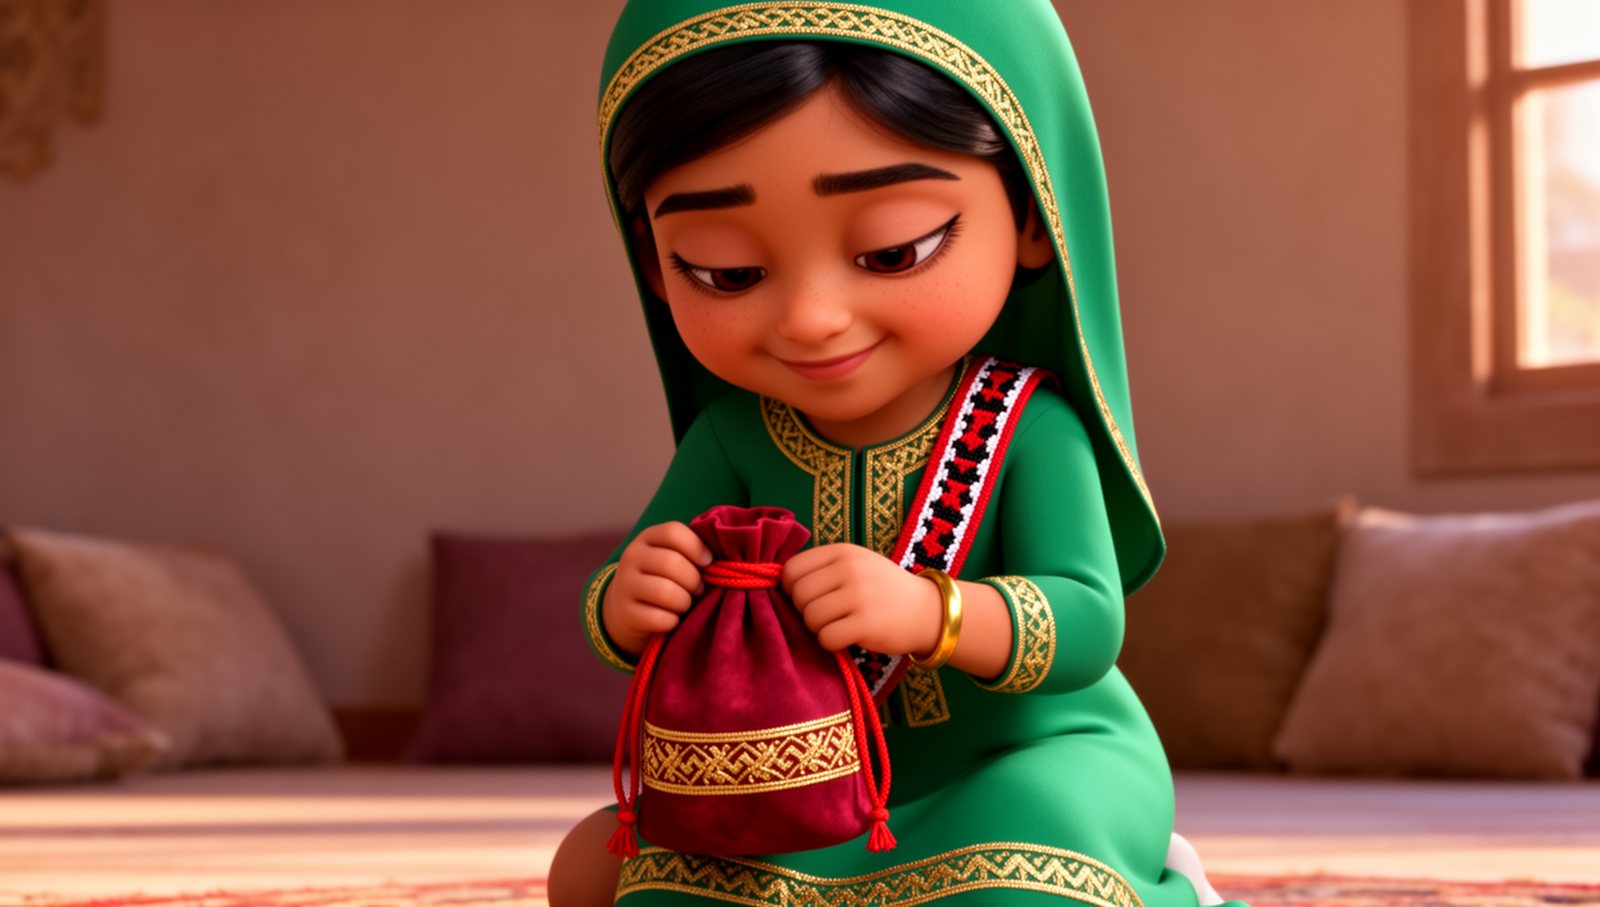
From the FLUX.2 [dev] keyframe, the mood matches the shot better: she looks down, glances up and speaks. Some hair shows under her head covering in the keyframe, and it stays visible throughout.
Hunyuan keeps her face sharp and consistent, but it pushes in much further than the ‘very slight’ move asked for, and she smiles and chats where the shot wants her shy and quiet.
Wan 2.2 plays the shot as written: a very slight push-in, and Noora glances up shyly, says something softly, then lowers her eyes again, with her face and the bag steady throughout. Of the six clips of this shot, its acting fits the moment best. It is 16 fps and about 5 seconds, the same length as the shot.
How long each clip took
Render time is ComfyUI’s execution time for the clip, from the start of the job to the saved video, including loading the model when it was the first job on that card.
| Video model | Card | Clips | Average per clip | Range | GPU time per second of video |
|---|---|---|---|---|---|
| LTX-2.5 (distilled) | RTX 5090 (32 GB) | 4 | 6 min 18 s | 2 min 54 s to 11 min 27 s | 1 min 02 s |
| HunyuanVideo 1.5 720p I2V | RTX 5090 (32 GB) | 4 | 29 min 02 s | 27 min 47 s to 30 min 32 s | 5 min 45 s |
| Wan 2.2 I2V A14B | RTX PRO 6000 (96 GB) | 4 | 37 min 14 s | 34 min 18 s to 40 min 13 s | 7 min 21 s |
| Shot | Keyframe | Video model | Card | Output | Render time | Per second of video |
|---|---|---|---|---|---|---|
| 1 | FLUX.2 [dev] | LTX-2.5 (distilled) | RTX 5090 (32 GB) | 1920×1088, 169 frames at 24 fps (7.0 s) | 7 min 54 s | 1 min 07 s |
| 1 | FLUX.2 [dev] | Wan 2.2 I2V A14B | RTX PRO 6000 (96 GB) | 1280×720, 81 frames at 16 fps (5.1 s) | 40 min 09 s | 7 min 56 s |
| 1 | FLUX.2 [dev] | HunyuanVideo 1.5 720p I2V | RTX 5090 (32 GB) | 1280×720, 121 frames at 24 fps (5.0 s) | 30 min 32 s | 6 min 03 s |
| 1 | FLUX.2 [klein] 9B | LTX-2.5 (distilled) | RTX 5090 (32 GB) | 1920×1088, 169 frames at 24 fps (7.0 s) | 11 min 27 s | 1 min 38 s |
| 1 | FLUX.2 [klein] 9B | Wan 2.2 I2V A14B | RTX PRO 6000 (96 GB) | 1280×720, 81 frames at 16 fps (5.1 s) | 40 min 13 s | 7 min 57 s |
| 1 | FLUX.2 [klein] 9B | HunyuanVideo 1.5 720p I2V | RTX 5090 (32 GB) | 1280×720, 121 frames at 24 fps (5.0 s) | 29 min 43 s | 5 min 54 s |
| 9 | FLUX.2 [dev] | LTX-2.5 (distilled) | RTX 5090 (32 GB) | 1920×1088, 121 frames at 24 fps (5.0 s) | 2 min 55 s | 35 s |
| 9 | FLUX.2 [dev] | Wan 2.2 I2V A14B | RTX PRO 6000 (96 GB) | 1280×720, 81 frames at 16 fps (5.1 s) | 34 min 18 s | 6 min 47 s |
| 9 | FLUX.2 [dev] | HunyuanVideo 1.5 720p I2V | RTX 5090 (32 GB) | 1280×720, 121 frames at 24 fps (5.0 s) | 28 min 04 s | 5 min 34 s |
| 9 | FLUX.2 [klein] 9B | LTX-2.5 (distilled) | RTX 5090 (32 GB) | 1920×1088, 121 frames at 24 fps (5.0 s) | 2 min 54 s | 35 s |
| 9 | FLUX.2 [klein] 9B | Wan 2.2 I2V A14B | RTX PRO 6000 (96 GB) | 1280×720, 81 frames at 16 fps (5.1 s) | 34 min 18 s | 6 min 47 s |
| 9 | FLUX.2 [klein] 9B | HunyuanVideo 1.5 720p I2V | RTX 5090 (32 GB) | 1280×720, 121 frames at 24 fps (5.0 s) | 27 min 47 s | 5 min 31 s |
What we saw
LTX-2.5 is by far the fastest: a 5-second clip at full HD took about three minutes on an RTX 5090 once the model was loaded, against 28 to 31 minutes for HunyuanVideo 1.5 and 34 to 40 minutes for Wan 2.2 at 720p. It is also the only one of the three that renders the full length of a shot at 1920×1088 and takes an audio track to drive the lip sync. Its faces are expressive, and its camera moves sometimes head for the wrong subject.
HunyuanVideo 1.5 makes the most convincing camera moves and follows a directed push-in best, but it overshoots gentle ones and sometimes plays a quiet moment too brightly.
Wan 2.2 is the steadiest: no identity drift in any clip, and the most restrained, believable acting in the close-ups. It largely ignores camera direction, renders at 16 fps, and is the slowest by a wide margin, on our largest card.
The keyframe decides the casting. No video model repaired a wrong keyframe: a mask on the wrong character or an extra person carries through every frame. So the keyframe is where most of the quality work has to go.
For the pilot draft we used LTX-2.5, because it is the only one of the three that lip-syncs to our voices and renders the whole shot at full HD in minutes. Wan 2.2 and HunyuanVideo 1.5 stay candidates for shots without dialogue.
Part 2: the whole pilot, script to cut, in one night
With the image and voice models already chosen, the second half of the night rendered the whole pilot as a draft. Nothing new was tested here: the aim was to find out what a full pass from script to cut takes on our own hardware, and what breaks when it runs end to end.
Speaking shots are rendered once per language rather than dubbed. Arabic and English lines differ in length and rhythm, so a clip animated to the Arabic line cannot simply take the English audio. Rendering both costs 14 extra clips; both renders start from the same keyframe and seed, so the two versions keep the same framing and diverge only where the voice drives the performance.
How it was made
- Script and shot list. 24 shots, 188 seconds, five scenes, four characters. Every spoken line is written in Emirati Arabic and in English. Each shot has a keyframe prompt and a motion prompt, and each character has one identity text used word for word.
- Voices: Audar-TTS V1 Turbo read every line that is spoken, not sung, in both languages, three takes each: 96 clips. Each character copies a synthetic reference voice that another model designed from a description (age, sex, pitch); no real person’s voice was cloned.
- Choosing a take: each take was transcribed with Whisper small on the CPU and compared word by word with the script, and its speech was measured against the shot’s speaking window. The chosen take is the one that fits the shot and matches the most words.
- Keyframes: FLUX.2 [klein] 9B drew three takes of every shot at 1920×1088, and three more for the six shots where all three were wrong. Every picture was reviewed by eye, and one take was picked per shot.
- Clips: LTX-2.5 animated the picked keyframe for the full length of the shot, at 1920×1088 and 24 fps. On a shot where a character speaks on camera, the chosen voice take goes into the model with the picture, so the lips move to that language: those shots are rendered twice, once in Arabic and once in English. The other shots are rendered once and used in both cuts.
- Cuts: the clips were joined with the voice tracks and cropped to 1920×1080, one cut per language, with English subtitles on the Arabic cut.
The numbers
- Voices: 96 clips on one NVIDIA GeForce RTX 5090 (32 GB VRAM), median 14.3 s each including loading the model.
- Keyframes: 90 pictures, median 7 s each; the first on a card also loads the model.
- Clips: 38 clips, 7046 frames (294 s of video), 4.6 GPU-hours: 2.4 s of GPU time per frame on average.
- NVIDIA RTX PRO 6000 Blackwell Workstation Edition (96 GB VRAM): 8 clips, 3.3 s per frame.
- NVIDIA GeForce RTX 5090 (32 GB VRAM): 30 clips, 2.0 s per frame.
These figures count the final clips only. Twenty-seven earlier renders of speaking shots were discarded and are not counted: 26 made before the fix to the voice conditioning described below, and one made with a misplaced voice track.
How long each stage took, by model
| Stage | Model | Card | Jobs | Total | Average per job | Range |
|---|---|---|---|---|---|---|
| Voices | Audar-TTS V1 Turbo | RTX 5090 (32 GB) | 96 | 23 min 54 s | 15 s | 13 s to 36 s |
| Keyframes | FLUX.2 [klein] 9B | RTX 5090 (32 GB) | 90 | 18 min 05 s | 12 s | 4 s to 2 min 55 s |
| Music | ACE-Step v1 3.5B | RTX 5090 (32 GB) | 6 | 2 min 22 s | 24 s | 15 s to 1 min 07 s |
| Clips | LTX-2.5 distilled | RTX 5090 (32 GB) | 30 | 193 min 01 s | 6 min 26 s | 2 min 56 s to 14 min 03 s |
| Clips | LTX-2.5 distilled | RTX PRO 6000 (96 GB) | 8 | 84 min 23 s | 10 min 33 s | 6 min 17 s to 14 min 00 s |
Times are per job: the voice times include loading the model, because each voice take ran as its own process; the keyframe and clip times are ComfyUI’s execution times.
How long each pilot clip took
| Shot | Version | Frames | Video length | Card | Render time | Per second of video |
|---|---|---|---|---|---|---|
| 1 | Both languages | 169 | 7.0 s | RTX PRO 6000 (96 GB) | 9 min 05 s | 1 min 17 s |
| 2 | Both languages | 145 | 6.0 s | RTX 5090 (32 GB) | 3 min 58 s | 39 s |
| 3 | Arabic | 121 | 5.0 s | RTX 5090 (32 GB) | 3 min 00 s | 36 s |
| 3 | English | 121 | 5.0 s | RTX 5090 (32 GB) | 3 min 00 s | 36 s |
| 4 | Arabic | 217 | 9.0 s | RTX 5090 (32 GB) | 9 min 58 s | 1 min 06 s |
| 4 | English | 217 | 9.0 s | RTX 5090 (32 GB) | 9 min 35 s | 1 min 04 s |
| 5 | Arabic | 121 | 5.0 s | RTX 5090 (32 GB) | 2 min 59 s | 36 s |
| 5 | English | 121 | 5.0 s | RTX 5090 (32 GB) | 2 min 56 s | 35 s |
| 6 | Both languages | 217 | 9.0 s | RTX 5090 (32 GB) | 8 min 30 s | 56 s |
| 7 | Arabic | 121 | 5.0 s | RTX 5090 (32 GB) | 3 min 00 s | 36 s |
| 7 | English | 121 | 5.0 s | RTX 5090 (32 GB) | 2 min 59 s | 36 s |
| 8 | Arabic | 193 | 8.0 s | RTX PRO 6000 (96 GB) | 10 min 39 s | 1 min 19 s |
| 8 | English | 193 | 8.0 s | RTX 5090 (32 GB) | 7 min 15 s | 54 s |
| 9 | Arabic | 121 | 5.0 s | RTX PRO 6000 (96 GB) | 6 min 17 s | 1 min 15 s |
| 9 | English | 121 | 5.0 s | RTX 5090 (32 GB) | 3 min 00 s | 36 s |
| 10 | Arabic | 241 | 10.0 s | RTX PRO 6000 (96 GB) | 14 min 00 s | 1 min 24 s |
| 10 | English | 241 | 10.0 s | RTX 5090 (32 GB) | 9 min 21 s | 56 s |
| 11 | Both languages | 193 | 8.0 s | RTX 5090 (32 GB) | 6 min 19 s | 47 s |
| 12 | Both languages | 169 | 7.0 s | RTX 5090 (32 GB) | 5 min 03 s | 43 s |
| 13 | Arabic | 121 | 5.0 s | RTX 5090 (32 GB) | 2 min 59 s | 36 s |
| 13 | English | 121 | 5.0 s | RTX 5090 (32 GB) | 2 min 59 s | 36 s |
| 14 | Both languages | 193 | 8.0 s | RTX 5090 (32 GB) | 6 min 53 s | 51 s |
| 15 | Arabic | 193 | 8.0 s | RTX 5090 (32 GB) | 7 min 15 s | 54 s |
| 15 | English | 193 | 8.0 s | RTX PRO 6000 (96 GB) | 10 min 39 s | 1 min 19 s |
| 16 | Both languages | 193 | 8.0 s | RTX PRO 6000 (96 GB) | 10 min 40 s | 1 min 20 s |
| 17 | Arabic | 169 | 7.0 s | RTX 5090 (32 GB) | 5 min 08 s | 44 s |
| 17 | English | 169 | 7.0 s | RTX 5090 (32 GB) | 5 min 03 s | 43 s |
| 18 | Both languages | 289 | 12.0 s | RTX 5090 (32 GB) | 12 min 49 s | 1 min 04 s |
| 19 | Both languages | 193 | 8.0 s | RTX 5090 (32 GB) | 6 min 19 s | 47 s |
| 20 | Arabic | 193 | 8.0 s | RTX 5090 (32 GB) | 6 min 46 s | 50 s |
| 20 | English | 193 | 8.0 s | RTX 5090 (32 GB) | 6 min 21 s | 47 s |
| 21 | Arabic | 169 | 7.0 s | RTX PRO 6000 (96 GB) | 9 min 04 s | 1 min 17 s |
| 21 | English | 169 | 7.0 s | RTX 5090 (32 GB) | 5 min 03 s | 43 s |
| 22 | Arabic | 241 | 10.0 s | RTX 5090 (32 GB) | 9 min 02 s | 54 s |
| 22 | English | 241 | 10.0 s | RTX PRO 6000 (96 GB) | 13 min 59 s | 1 min 24 s |
| 23 | Arabic | 313 | 13.0 s | RTX 5090 (32 GB) | 14 min 03 s | 1 min 05 s |
| 23 | English | 313 | 13.0 s | RTX 5090 (32 GB) | 13 min 56 s | 1 min 04 s |
| 24 | Both languages | 217 | 9.0 s | RTX 5090 (32 GB) | 7 min 32 s | 50 s |
| All 38 clips | 277 min 24 s | |||||
What went wrong during the night, and what we changed
The voice tracks were misplaced. Each line is placed inside its shot at the moment the character starts speaking. Our first version did this with an ffmpeg filter chain, loudness normalisation followed by a delay, and the delay did not survive: every track came out shorter than its shot, with the line at the very start. Checking the first finished clip’s audio caught it after one render. The tracks are now built sample by sample, checked for exact length and start time, and fixed before any other clip used them.
The voice was not reaching the picture. Measuring the finished clips showed that for five shots the Arabic and English renders were identical to the pixel, although they had been given different voice tracks. In the ComfyUI build we run, the node that joins the video and audio latents marks an audio latent without its own mask as fully to be regenerated, so the sampler replaced our voice with noise and the lips moved only because the prompt said the character speaks. Adding an all-zero noise mask to the audio latent holds the voice fixed as conditioning. On a test shot the two languages then diverged, with the girl’s mouth closing where each language’s line ends, and every speaking clip was rendered again with the fix. Earlier renders are kept but not shown.
One machine stalled. Our Bangalore machine hung while loading FLUX.2 [dev] on top of weights the previous job had left pinned in memory. Restarting its ComfyUI server before each large model change kept it running for the rest of the night.
Shot by shot
Every shot below shows all the keyframe takes FLUX.2 [klein] 9B drew, with the one we picked marked, then the clip or clips LTX-2.5 made from it and, for spoken lines, the three voice takes in each language. The note under each set of takes says why that take was picked and what is wrong in the others.
Shot 1 (7 s)
Wide establishing shot. Low afternoon sun slants into the family majlis. Yaddi sits cross-legged at the head of the room, and Salem stands beside the low coffee tray with the brass dallah, finjans and dates. Yadda sits on a floor cushion sewing the crimson khareetah, with Noora kneeling beside her; both have their feet tucked under them. Everyone is barefoot, their sandals left outside the door.
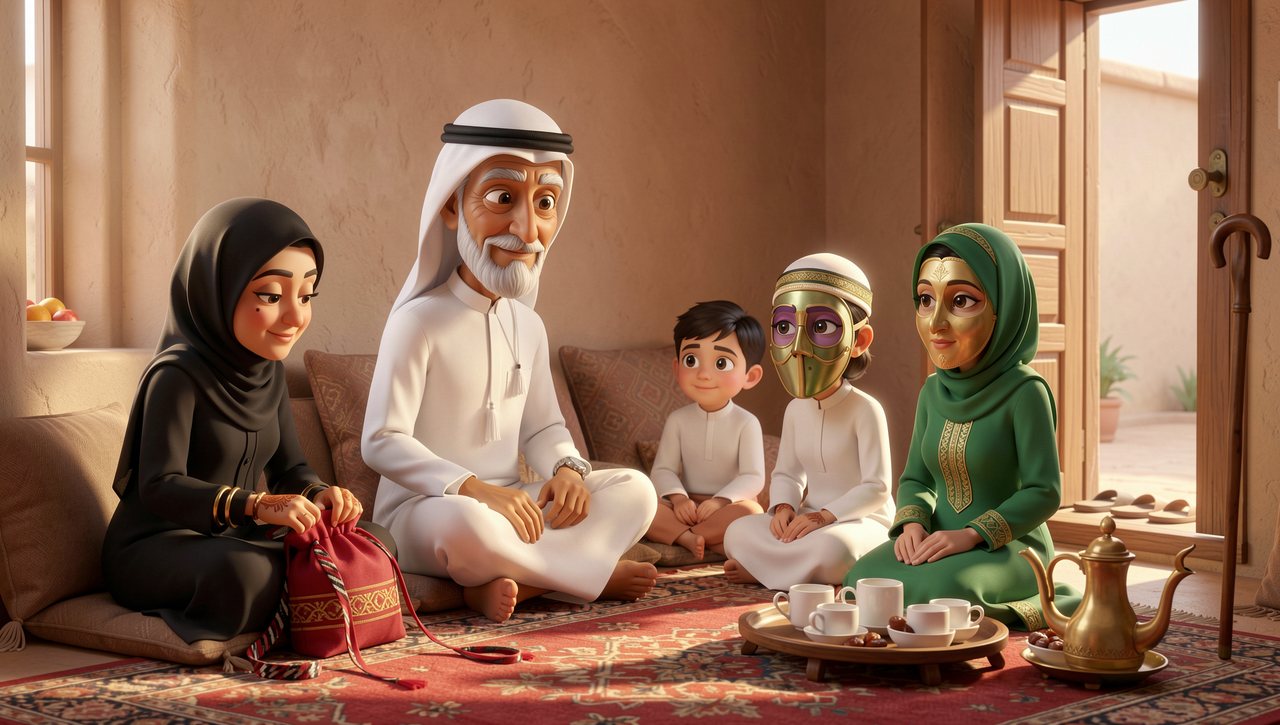
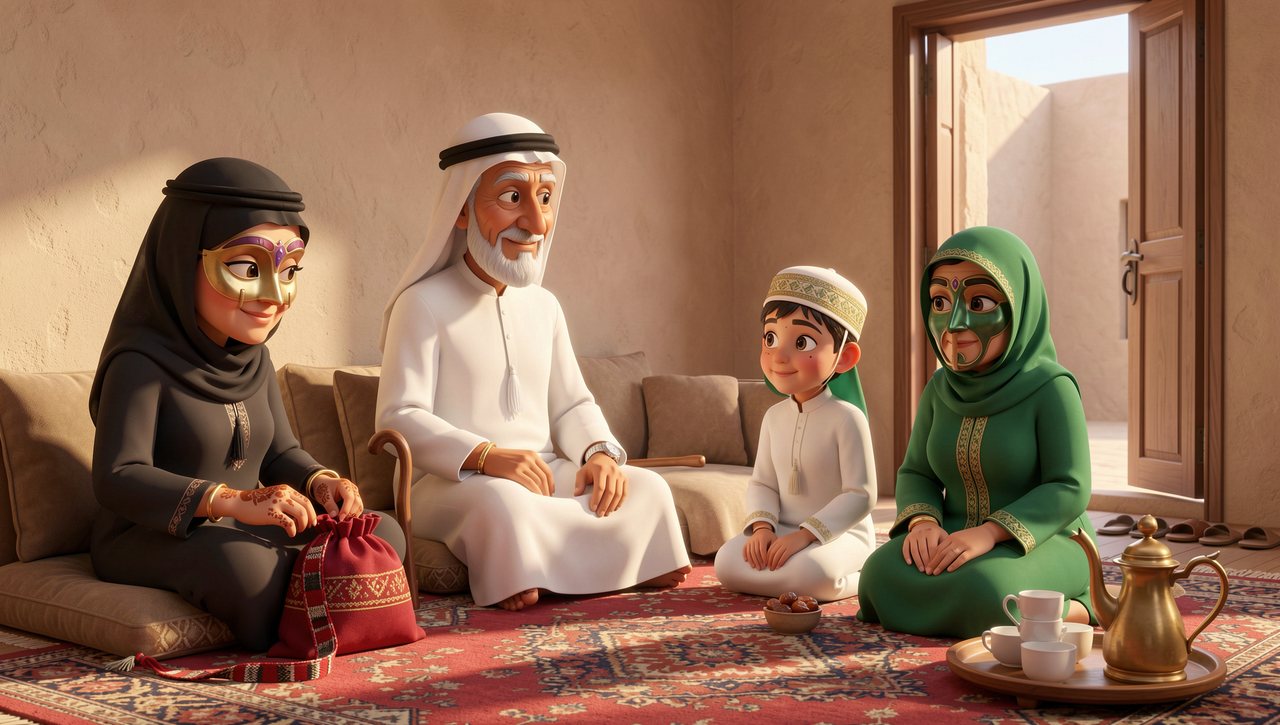
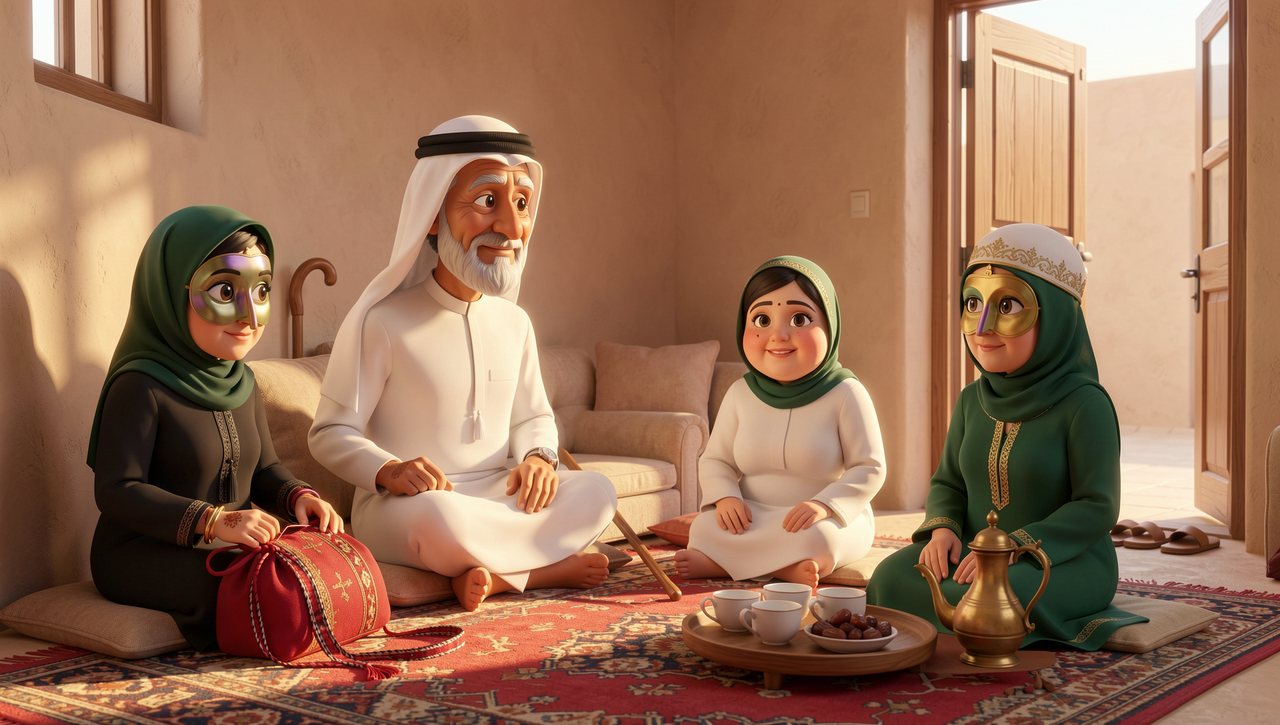
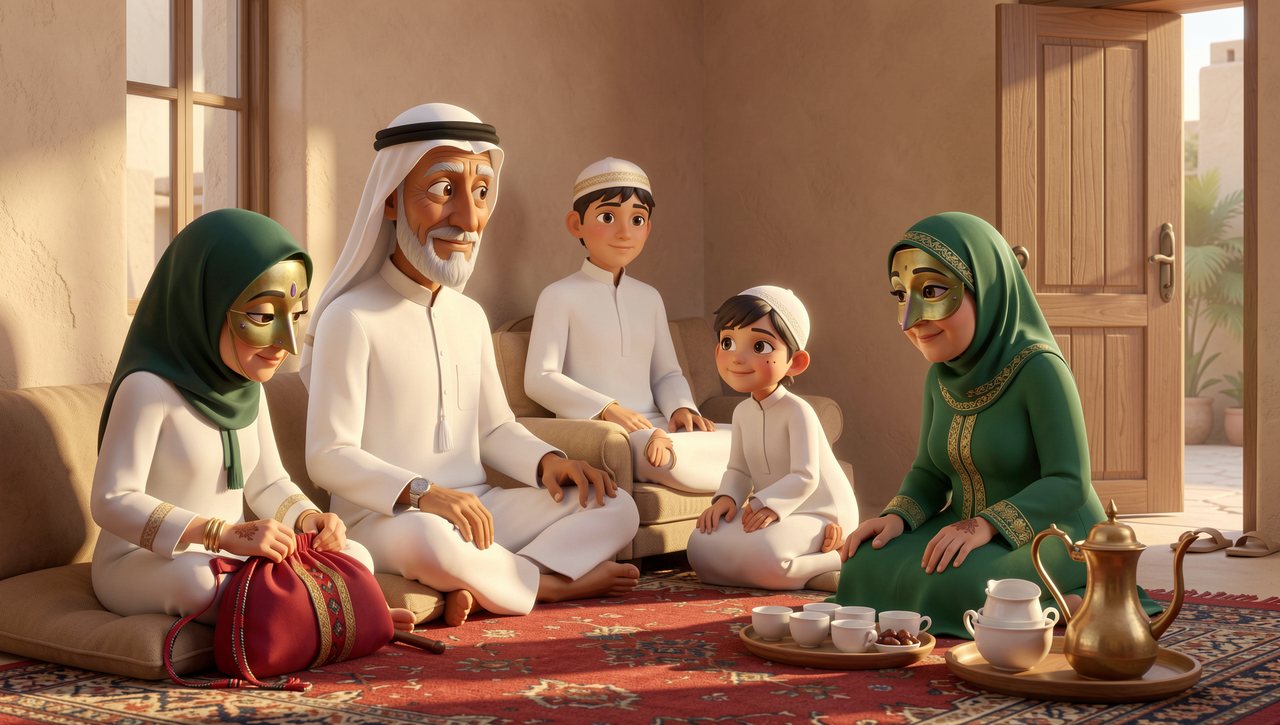
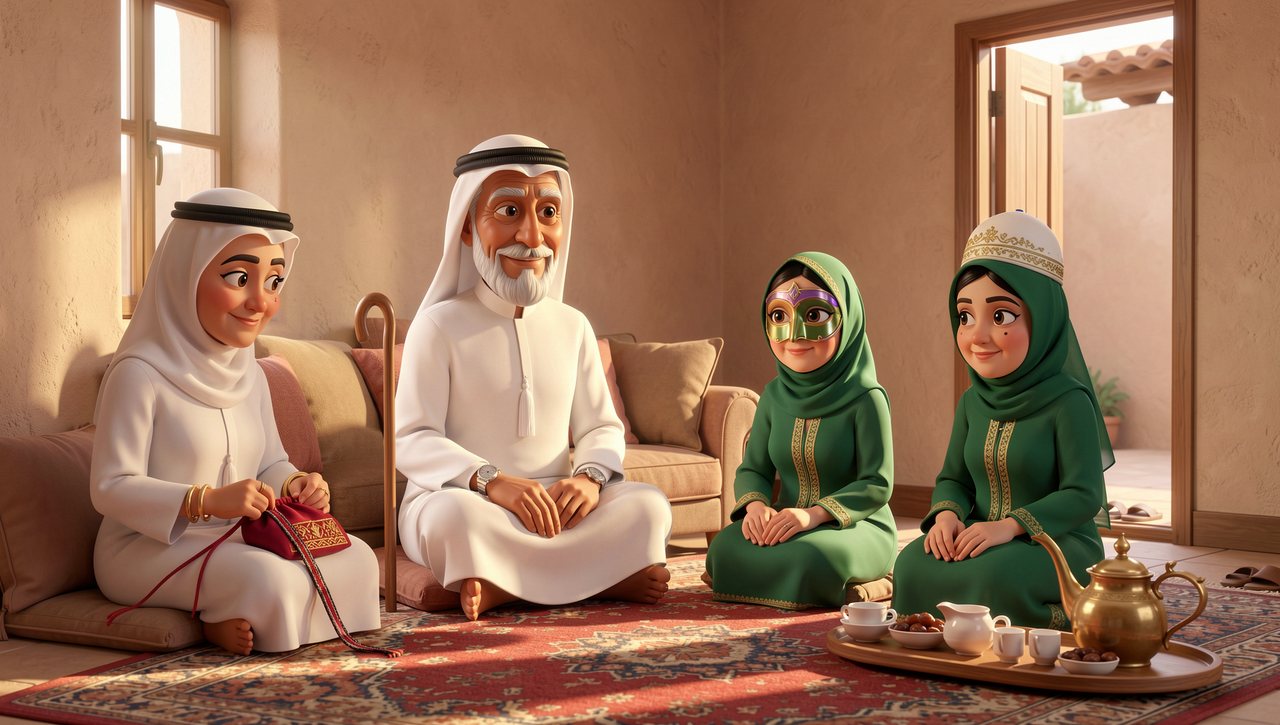
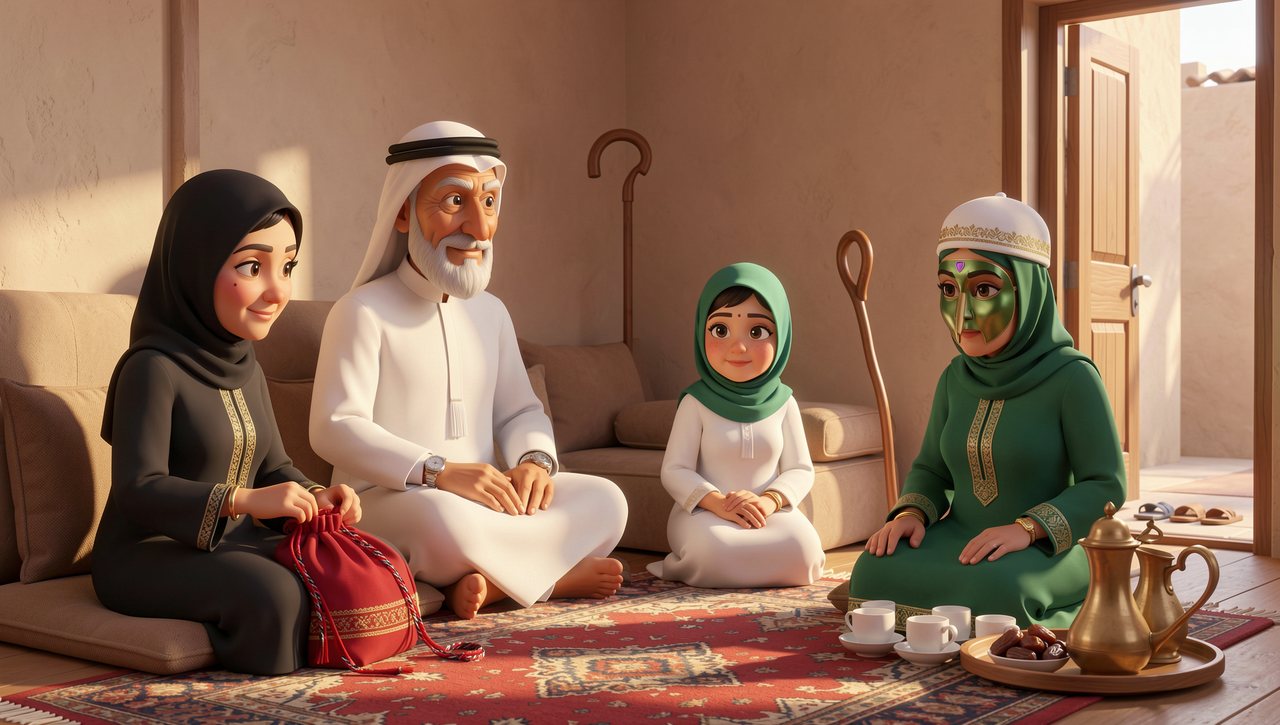
Keyframe review: All three wrong: takes 1 and 3 have five people and the battoulah on the wrong characters; take 2 has four people but Noora also wears a mask. Takes 4-6 drawn. None of takes 4-6 is right either: take 4 has five people, take 5 puts Yadda in a white head cloth and a skullcap on Noora, take 6 moves the battoulah to Noora. Picked take 2, the closest: the right four people and the battoulah on Yadda, but Noora wears a second mask.
The camera pushes in slowly toward the head of the room as asked, and Yadda sews while the others sit and look on. The keyframe's casting error carries through: Noora wears a second mask for the whole shot.
Shot 2 (6 s)
Close-up: Yadda's henna-stained fingers, gold bangles at her wrist, pull gold thread through crimson cloth to finish the last stitch of the crimson khareetah.
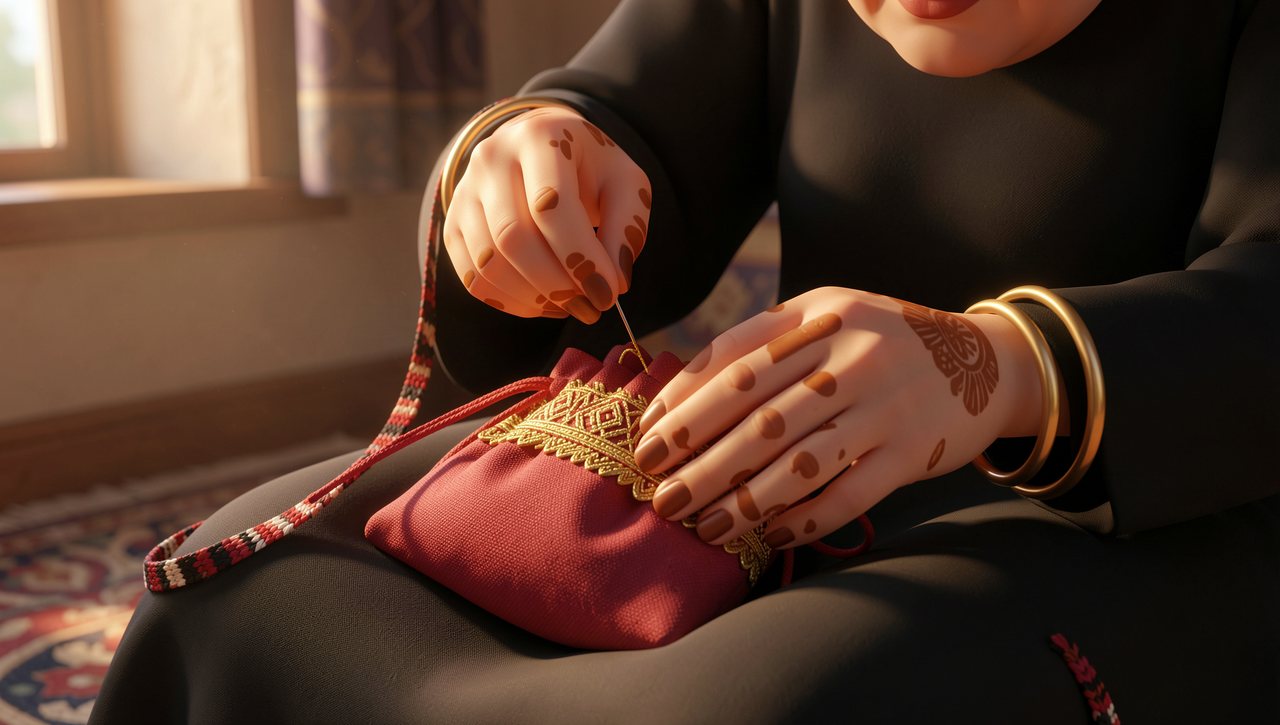
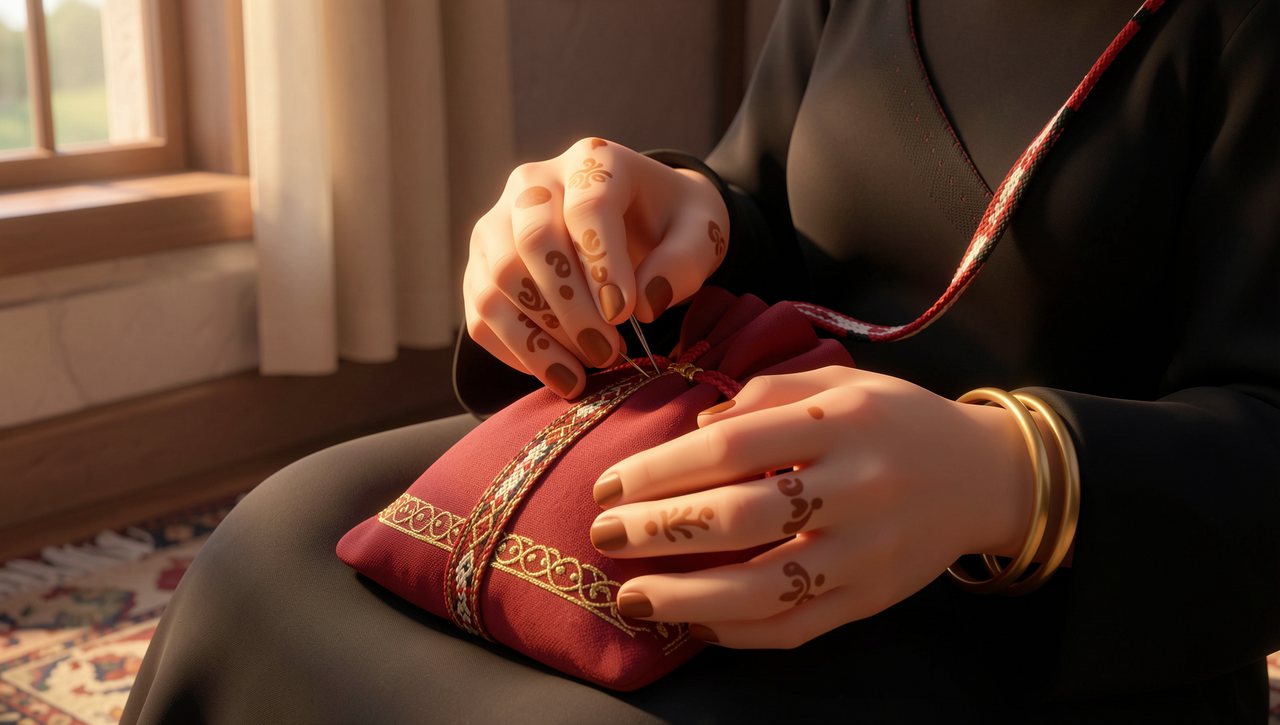
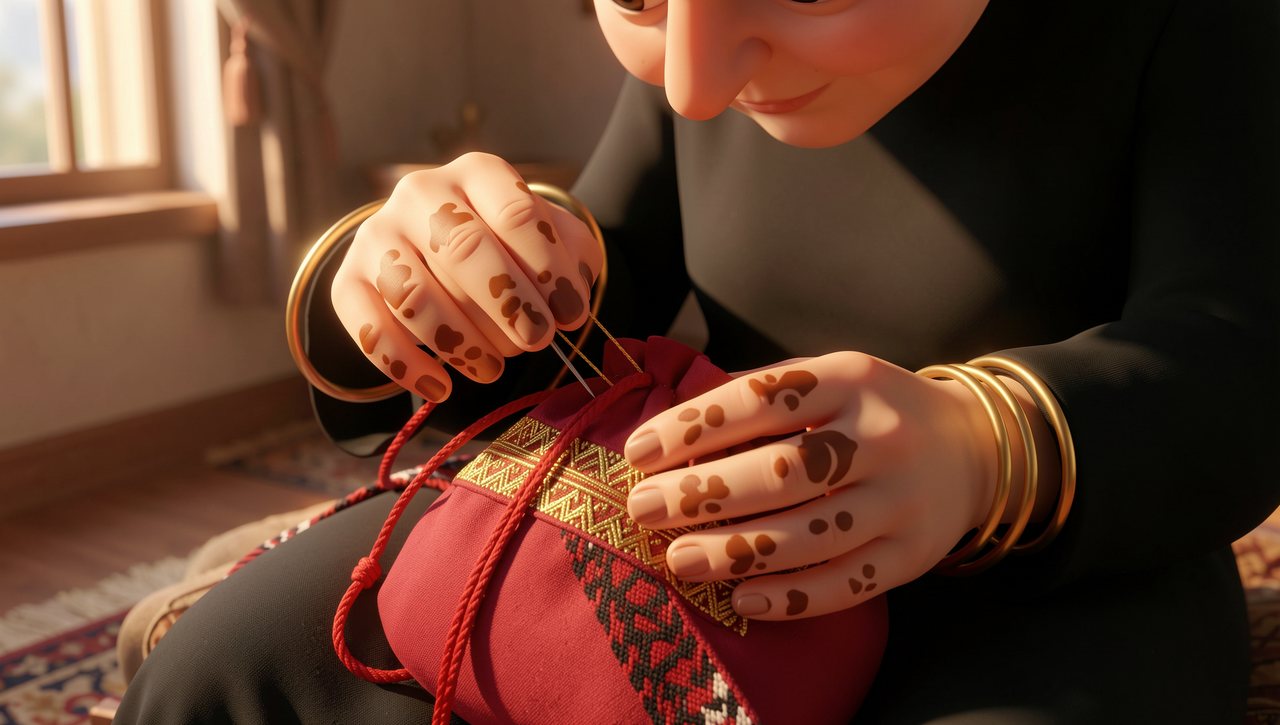
Keyframe review: Take 1: henna, bangles and the needle in her fingers. Take 3 shows Yadda's face without her battoulah.
The sewing close-up works: the henna hands draw the gold thread through the crimson cloth in small movements, the bangles catch the light, and the needle stays in her fingers.
Shot 3 (5 s): Noora
Medium close-up: Noora, kneeling beside Yadda, bounces on her knees and points at the open door. Her head covering stays in place.
يدّه، خلصتيها؟ عيال الفريج طلعوا!
Yadda, is it done yet? All the kids are out!
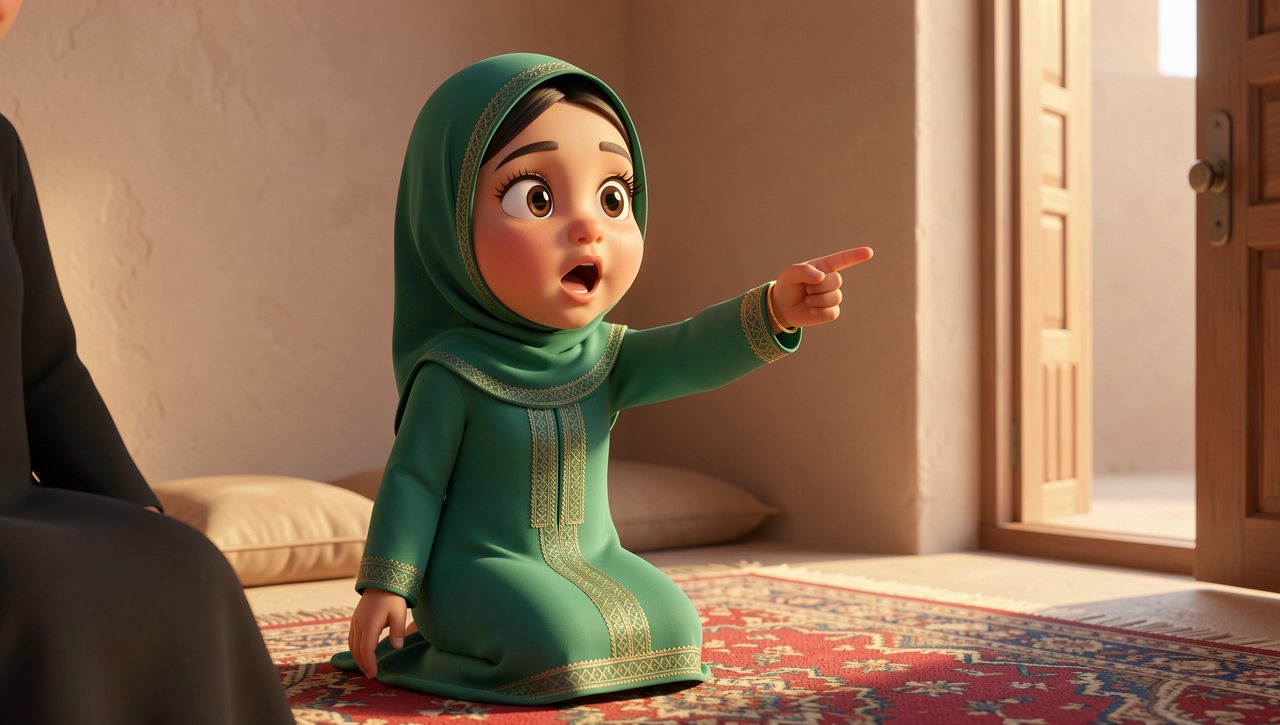
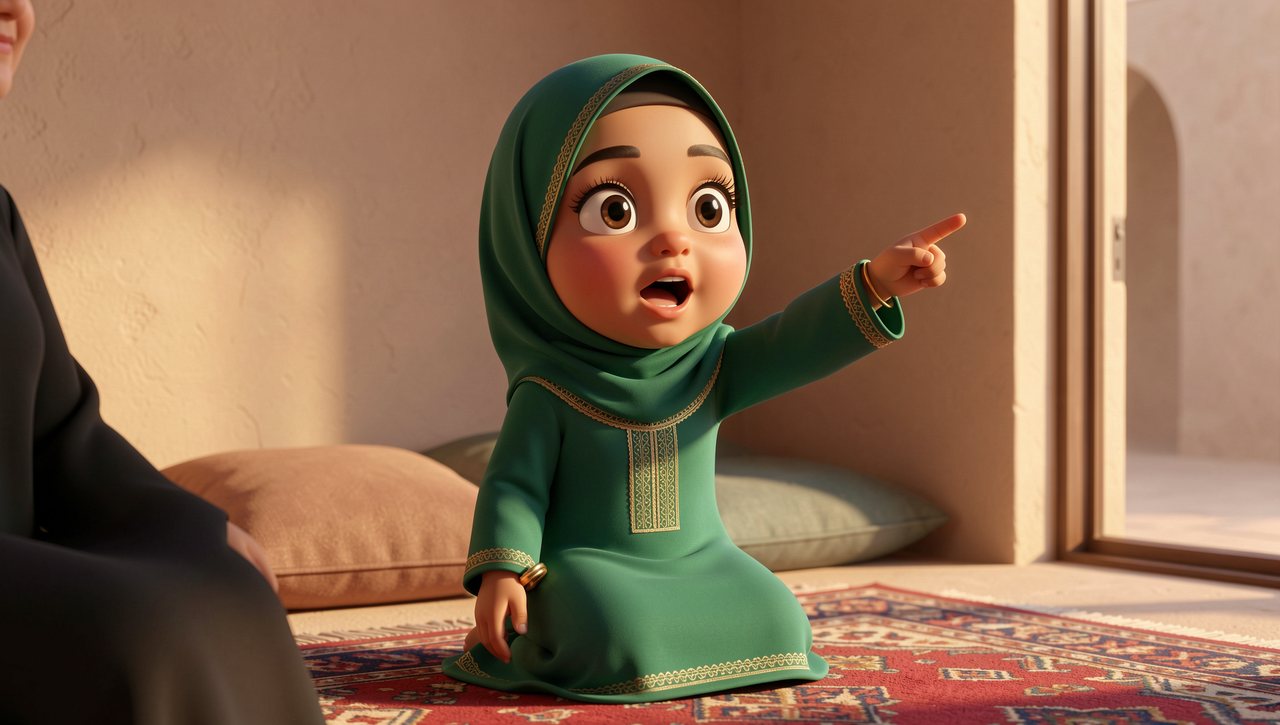
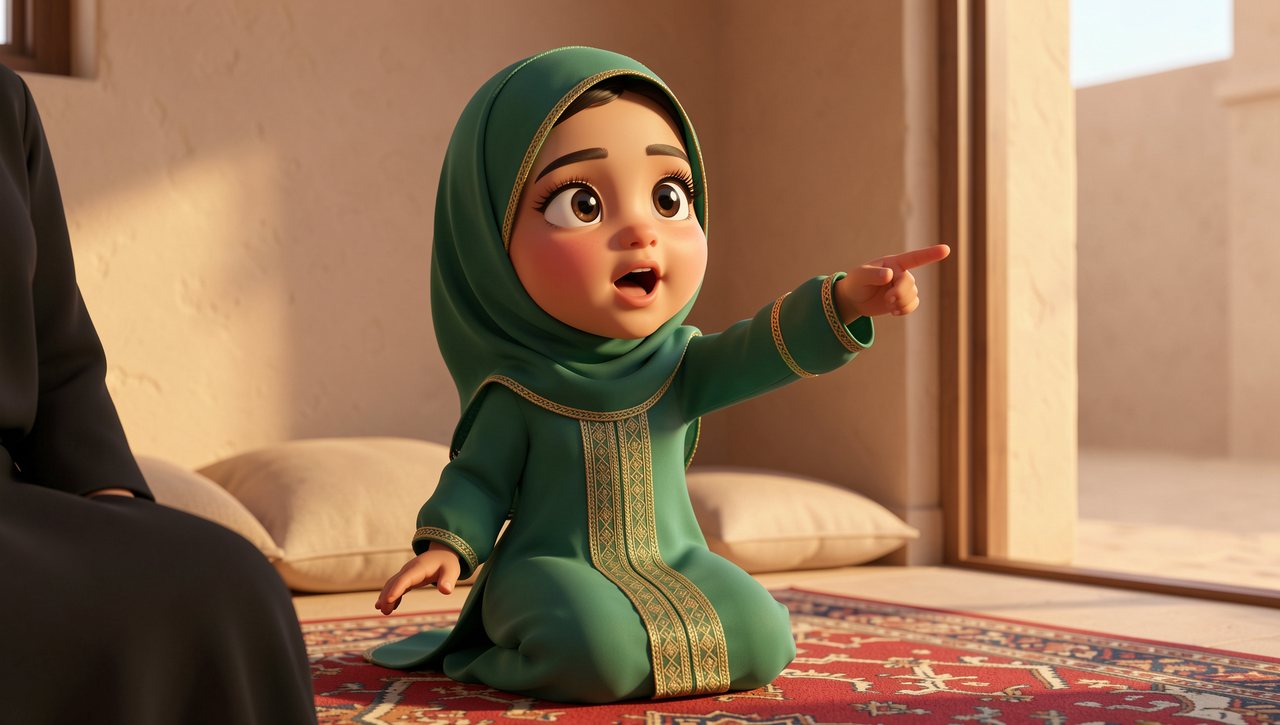
Keyframe review: Take 2: clear point toward the open door. A little of Noora's hair shows at the forehead in all three takes.
Noora bounces, points at the door and calls out her line. With the voice held, her mouth moves with each language's line and closes where it ends, a little after 2 s in English and after 3 s in Arabic.
Shot 4 (9 s): Yadda
Medium close-up: Yadda ties off the thread in her lap and holds the finished crimson khareetah out to Noora with her right hand.
خلصت. خيّطتها لج من ثوبي، يوم كنت صغيرة قدّج.
All done. I sewed it for you from the dress I wore when I was your size.
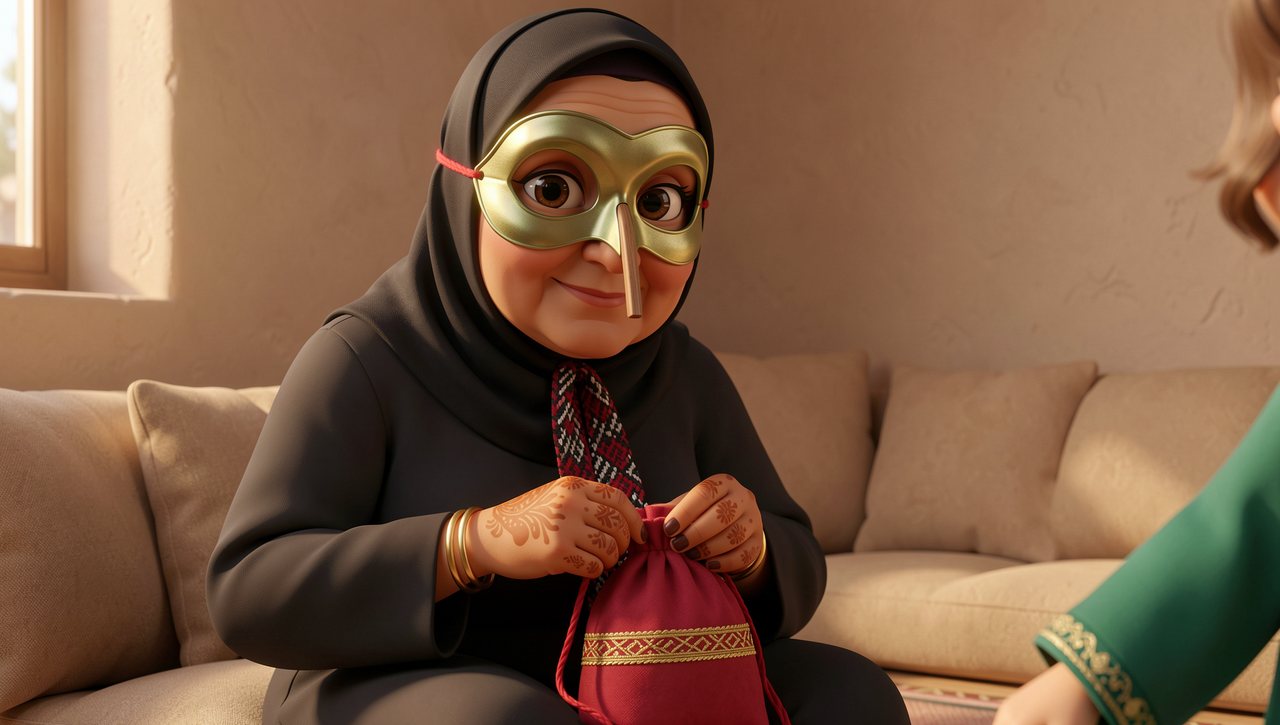
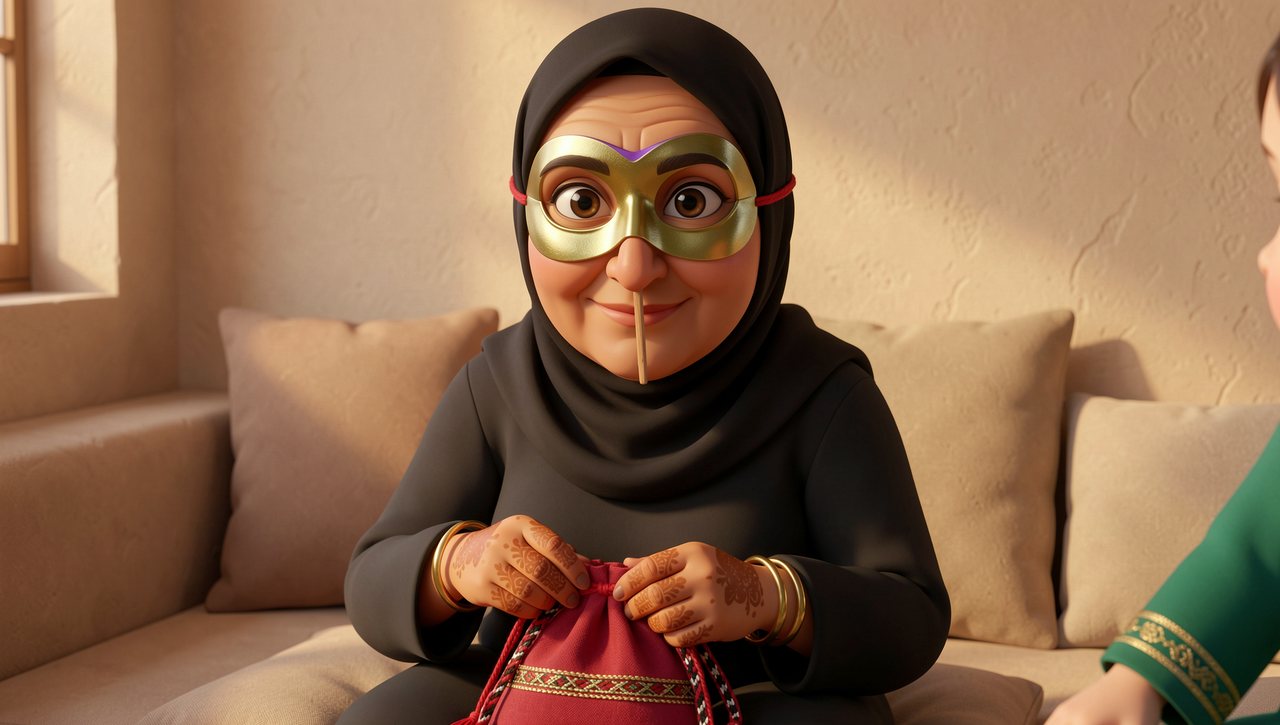
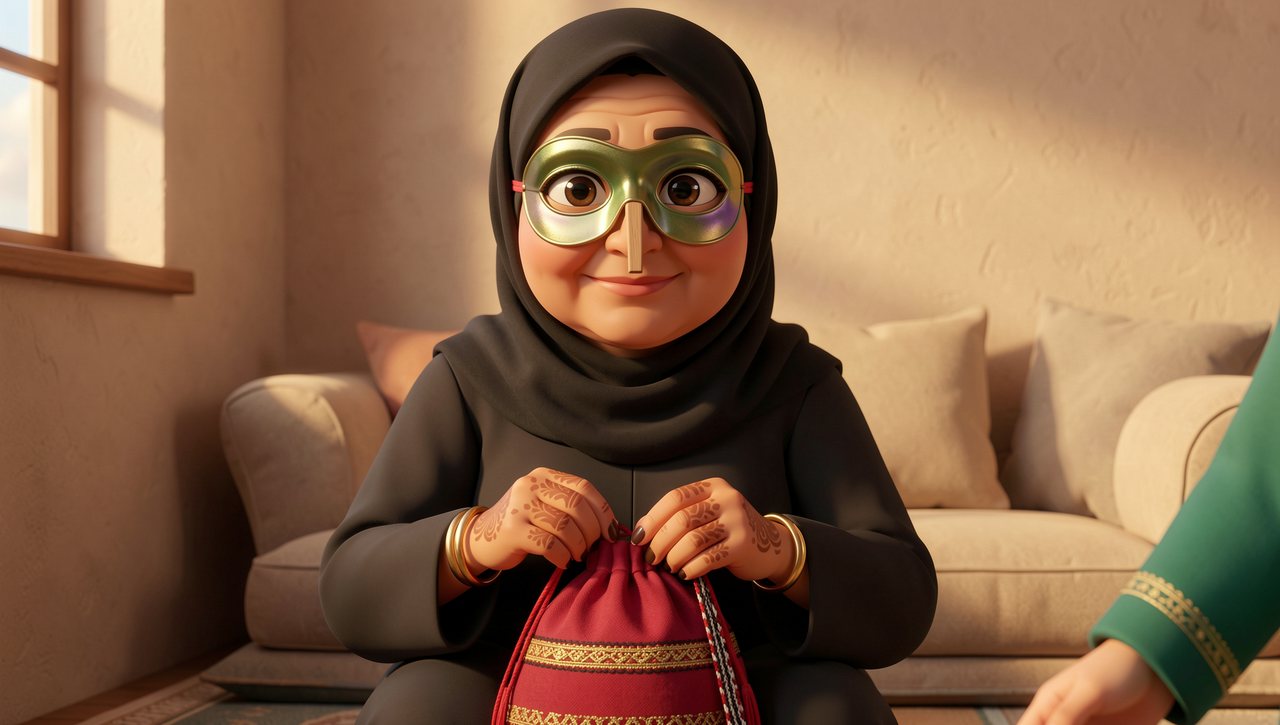
Keyframe review: Take 3. Every take draws the battoulah as an eye mask with a rib down the nose; in take 2 the rib runs past her mouth, which would block the lip sync. A sofa stands in for floor cushions in all three.
Yadda finishes the bag, talks as she lifts it, and holds it out to Noora's green sleeve at the right edge; her mouth stays clear of the mask. The shot is meant to be fixed, but the camera moves in to her face over the last seconds, and the two languages differ visibly through the whole shot.
Shot 5 (5 s): Noora
Close-up: Noora takes the bag with her right hand and hugs it to her chest, dimples showing.
وايد حلوة! مشكورة يا يدّه.
It's so pretty! Thank you, Yadda!
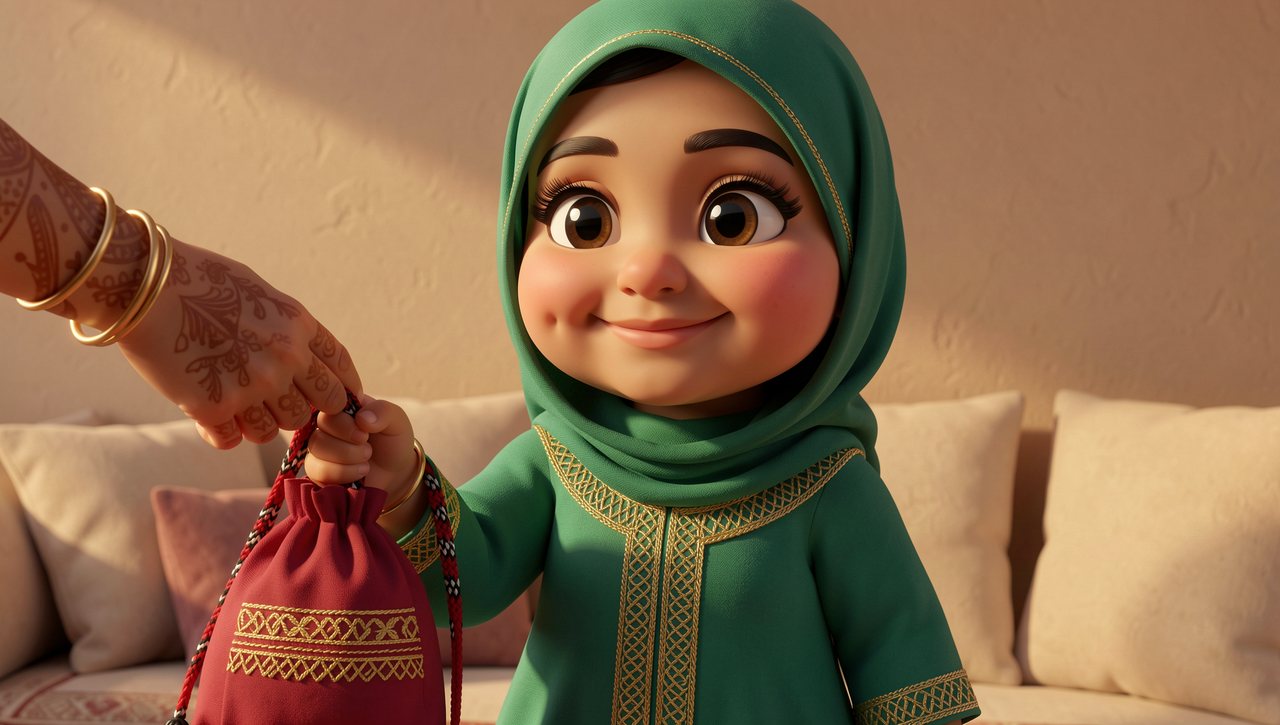
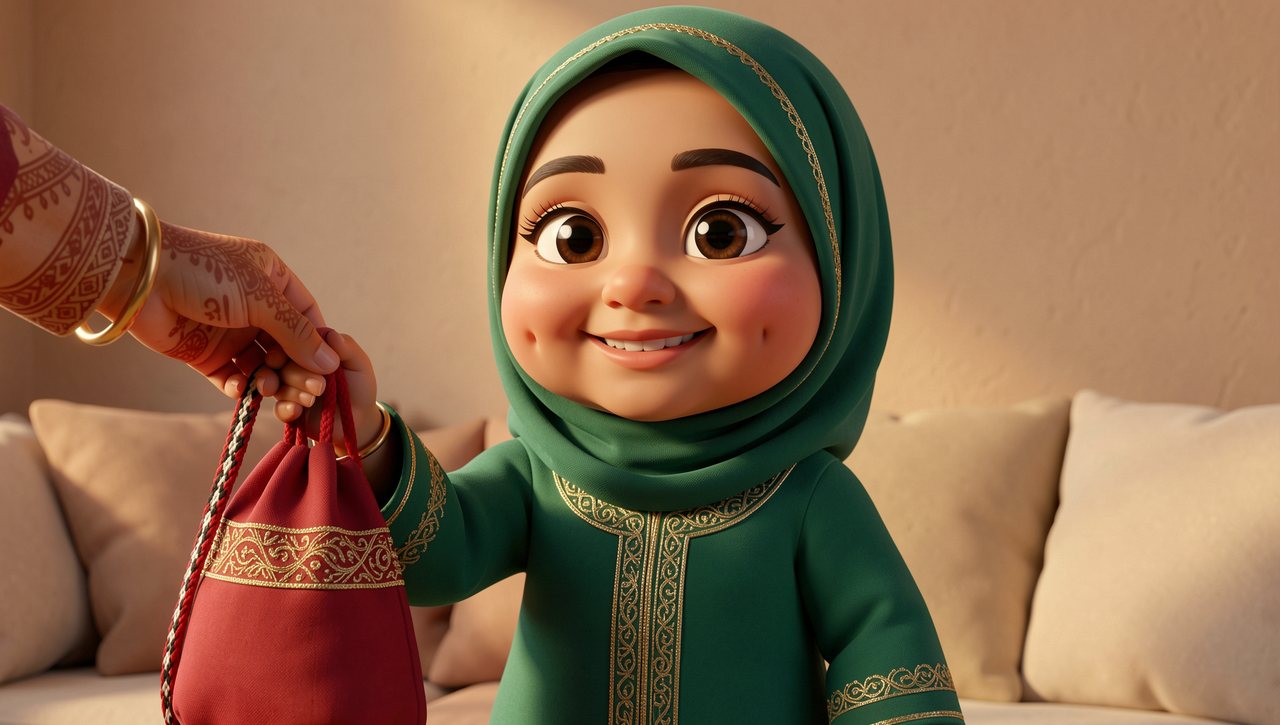
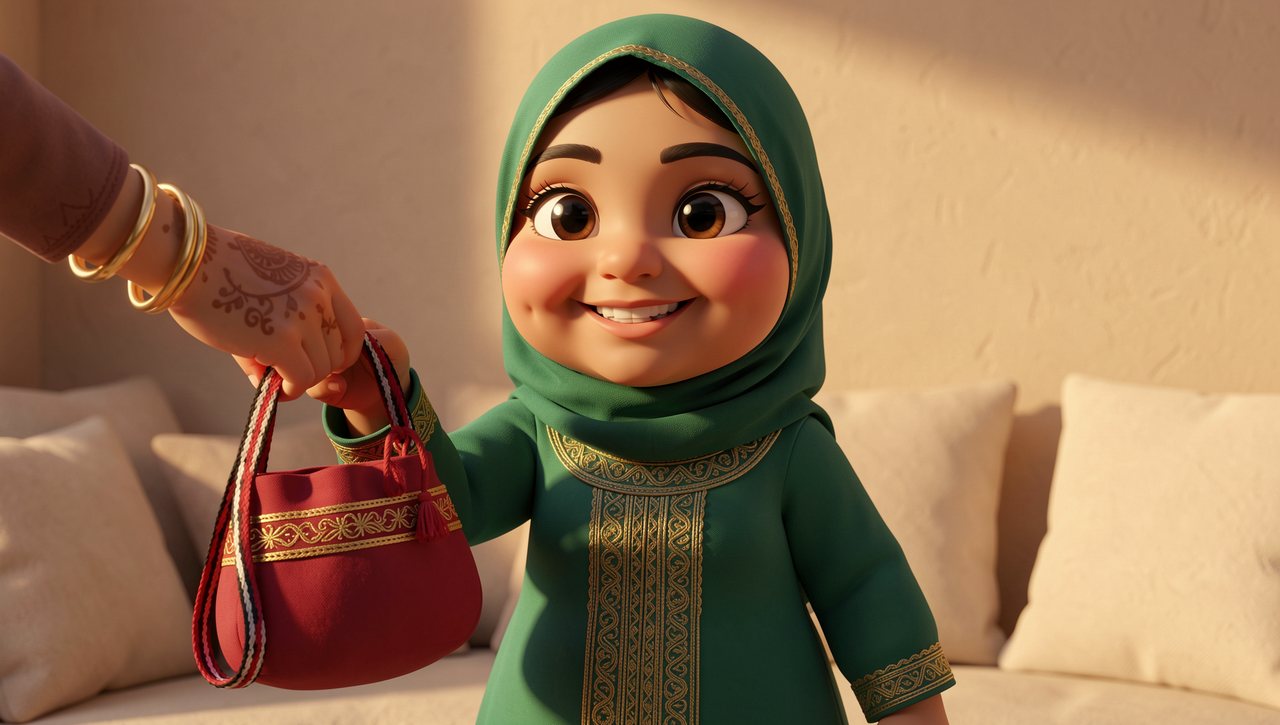
Keyframe review: Take 2: dimples, and both hands on the bag as it passes.
Noora takes the crimson bag from Yadda's henna hand, hugs it to her chest and says her thank-you with a dimpled smile, in both languages. Her cheeks break out in small red spots as the clip goes on, a skin texture the keyframe did not have.
Shot 6 (9 s)
Medium shot, the coffee pour. Salem stands beside the seated Yaddi, the brass dallah in his LEFT hand with his thumb on top of the handle and a stack of white finjans in his RIGHT. He pours a small splash of pale golden-brown coffee, about a quarter of the cup, and offers it. Yaddi takes it with his RIGHT hand.
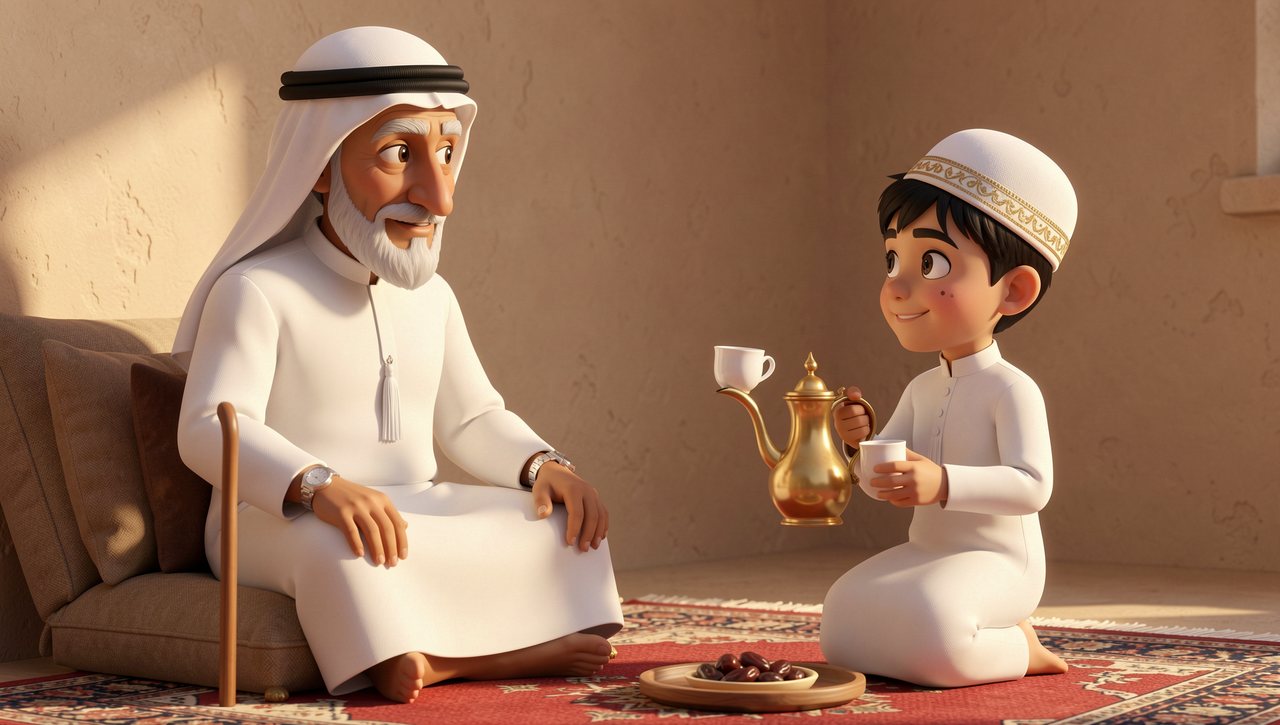
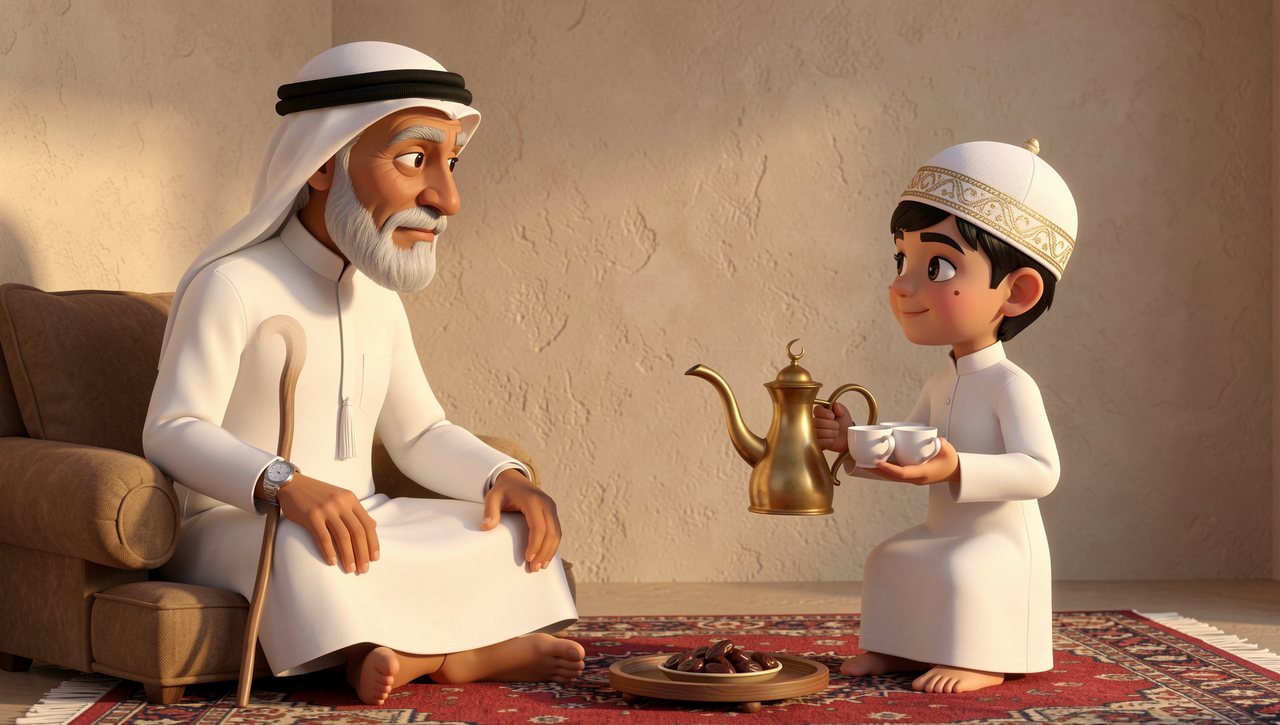
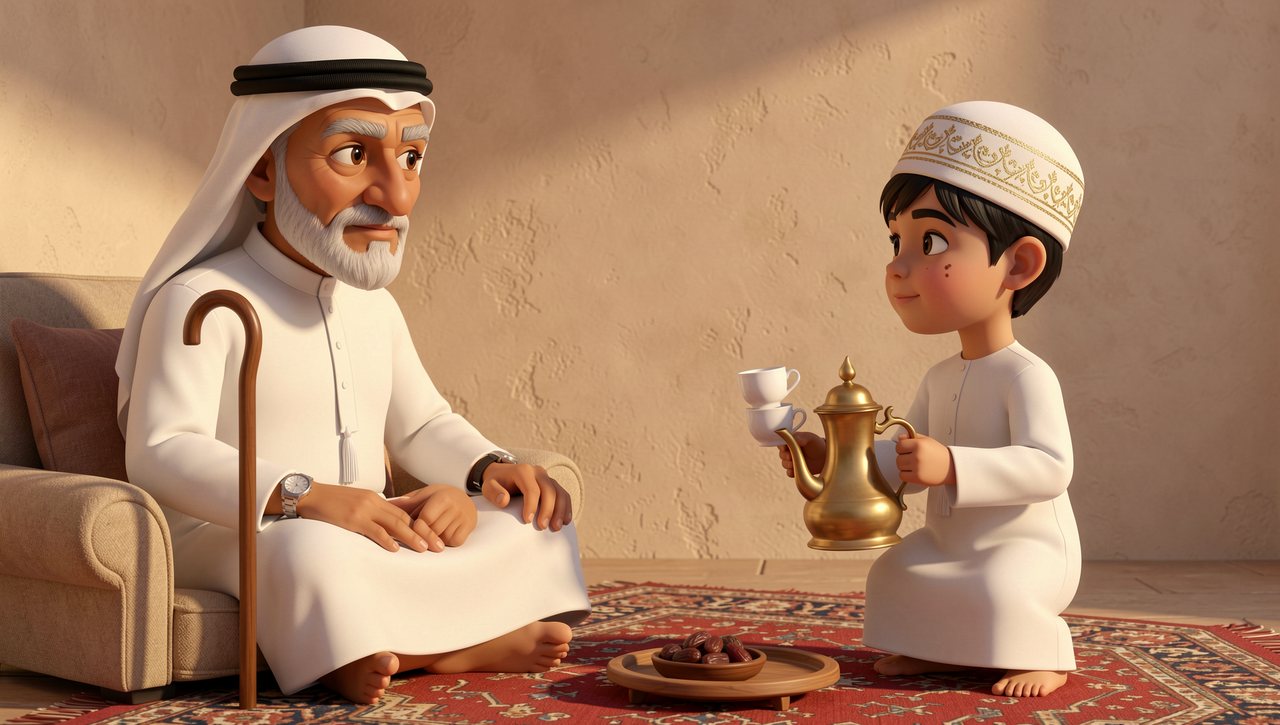
Keyframe review: Take 1: the only take with Yaddi on a floor cushion rather than an armchair. Salem kneels instead of standing in all three.
The coffee pour works: Salem tips the dallah, a thin stream of coffee fills the small cup, and Yaddi reaches over and takes it, with both faces steady through all 9 seconds. Salem kneels instead of standing, as he did in the keyframe.
Shot 7 (5 s): Yadda
Medium shot: Yadda smiles across the room and holds up a second bag, the indigo khareetah.
وإنت يا سالم، خريطتك ياهزة.
And you, Salem, your khareetah is ready.
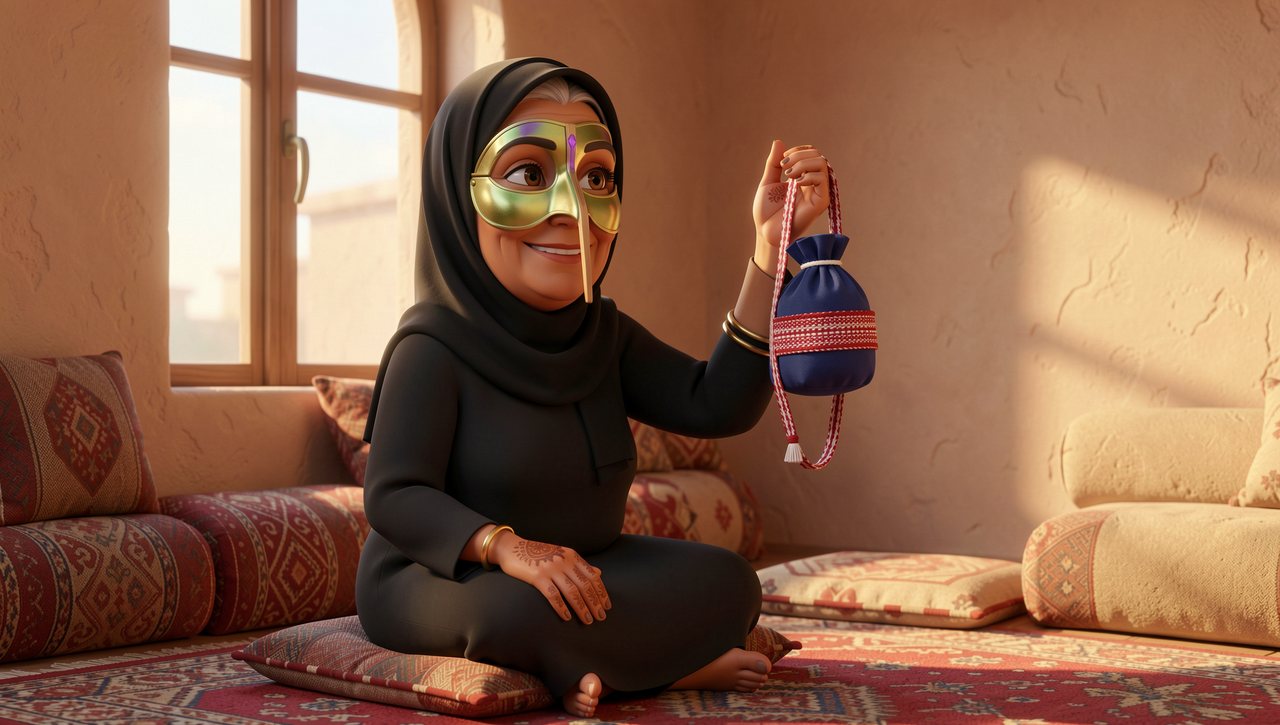
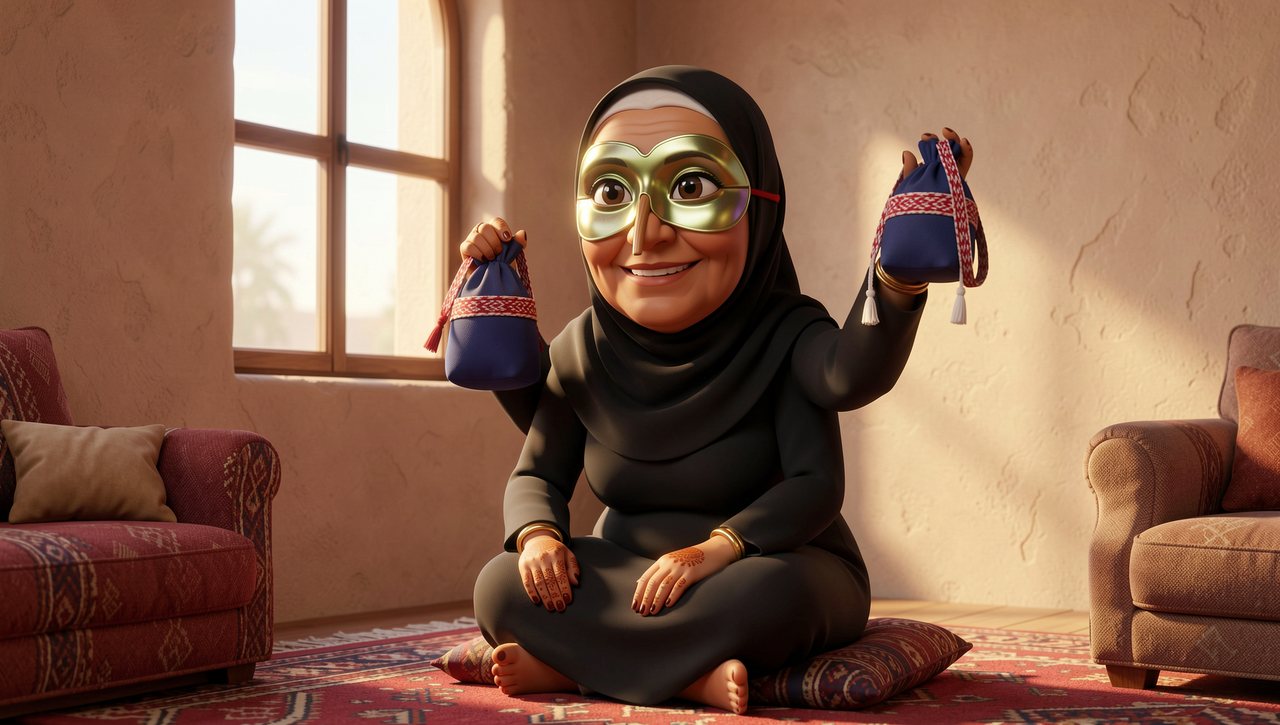
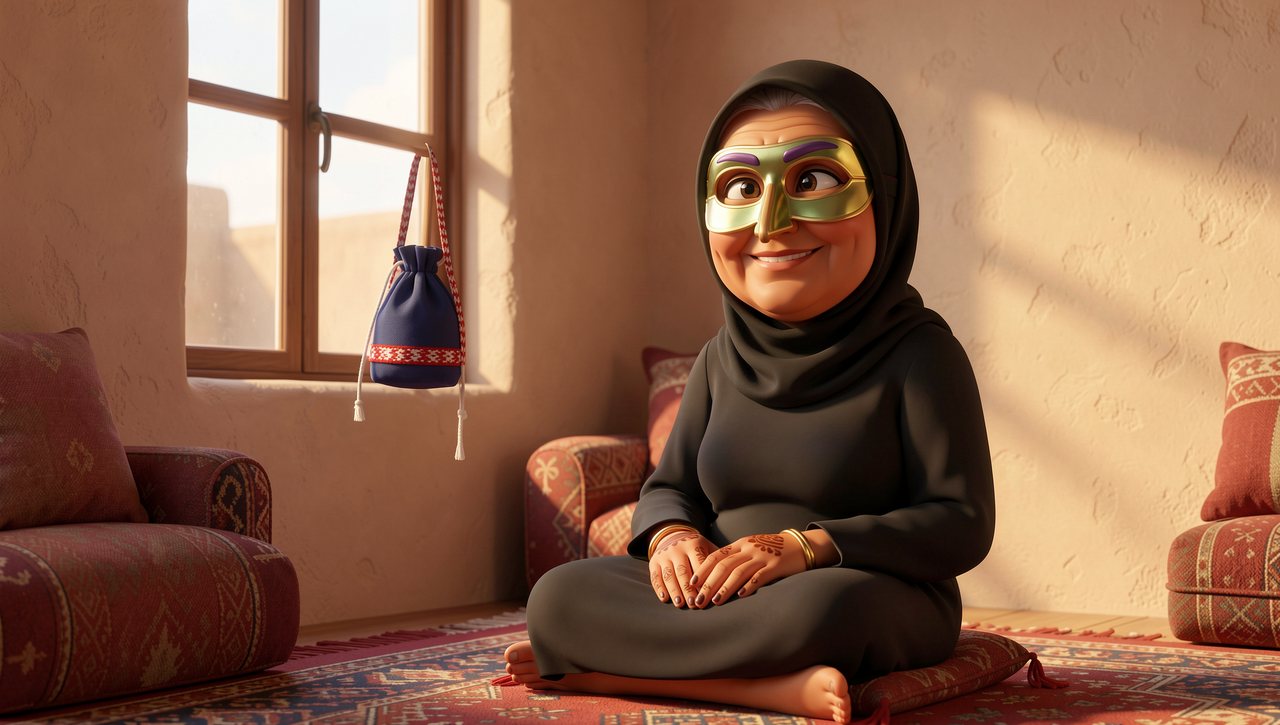
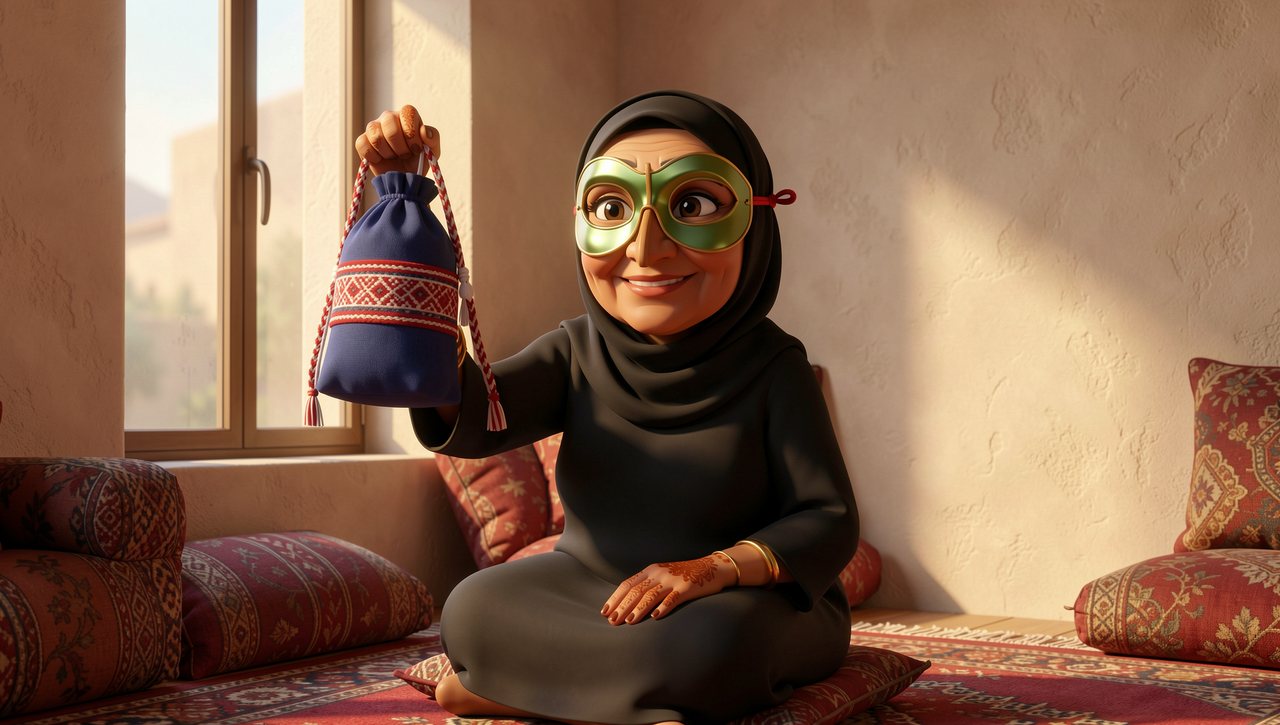
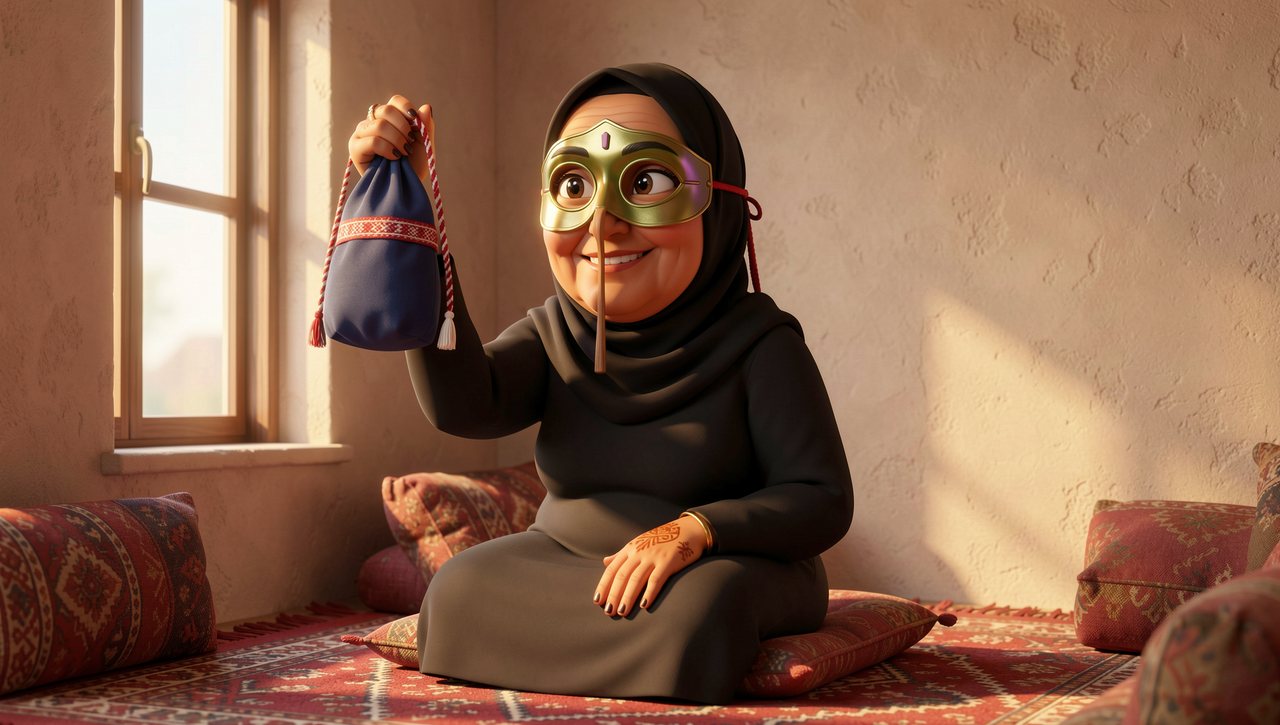
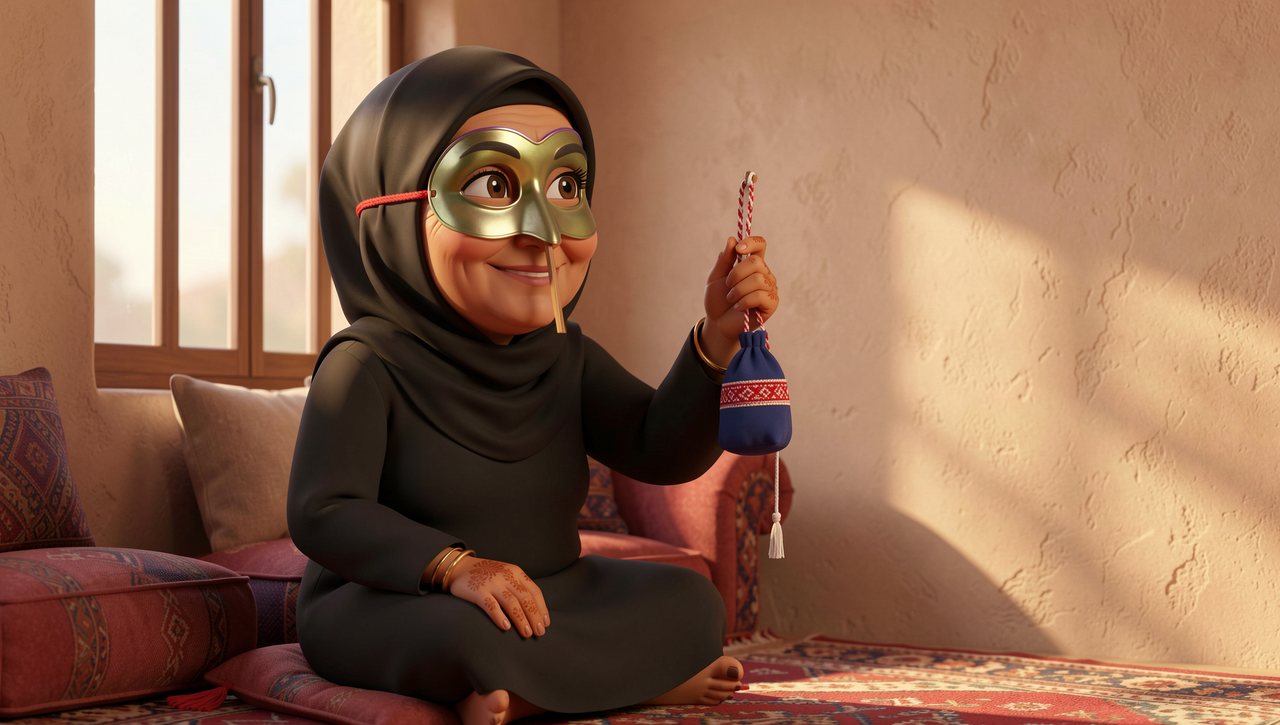
Keyframe review: All three wrong: in take 1 the battoulah rib crosses her mouth on a spoken line, take 2 holds two indigo bags, take 3's bag floats in the air. Takes 4-6 drawn. Picked take 4: one indigo bag held up, and the mask leaves her mouth clear.
Yadda lifts the indigo bag toward Salem, smiles and speaks with her mouth fully visible, since this take's mask has no rib across her lips. A simple shot that works.
Shot 8 (8 s): Salem
Medium close-up: Salem, still standing with the dallah, lifts his chin to look grown-up and does not look at the bag.
أنا ما بطلع يا يدّه. كبرت على حق الليلة. بقعد ويا يدّي.
I'm not going, Yadda. I'm too grown-up for Hag Al Laila. I'll stay with Yaddi.
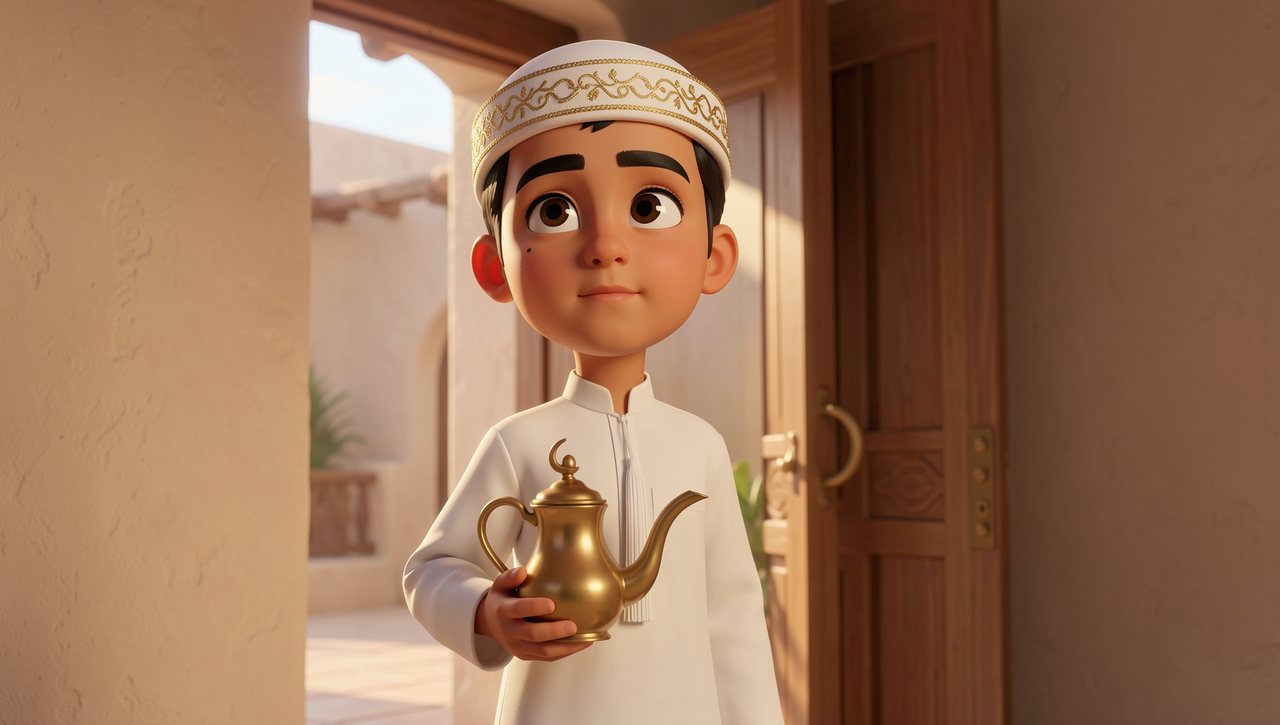
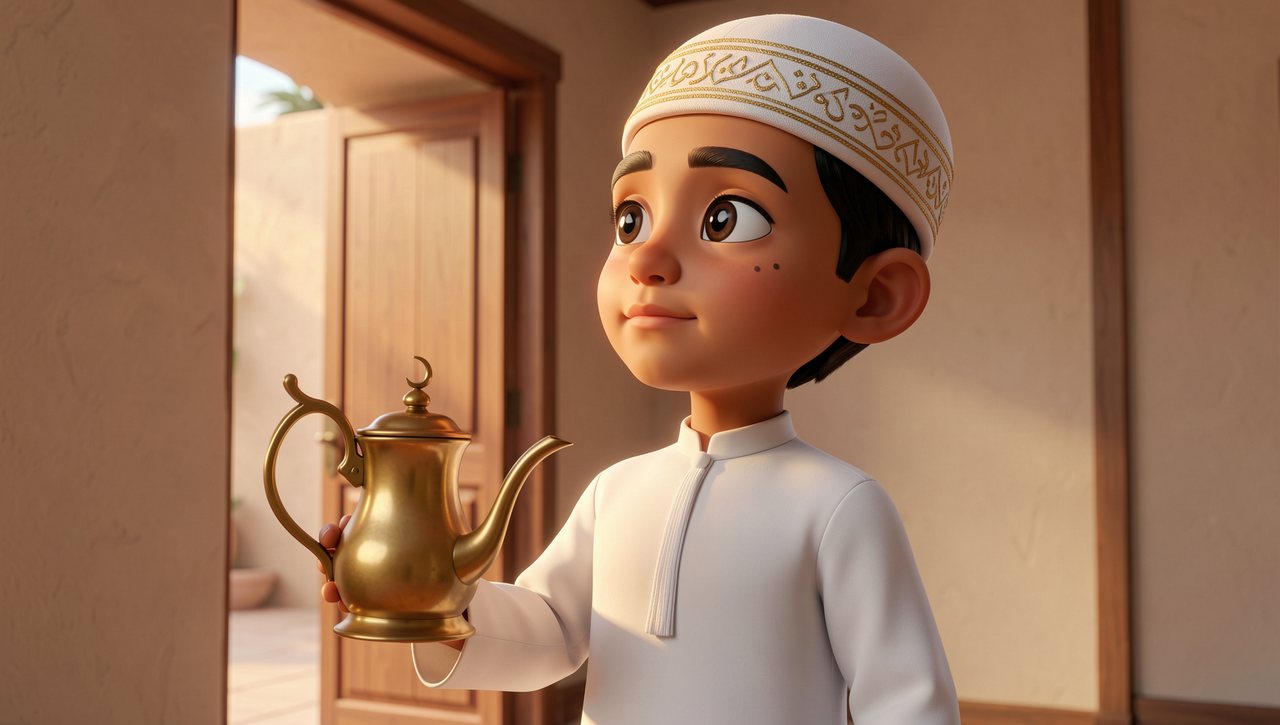
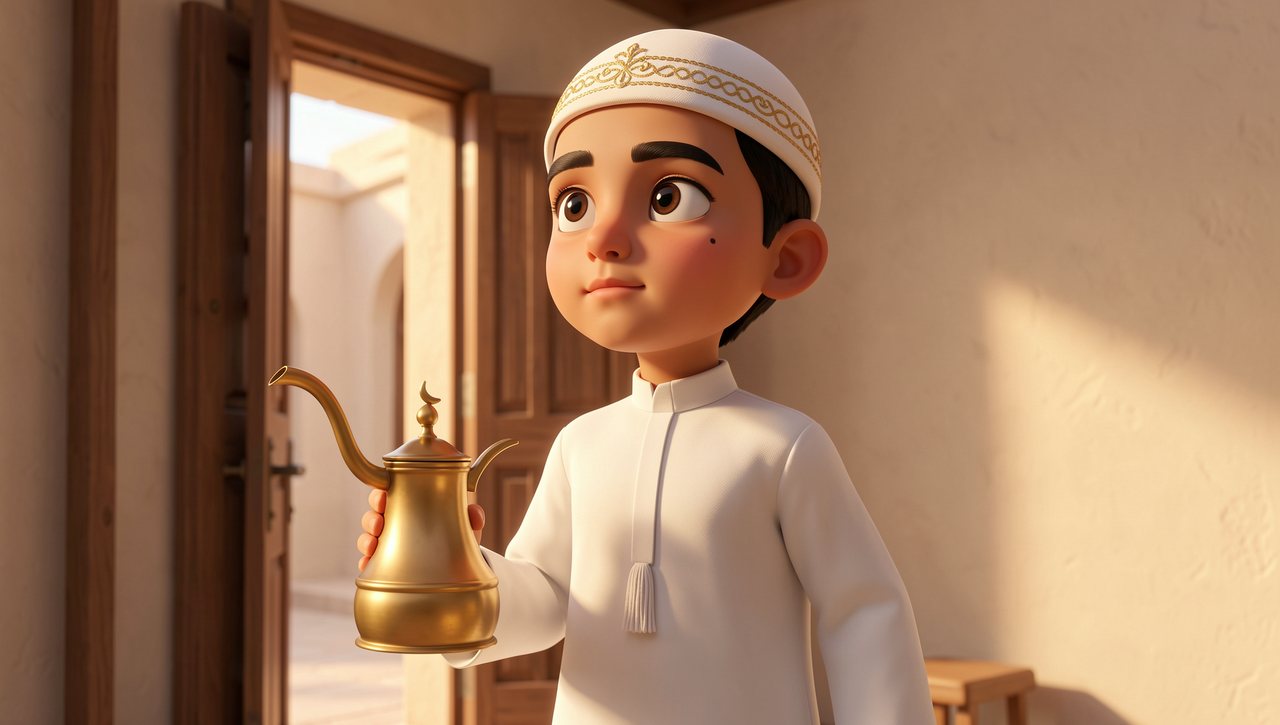
Keyframe review: Take 3: chin up, dallah in hand, clean face. Take 1 has a red ear.
Salem talks through his line with clear mouth movement and then closes his mouth and holds his grown-up frown for the rest of the shot, in both languages, which is exactly the timing of the voice tracks. A clean, steady clip.
Shot 9 (5 s): Noora
Close-up: Noora's smile fades, and her fingers twist the red drawstring of the crimson khareetah.
بس أنا أستحي أغنّي بروحي.
But I'm too shy to sing by myself.
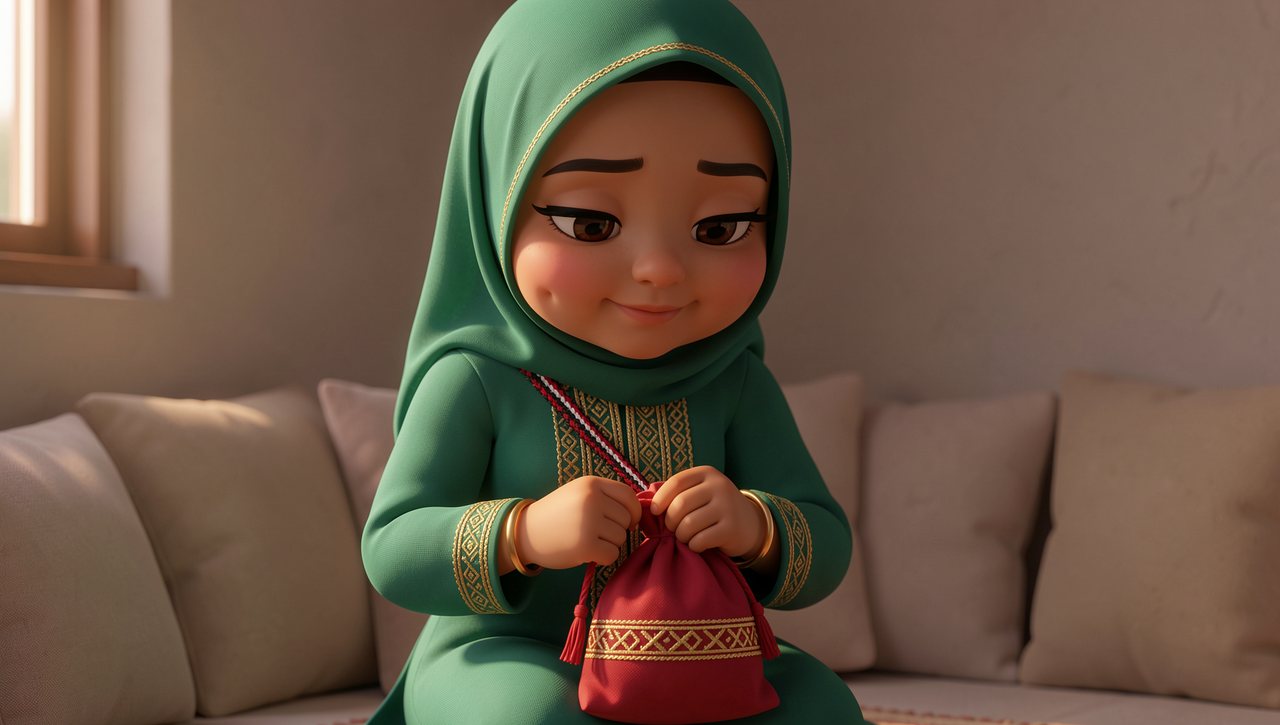
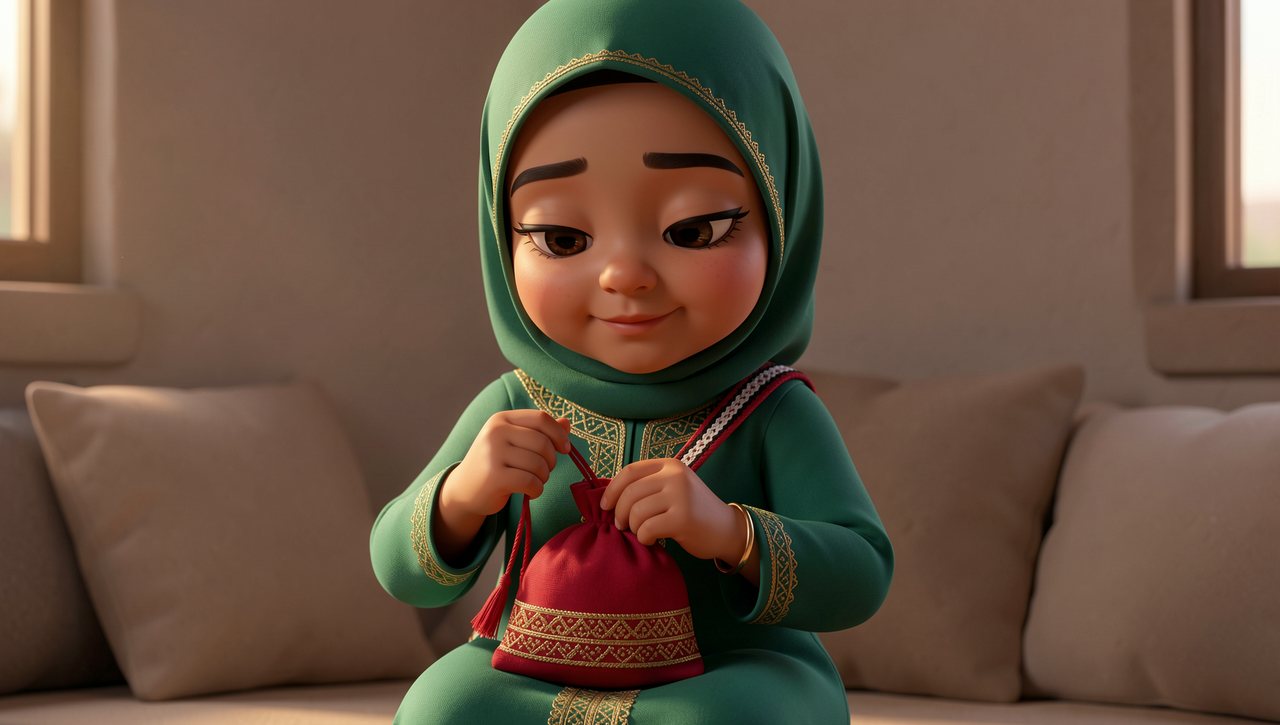
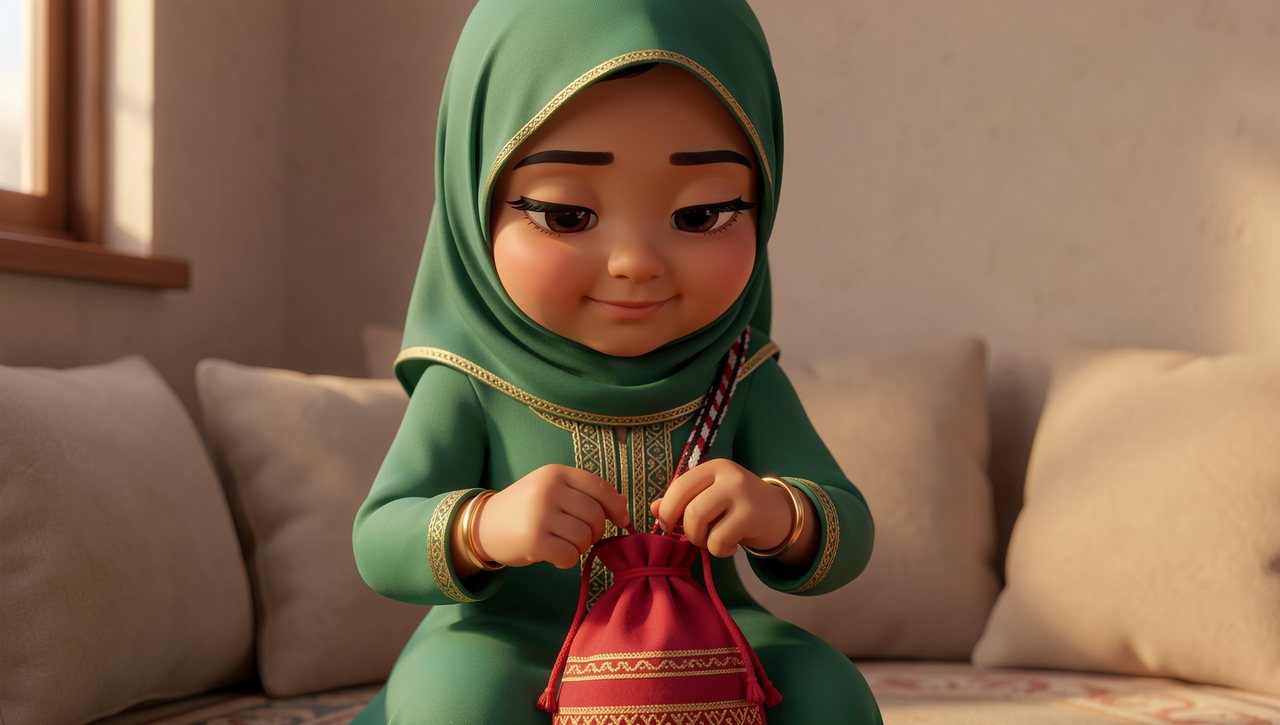
Keyframe review: Take 2: eyes lowered, no hair showing. Her smile has not quite gone in any take.
Noora twists the drawstring, glances up and says her shy line; the two languages act it differently, a small smile in Arabic and a hesitant rounded mouth in English. The camera pushes in to a close-up where the shot asks for only a very slight move.
Shot 10 (10 s): Yaddi
Medium shot: Yaddi gives his empty finjan a small, gentle side-to-side shake to say 'enough' and hands it back with his right hand; Salem takes it onto the stack of finjans in his right hand. Yaddi takes up his walking stick and begins to rise.
تسلم يمينك يا ولدي. يلّا يا نورة، أنا بمشي وراج.
Bless your hands, my boy. Come, Noora. I'll walk behind you.
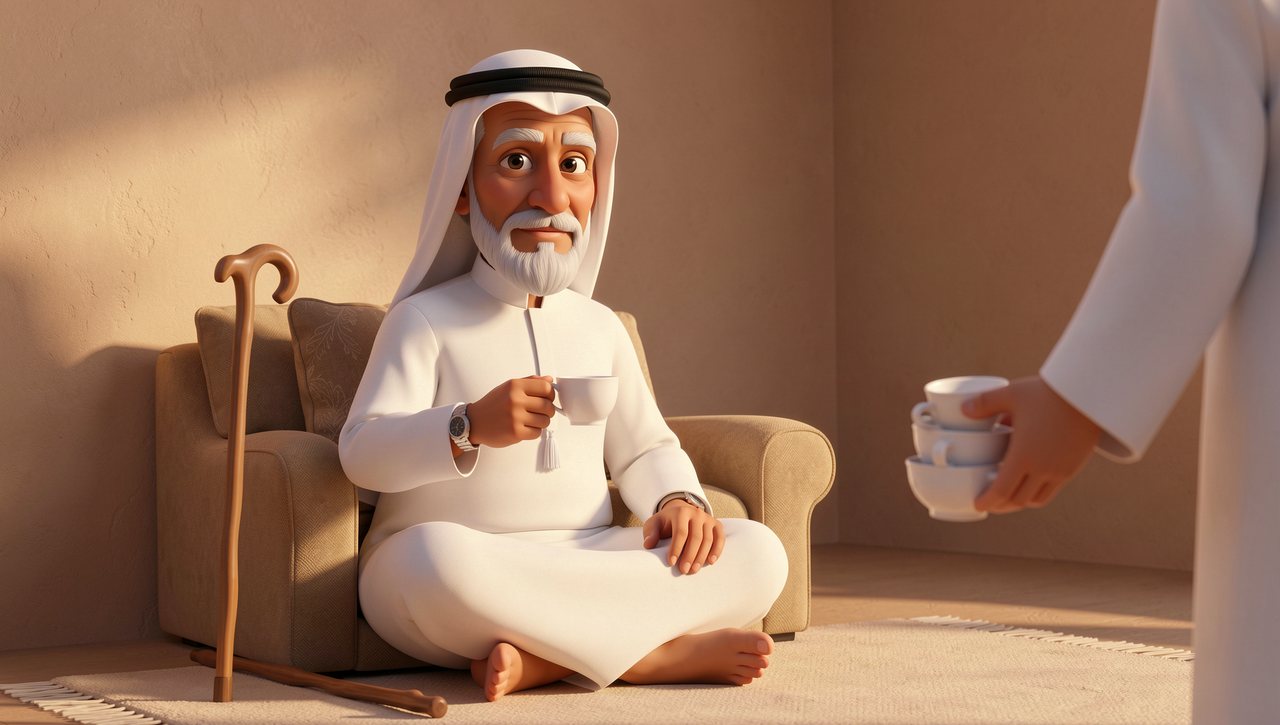
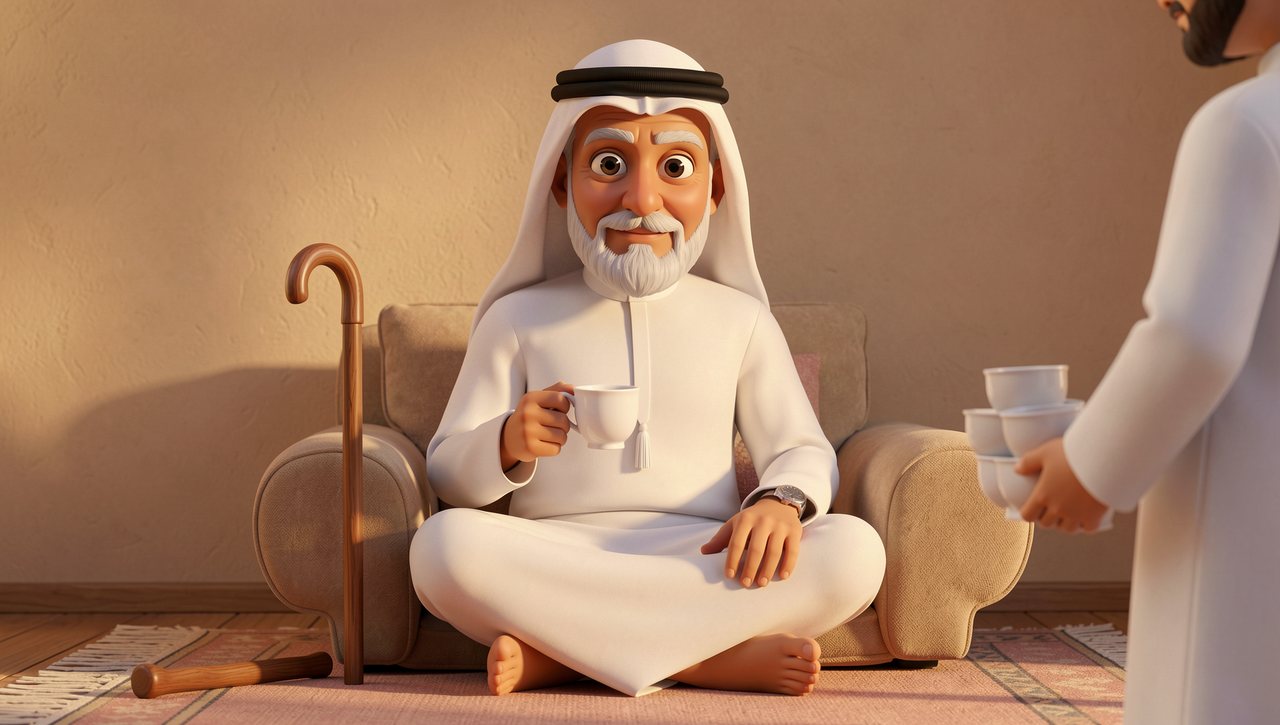
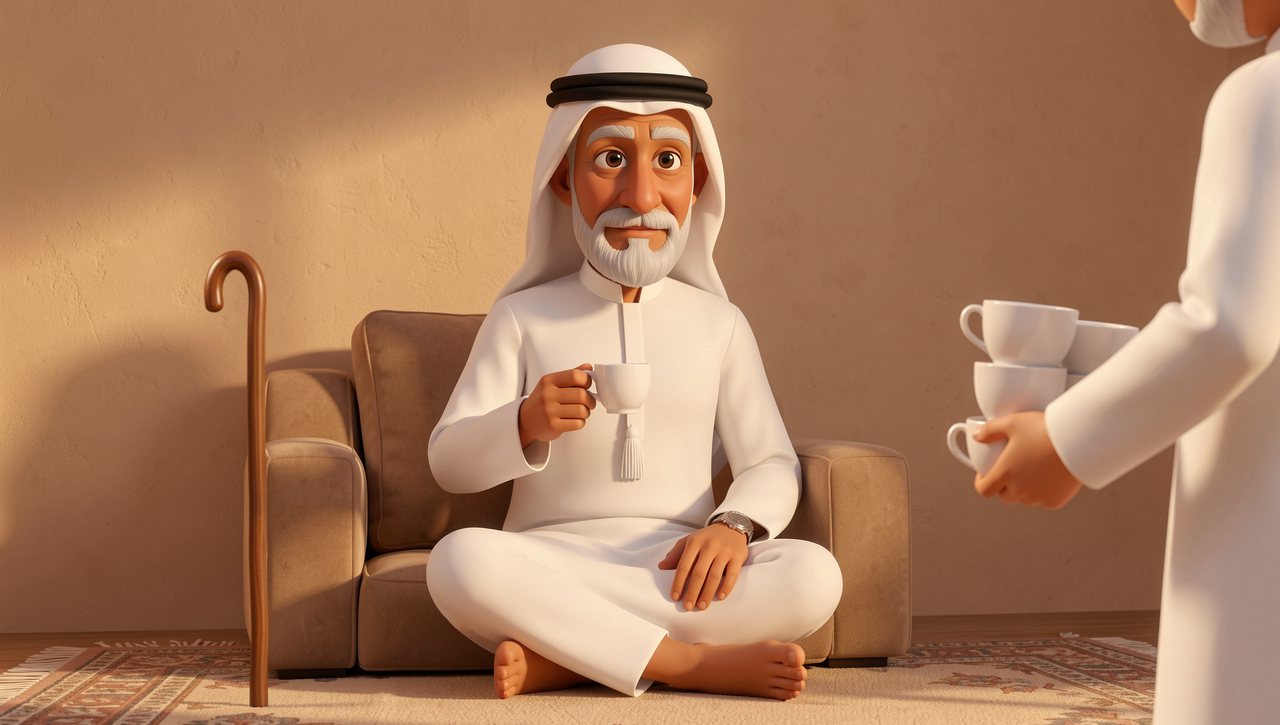
Keyframe review: Take 1. Take 2 gives Yaddi two canes and puts a bearded adult where Salem should be. Take 1 has a second stick lying on the floor.
Yaddi talks over the cup in the first four seconds, gives it back, takes his stick and rises, as the script asks, in both languages. Two defects: the arm taking the cup belongs to an adult in a white kandura and ghutra rather than nine-year-old Salem, and as Yaddi stands the framing jumps to a new angle, a cut inside the clip that nobody asked for.
Shot 11 (8 s)
Wide shot, golden hour, long shadows in the fereej lane. Noora walks ahead in sandals holding the flat, empty crimson khareetah, and Yaddi follows a few steps behind with his walking stick. Children's voices are heard far away.
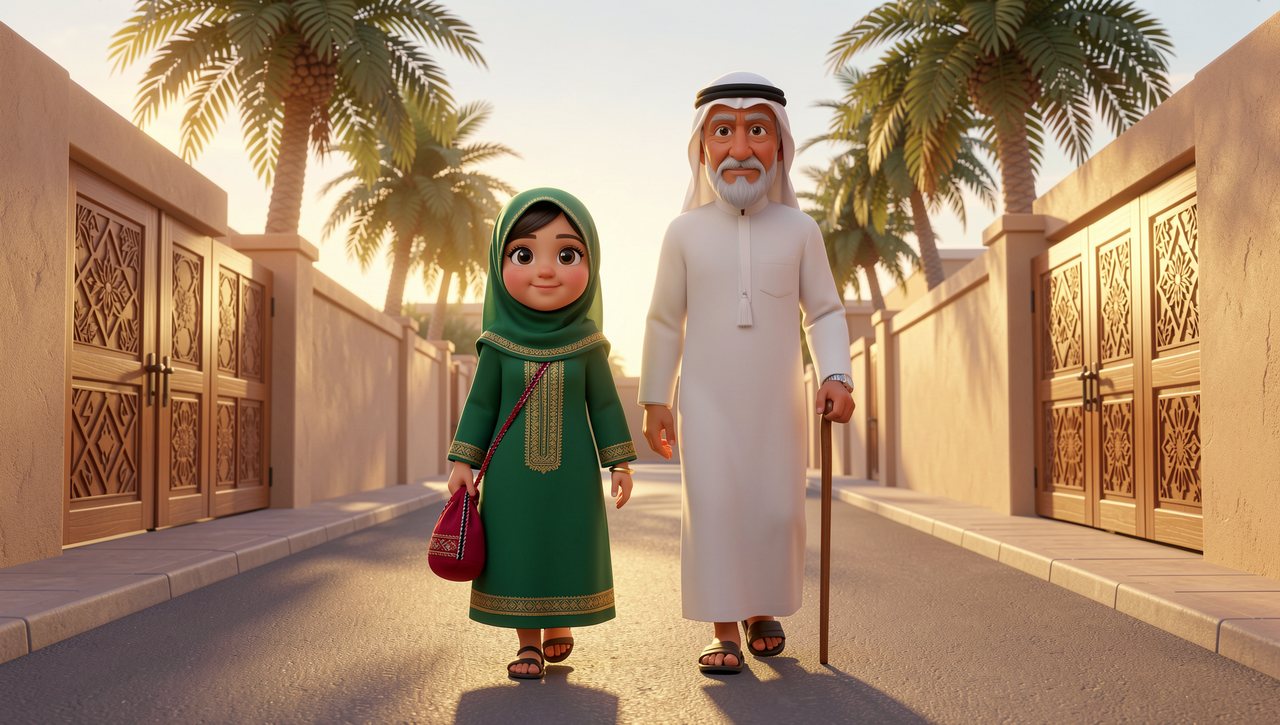
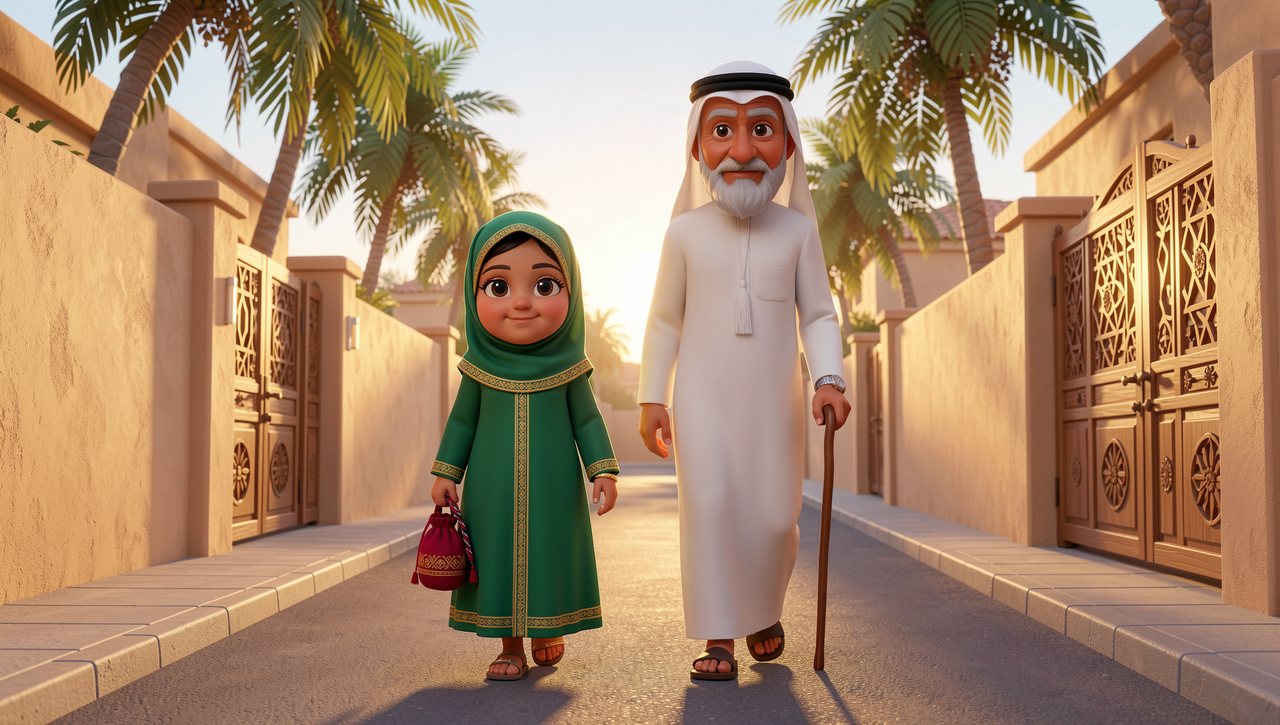
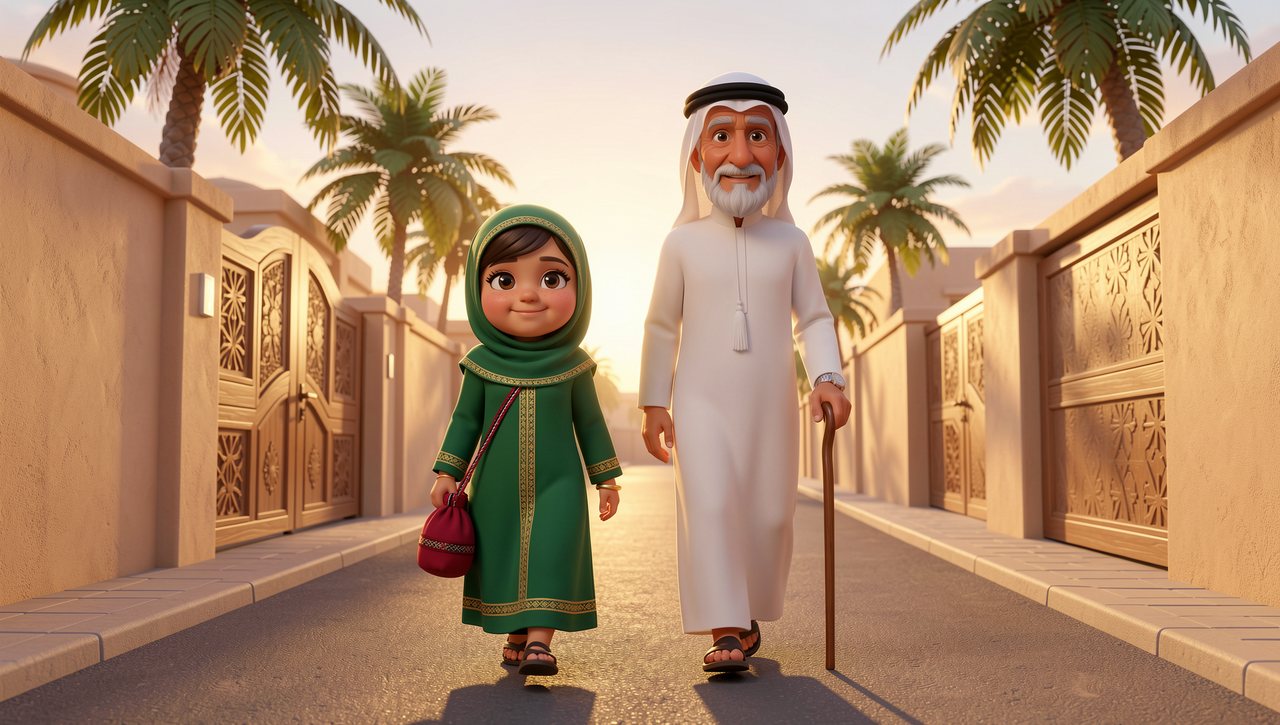
Keyframe review: Take 2: the only take with Noora ahead of Yaddi. All three put them on a modern paved street, not a sand fereej lane.
A convincing walk: Noora and Yaddi stride toward the camera down the lane with the bag swinging and the stick planted in step, and both stay consistent. They walk side by side, as in the keyframe, rather than Noora leading.
Shot 12 (7 s): Noora
Medium shot at a neighbour's closed carved wooden gate. Noora stands very small, clutching the empty bag, and starts the chant in a tiny voice that trails off.
عطونا الله يعطيكم…
Sung in Arabic: Give us, and God will give to you…
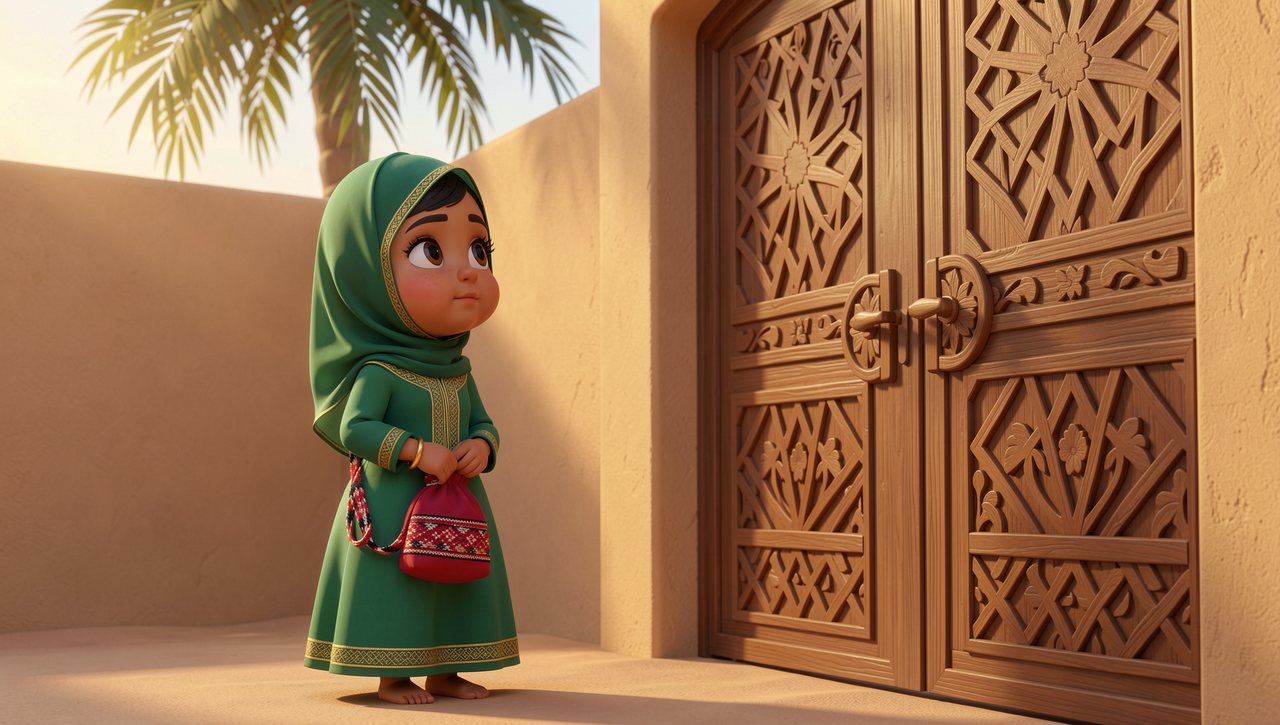
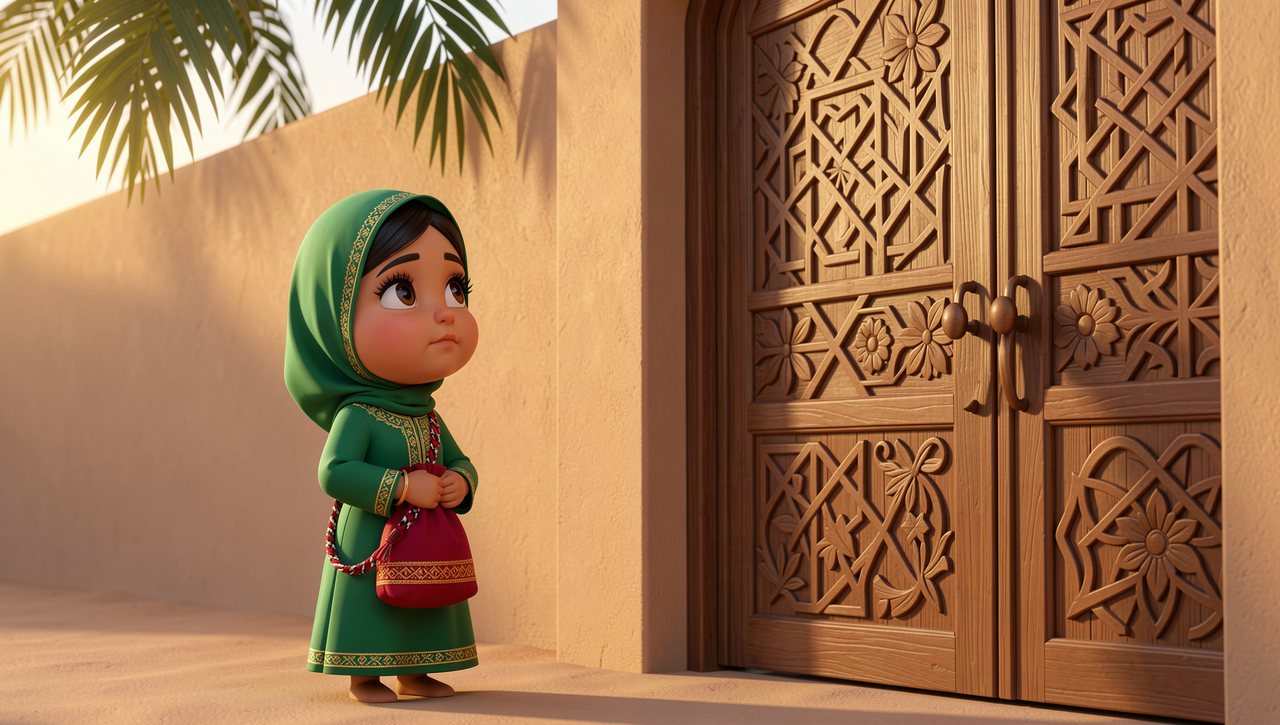
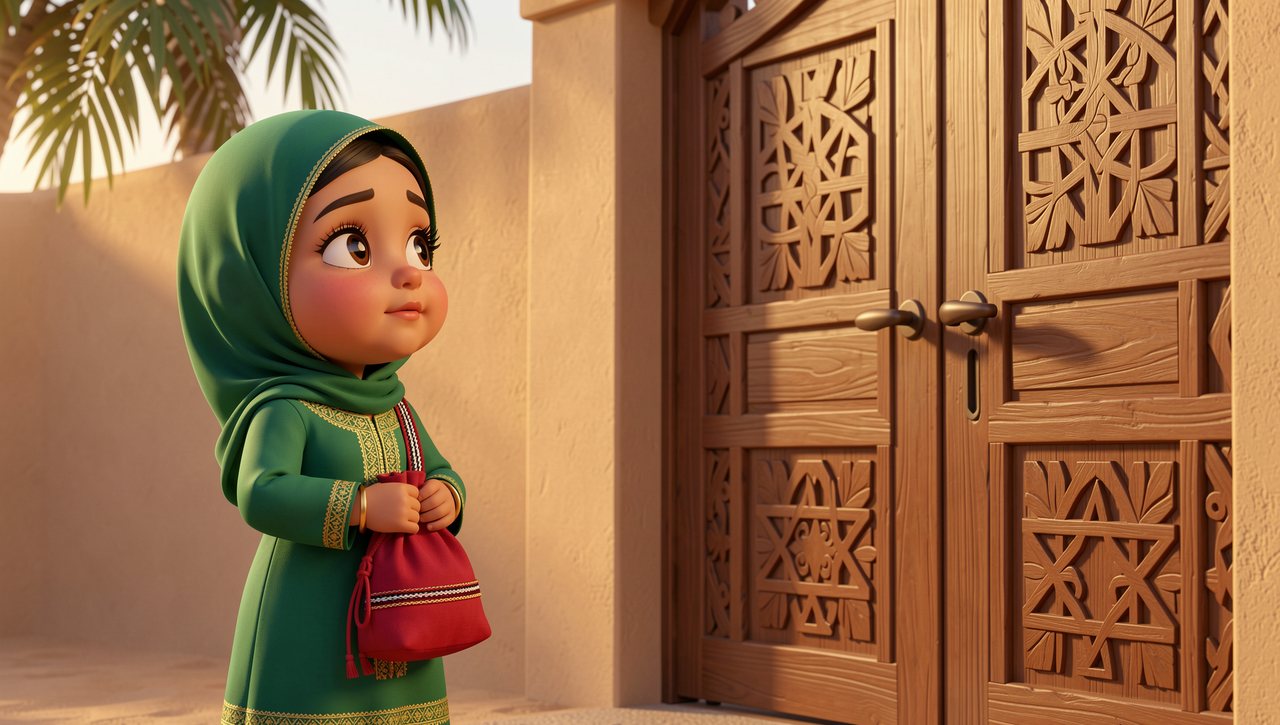
Keyframe review: Take 3: the medium shot, her face big enough for the chant.
Noora stands small at the closed gate, draws a breath, opens her mouth to sing, falters and lowers her eyes, clutching the bag: the beat is acted clearly even though no chant audio exists yet.
Shot 13 (5 s): Yaddi
Medium close-up: Yaddi, a few steps behind her, leans on his stick and nods gently.
علّي صوتج يا بنتي، لا تستحين.
Sing up, my girl. Don't be shy.
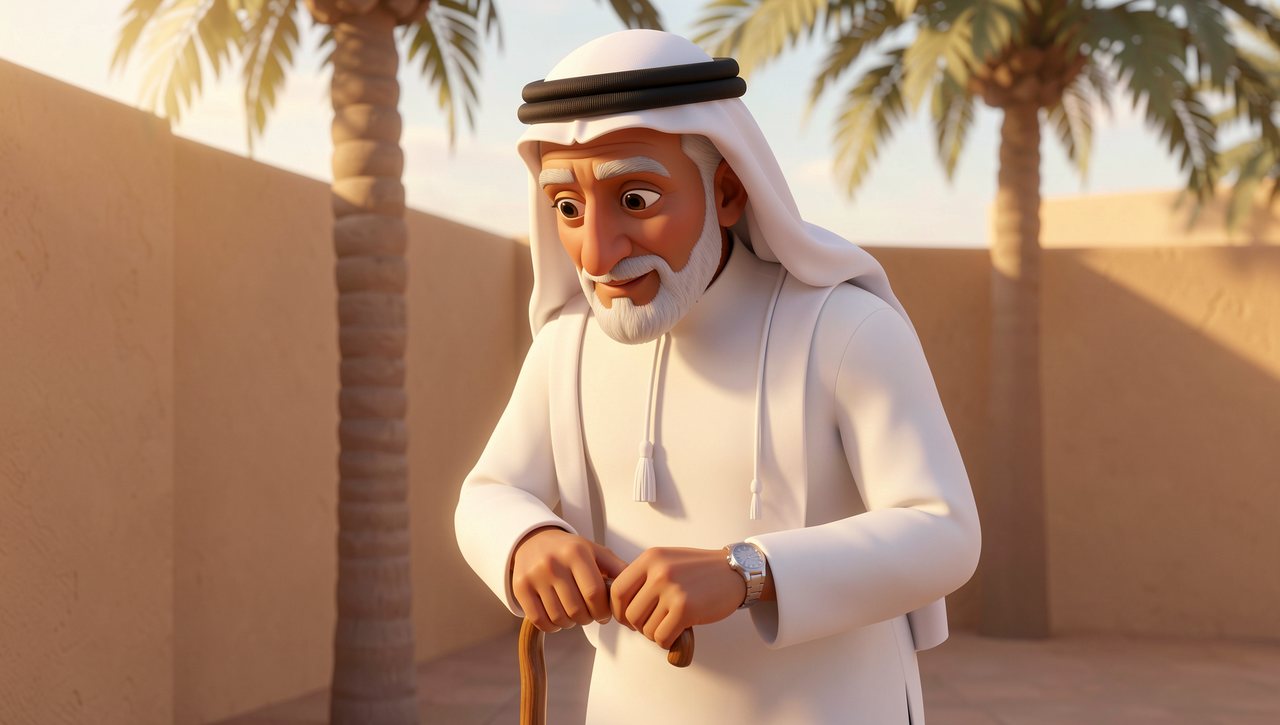
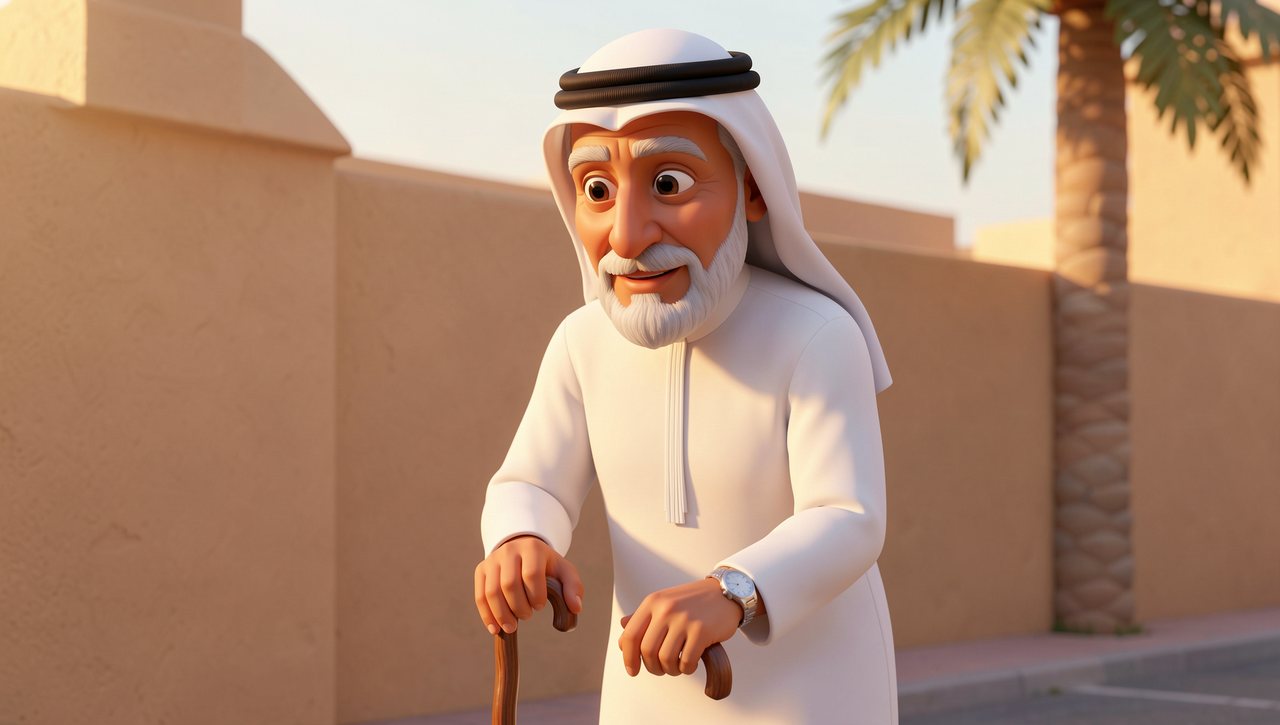
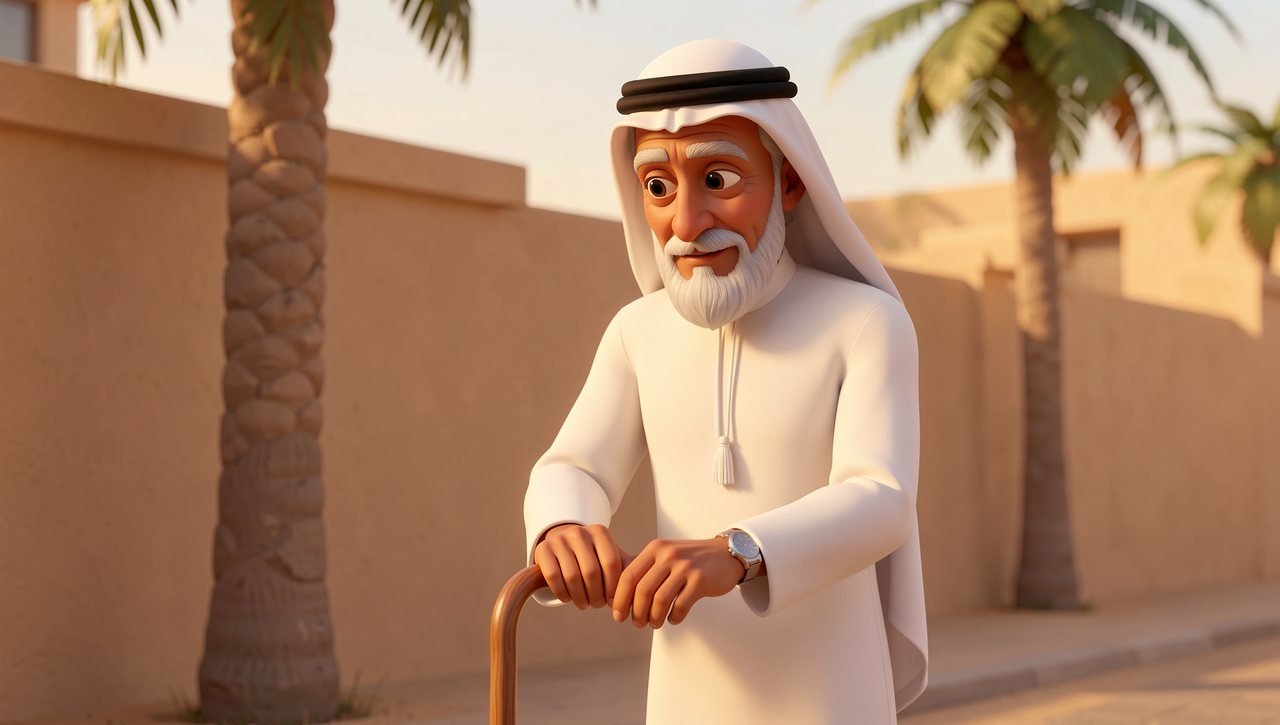
Keyframe review: Take 3: one cane. Take 2 gives him two.
Yaddi lifts a hand from his stick and speaks encouragingly, then leans on the stick again, in both languages. The stick stands upright on its own while his hand is off it, which a viewer will notice.
Shot 14 (8 s)
Golden hour in the family courtyard. Salem sits alone and barefoot on the majlis doorstep beside the coffee tray, the dallah set down on it. Faint, wobbly singing drifts over the wall, then stops. He turns round on the step to face the open doorway.
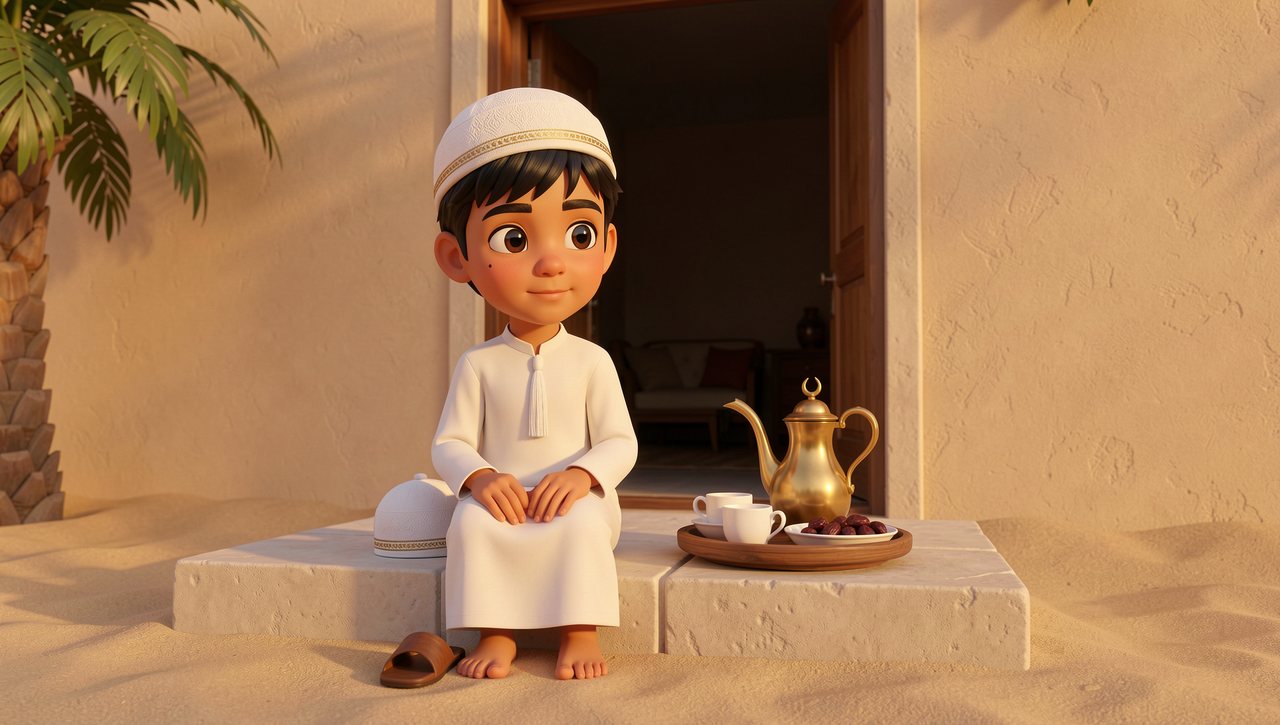
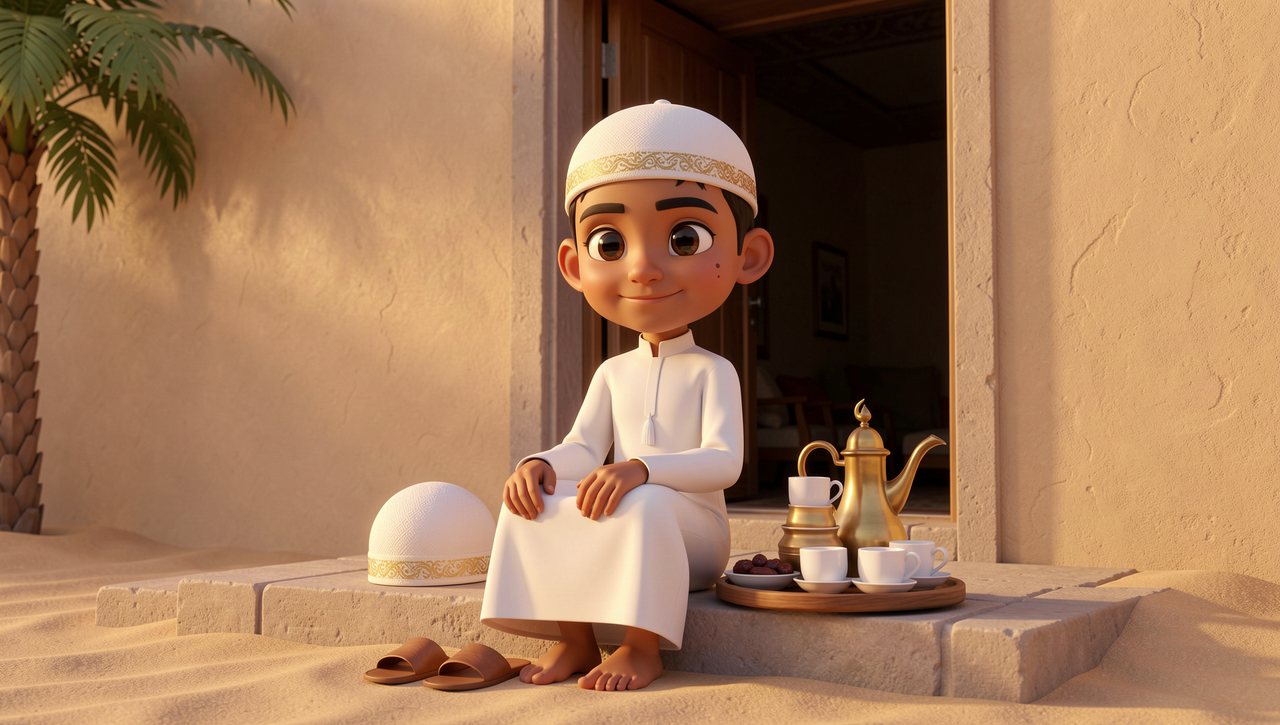
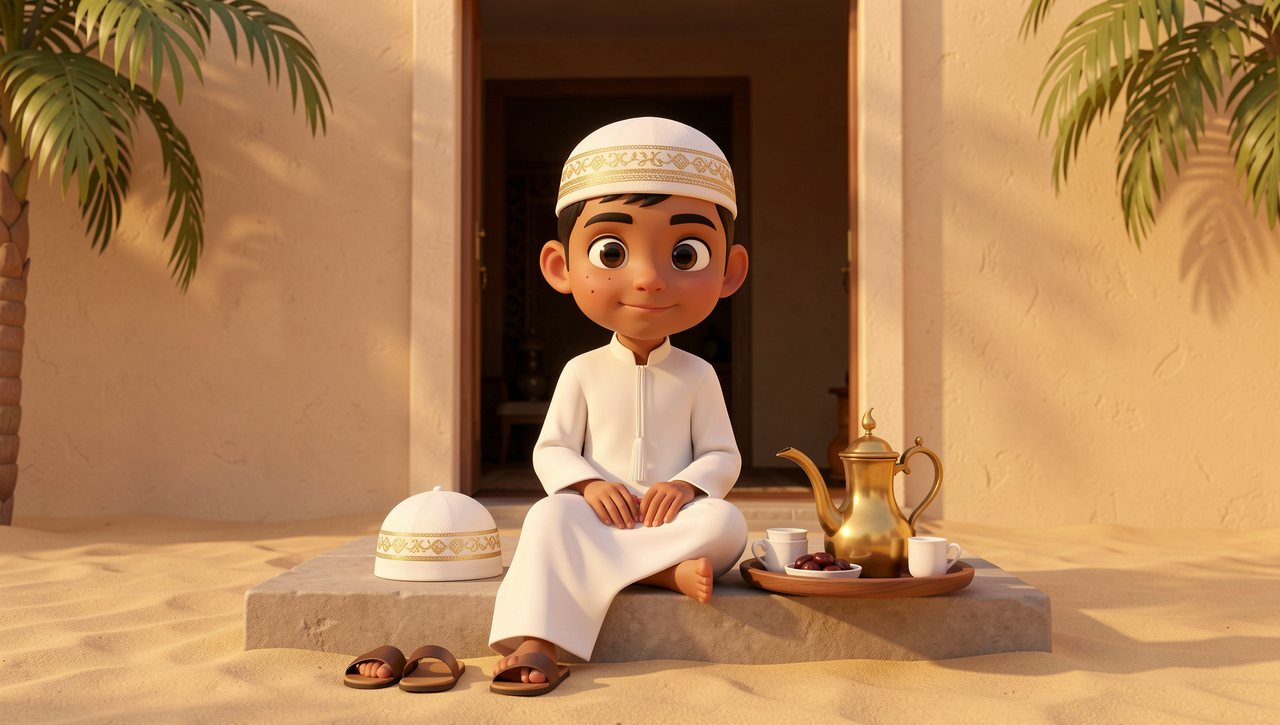
Keyframe review: Take 1. All three add a white cap-like dome on the step beside him; take 1 hides it best.
Salem sits on the step, his face falls as the singing stops, and he gets up and turns to face the doorway. The script has him turn round on the step rather than stand, but the beat reads clearly. The stray white cap from the keyframe sits on the step throughout.
Shot 15 (8 s): Yadda
Medium shot: Yadda stands in the majlis doorway holding the indigo khareetah and speaks softly, without scolding, to Salem, who sits turned towards her. On her last words she holds the bag out to him with her right hand.
تقول كبرت؟ الكبير ما يخلّي خته تغنّي بروحها.
You say you're grown up? A grown-up doesn't let his sister sing by herself.
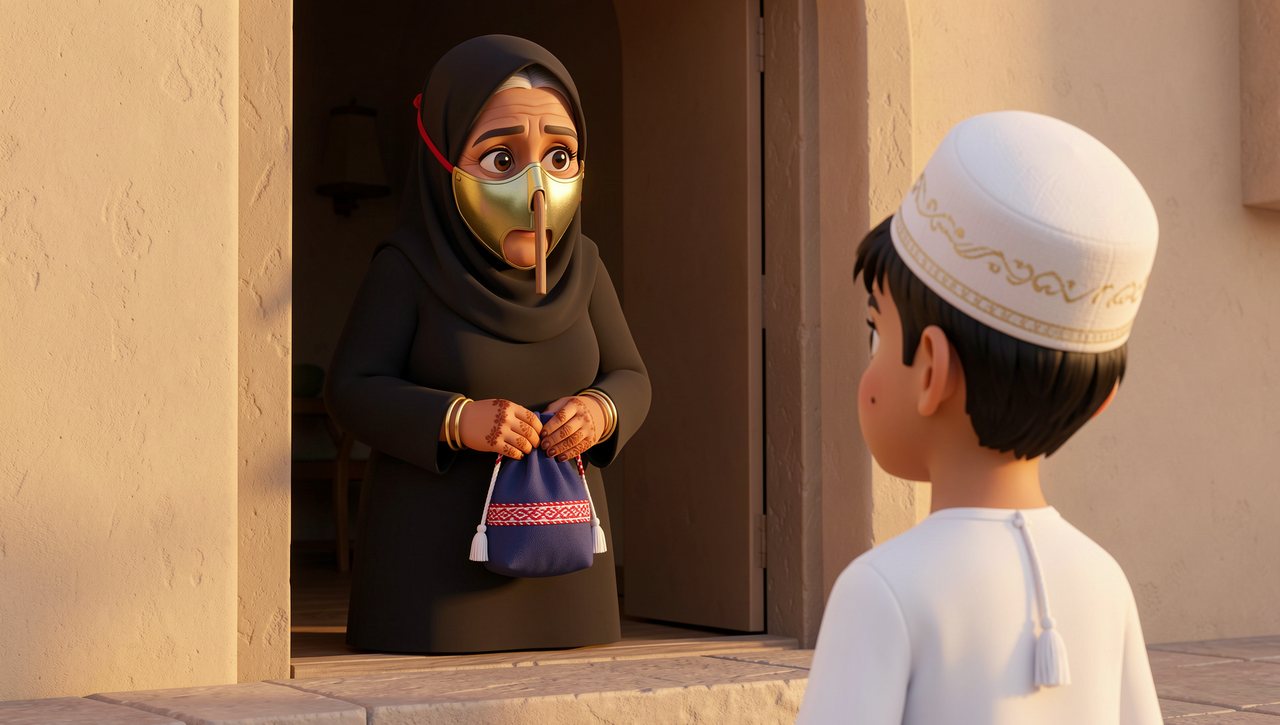
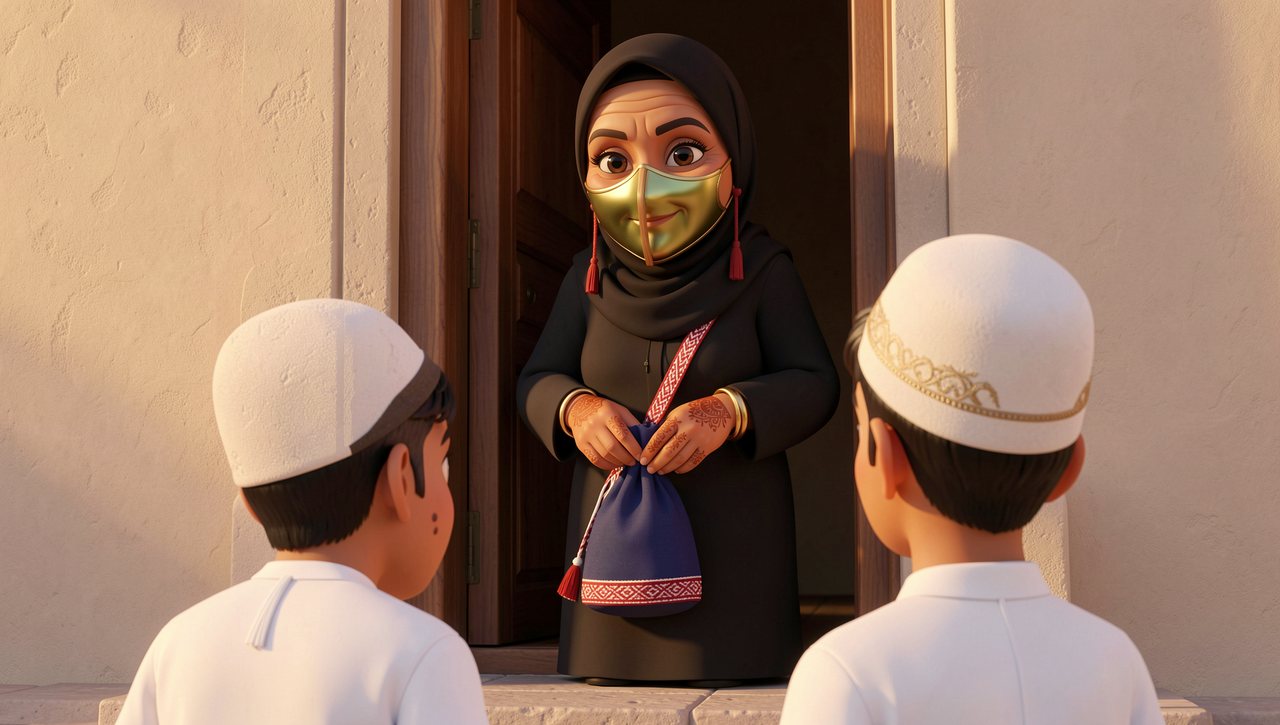
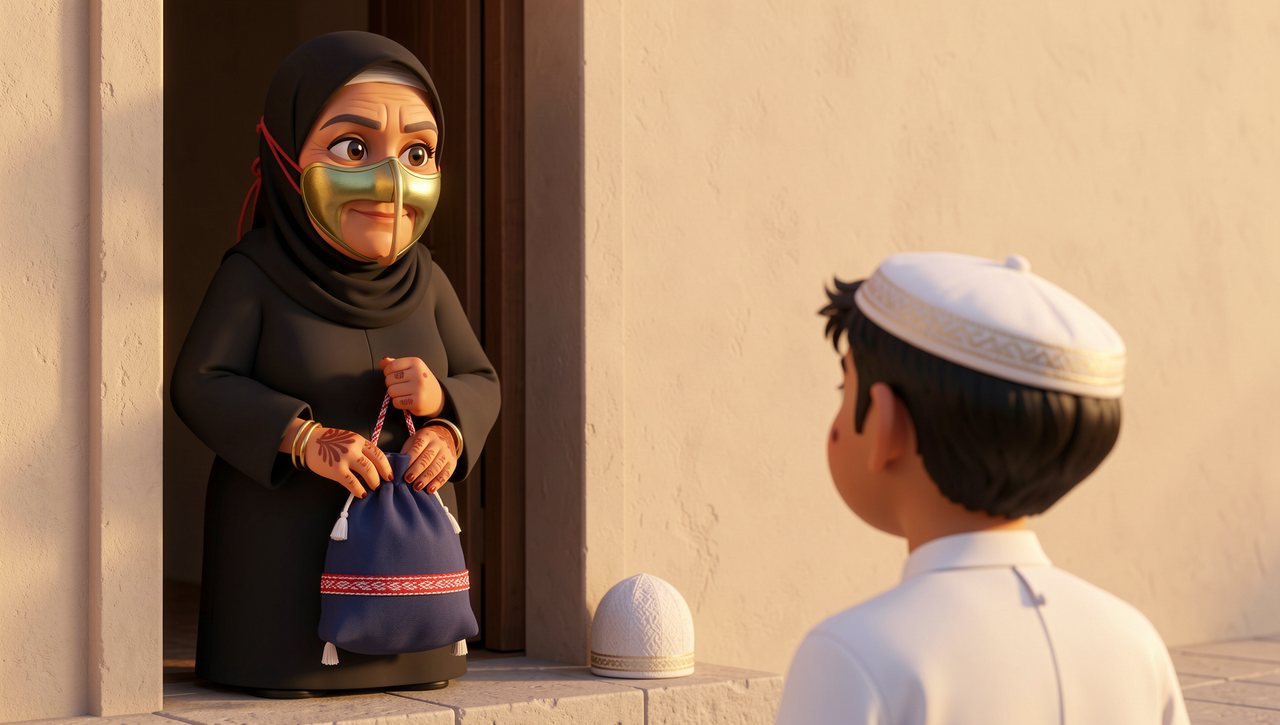
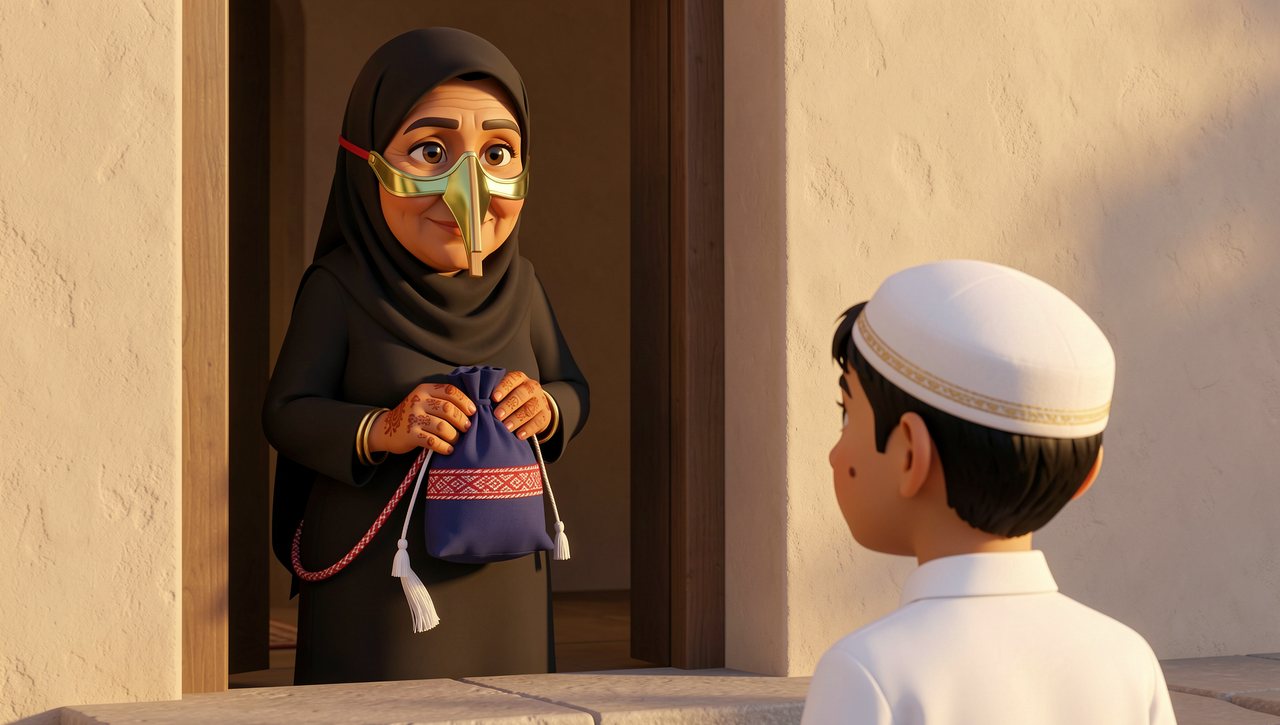
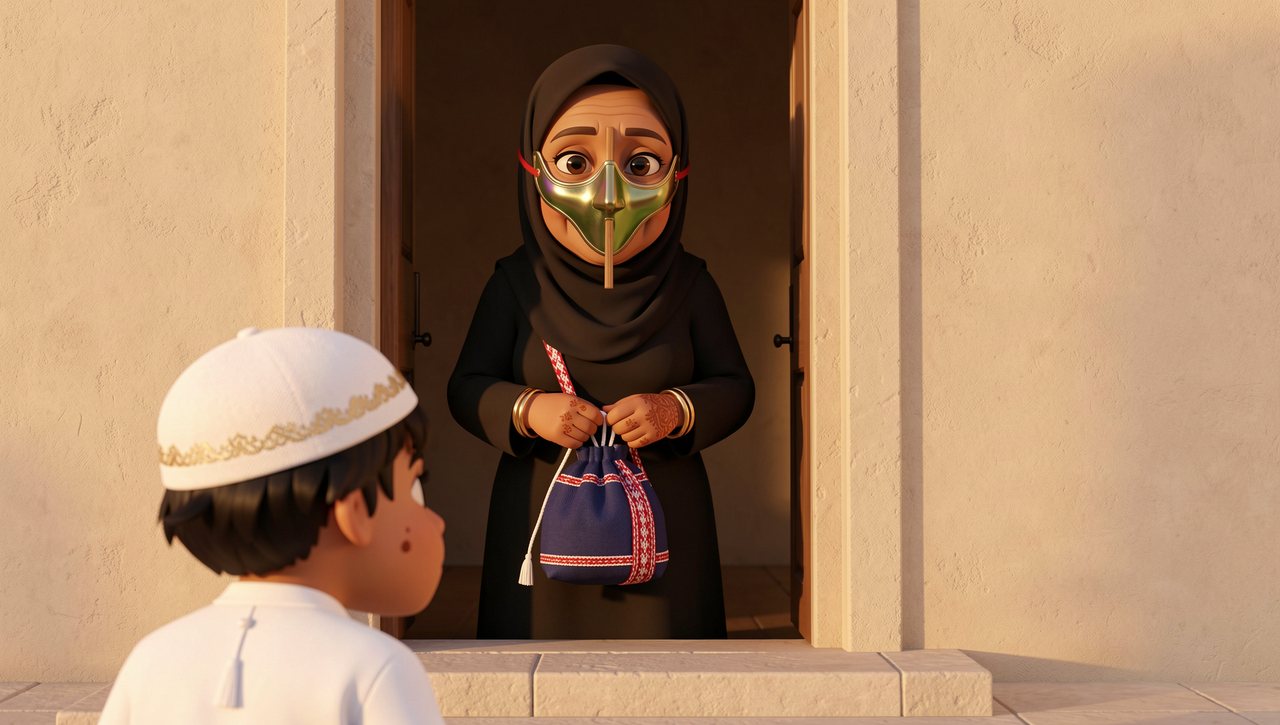
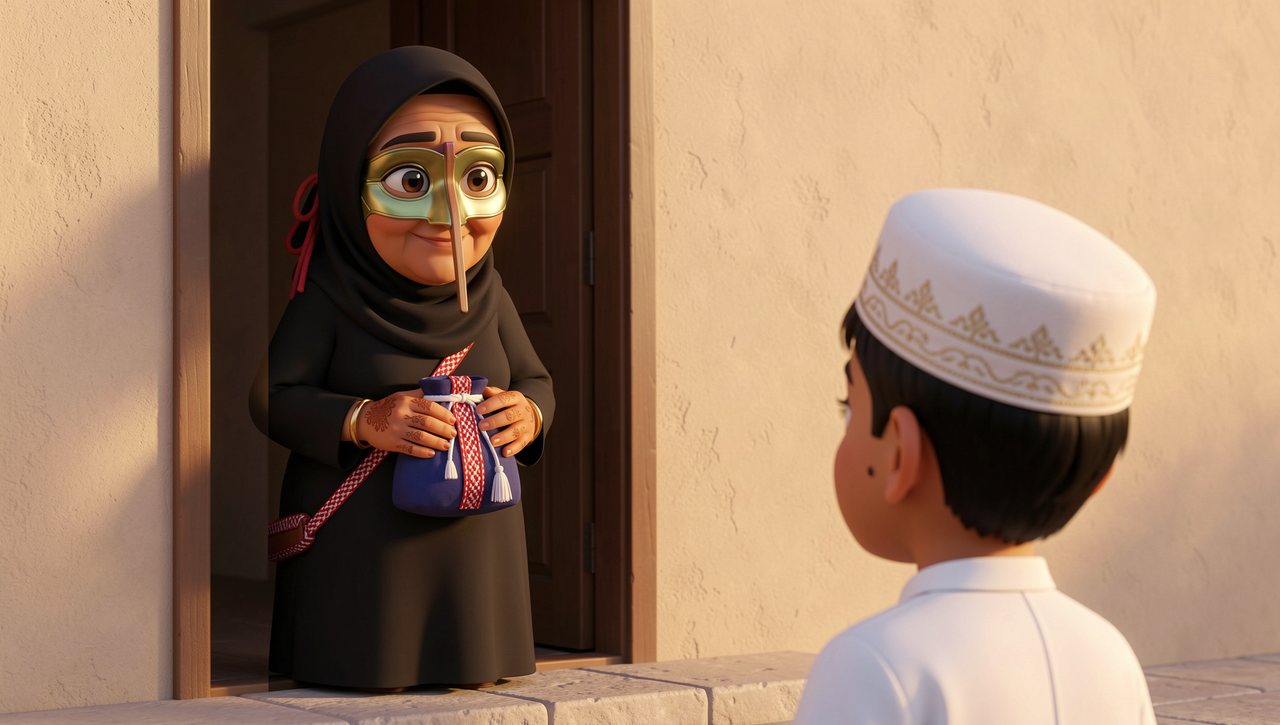
Keyframe review: All three wrong: the mask covers Yadda's mouth in every take, on a spoken line, and take 2 has two Salems. Takes 4-6 drawn. Takes 4-6 still cover her mouth. Looked at again at a larger size, take 3's mask stops above her upper lip, so her mouth shows; picked take 3 (a stray white cap sits on the step).
Yadda speaks in the doorway, then steps down to Salem and presses the indigo bag into his hands, which carries the scene's turn. Her lips show only partly under a mask that covers too much of her face, and the camera closes in on the two of them though the shot is meant to be fixed.
Shot 16 (8 s): Salem
Salem slides the coffee tray carefully back from the edge of the step, stands, takes the indigo khareetah from Yadda with his right hand, slips on his sandals and runs across the courtyard and out of the open gate, calling out. In the doorway, Yadda's eyes crinkle in a smile.
ياي يا نورة، ياي!
Coming, Noora! I'm coming!
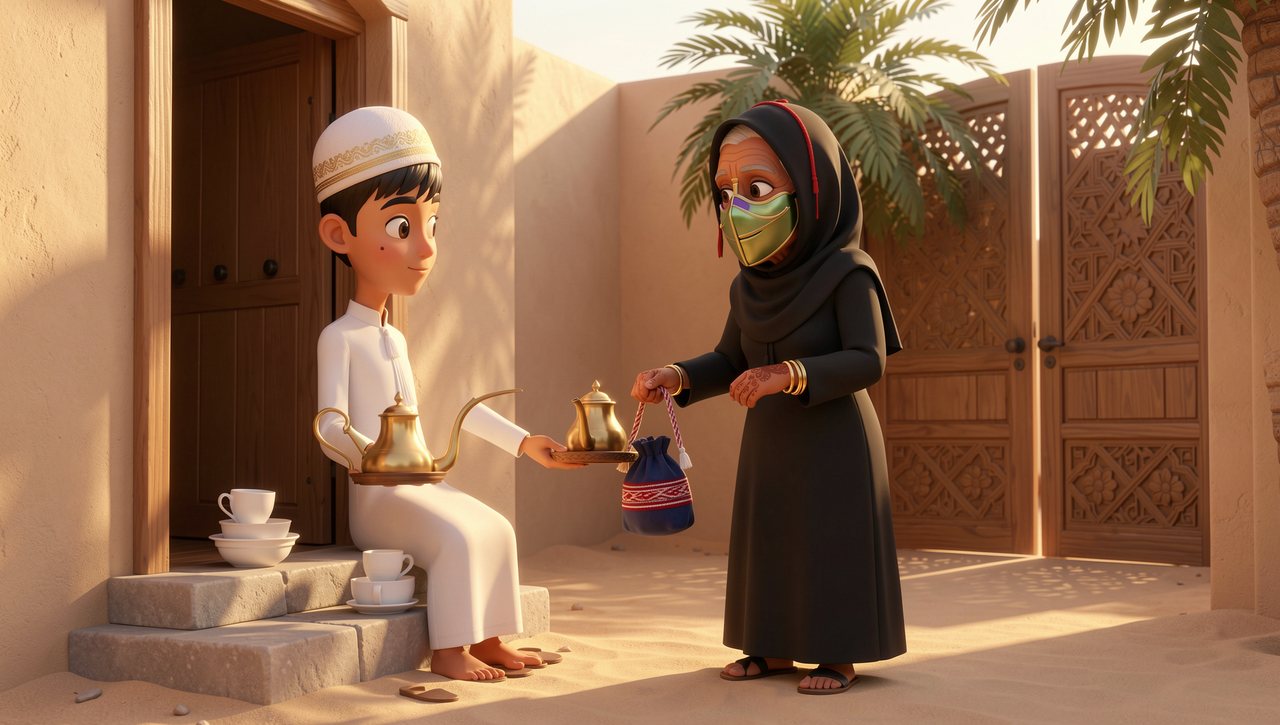
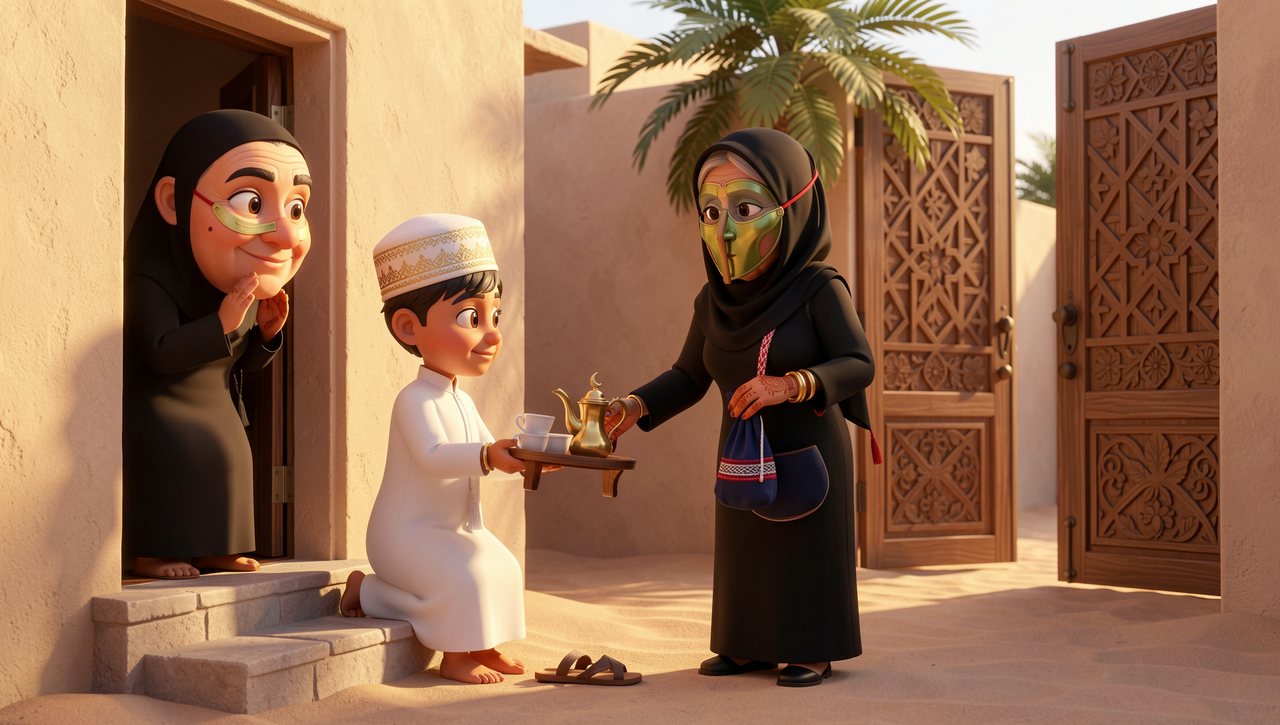
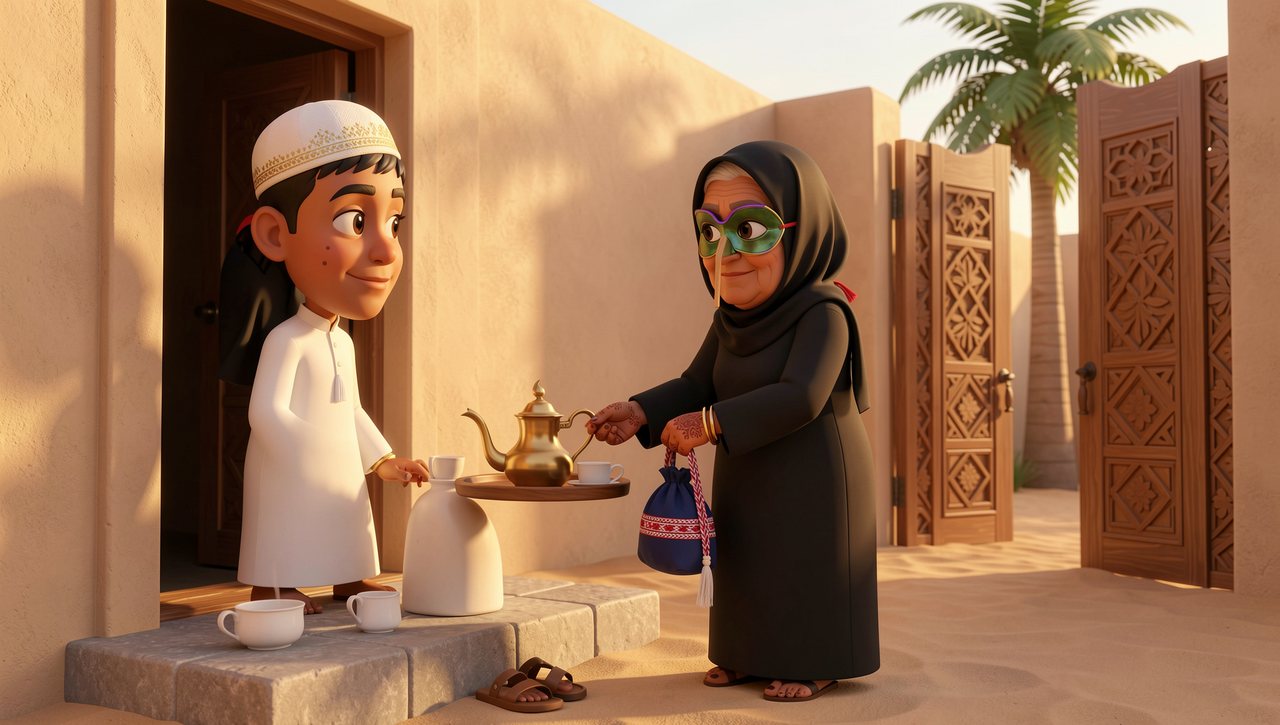
Keyframe review: Take 1. Take 2 has two Yaddas.
The action plays in order: Salem sets the tray down, takes the indigo bag from Yadda and runs out through the gate. Then LTX-2.5 adds something the shot never asked for, a hard cut inside the clip to a close-up of Yadda in a doorway, so this clip needs trimming before the cut point. Yadda's mask covers her mouth, as in the keyframe.
Shot 17 (7 s): Salem
Medium shot at the neighbour's gate. Salem runs up beside Noora, out of breath, and takes her free hand. She lights up, and Yaddi smiles behind them.
يلّا يا نورة، ويّاي. من الأول!
Come on, Noora, sing with me. From the start!
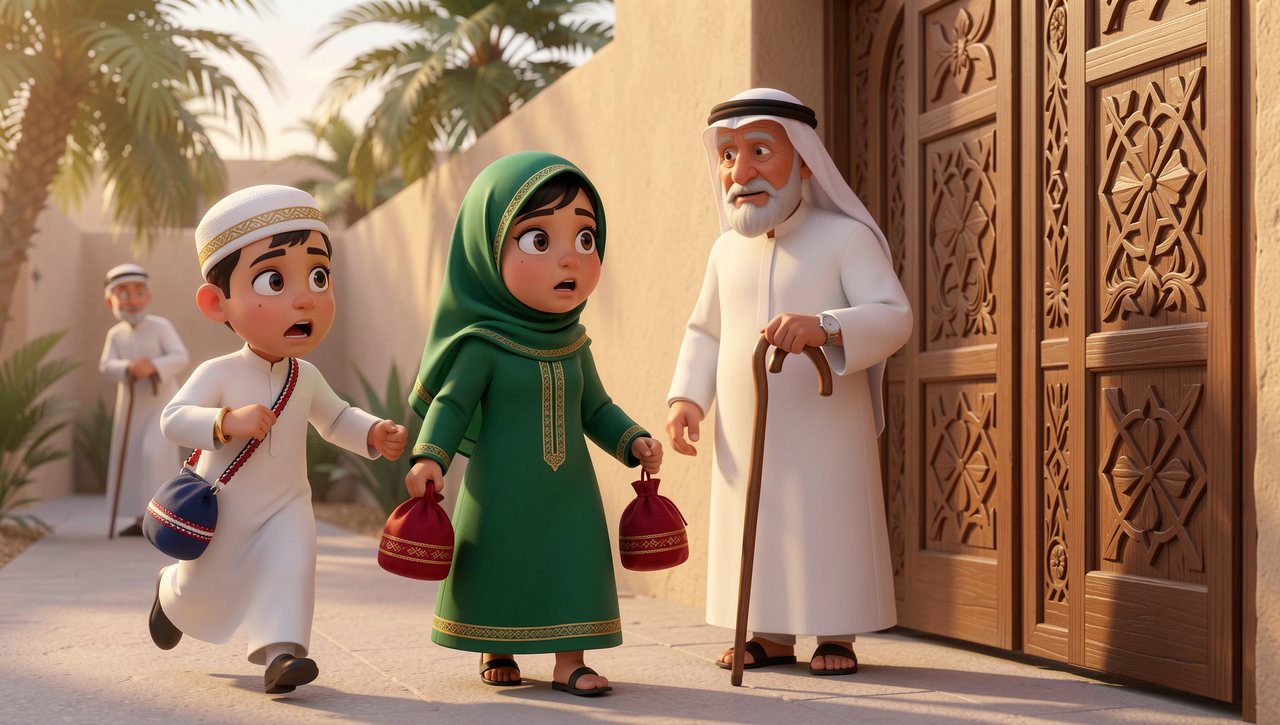
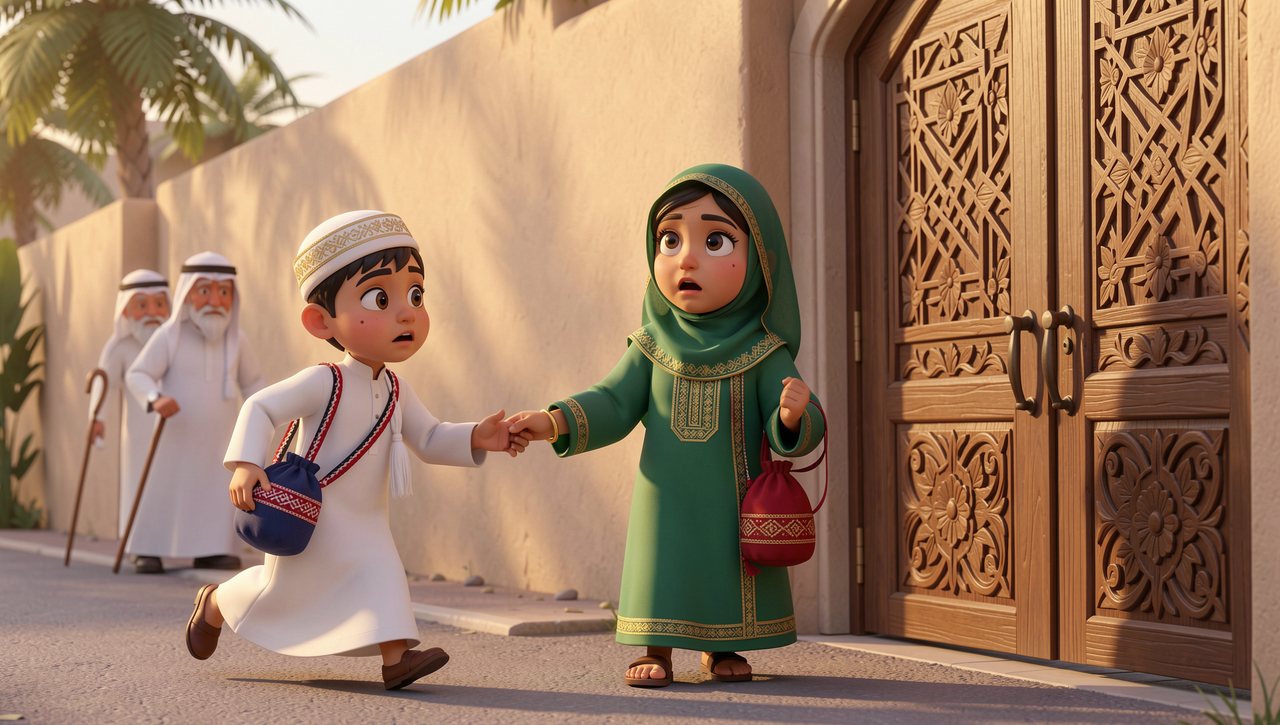
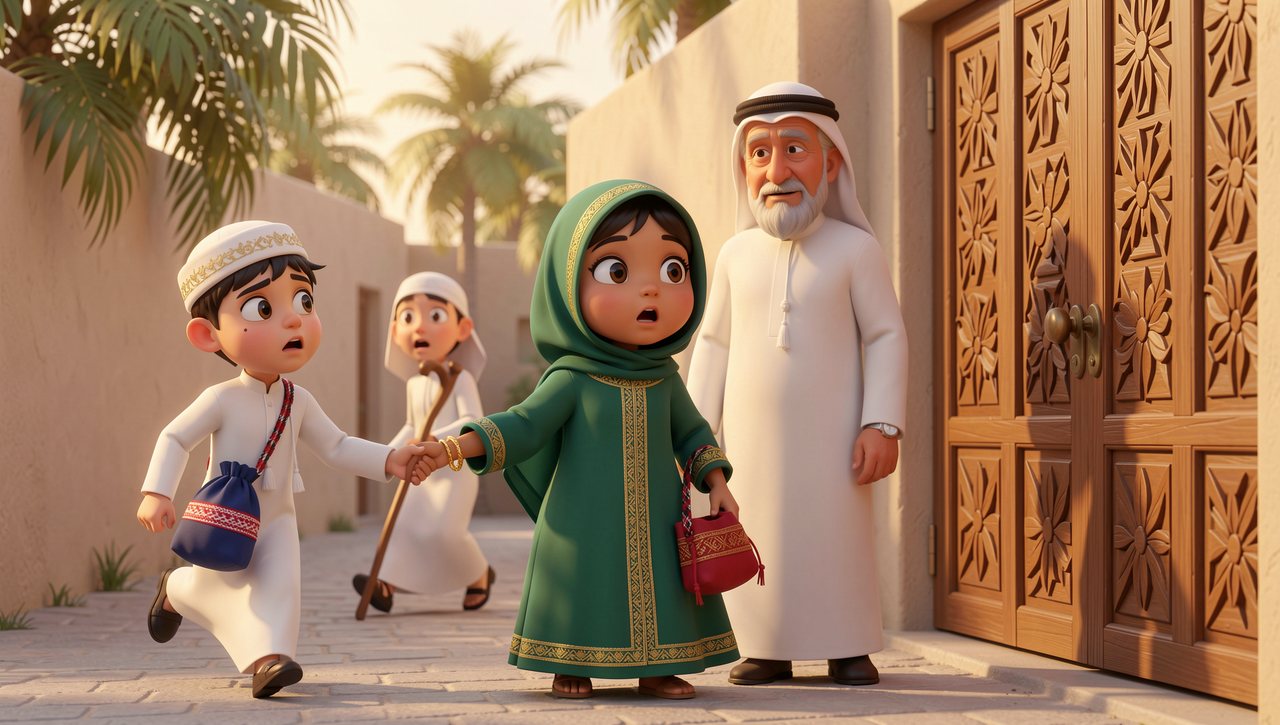
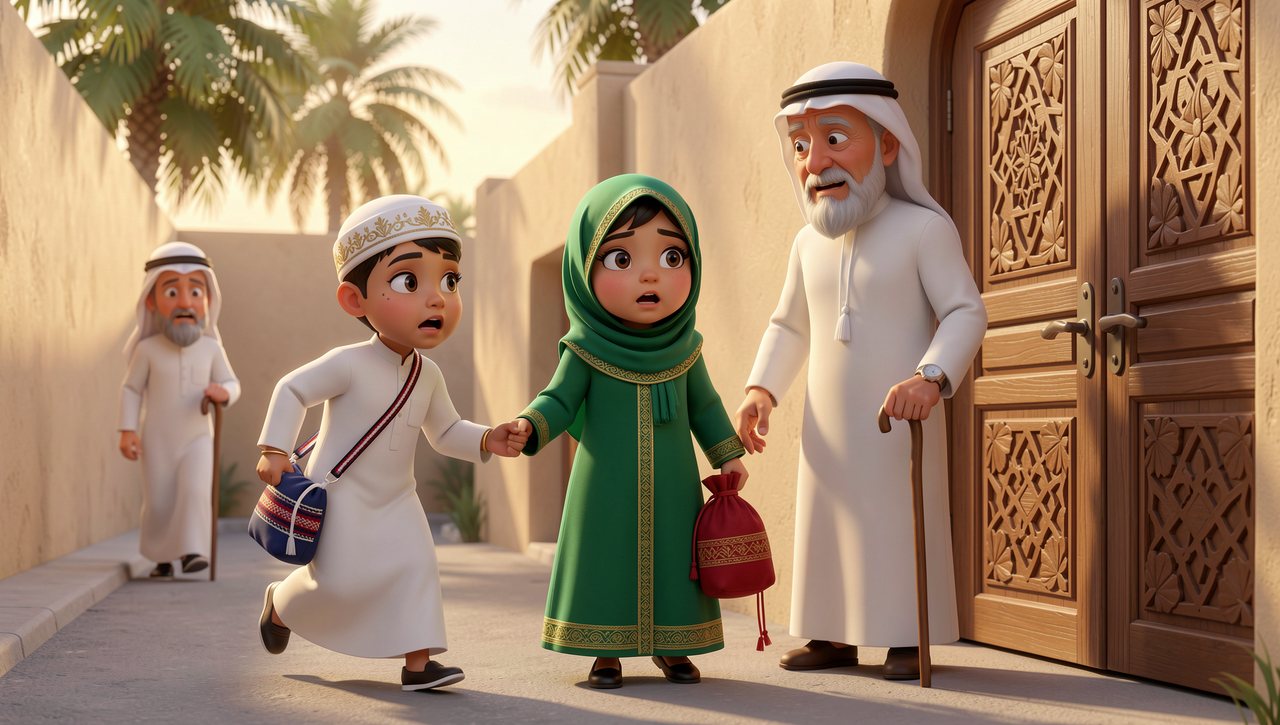
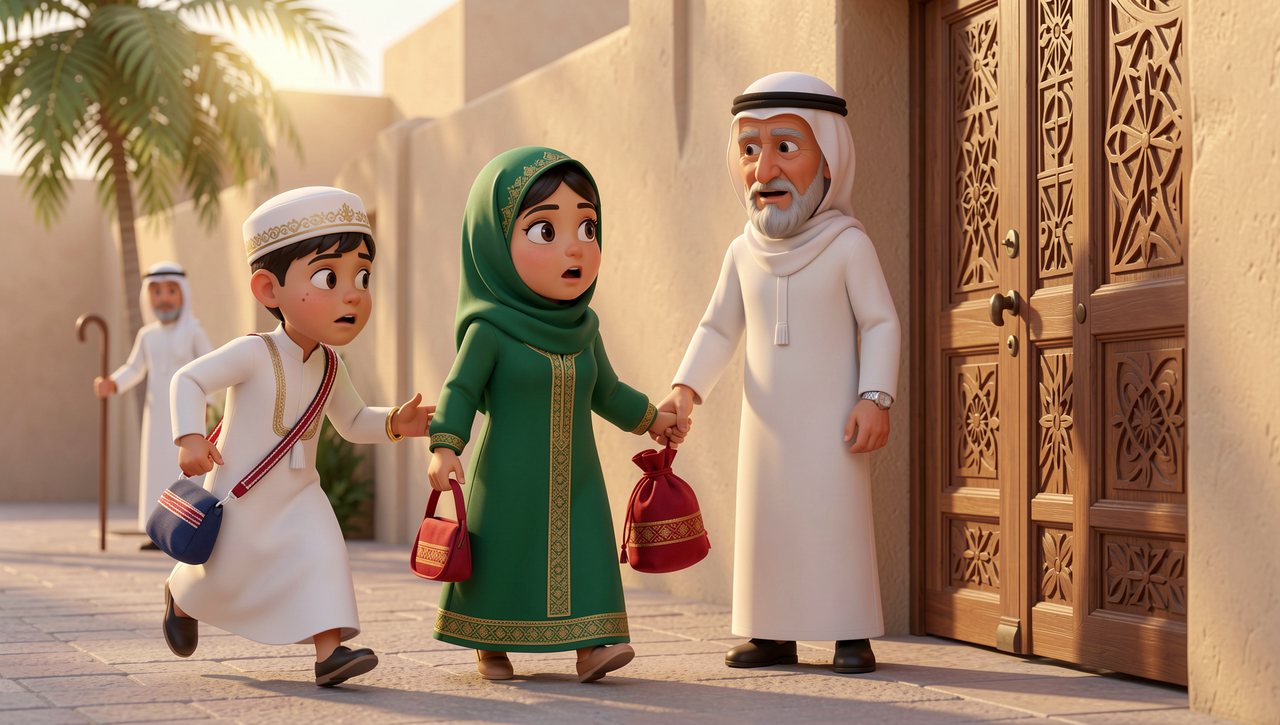
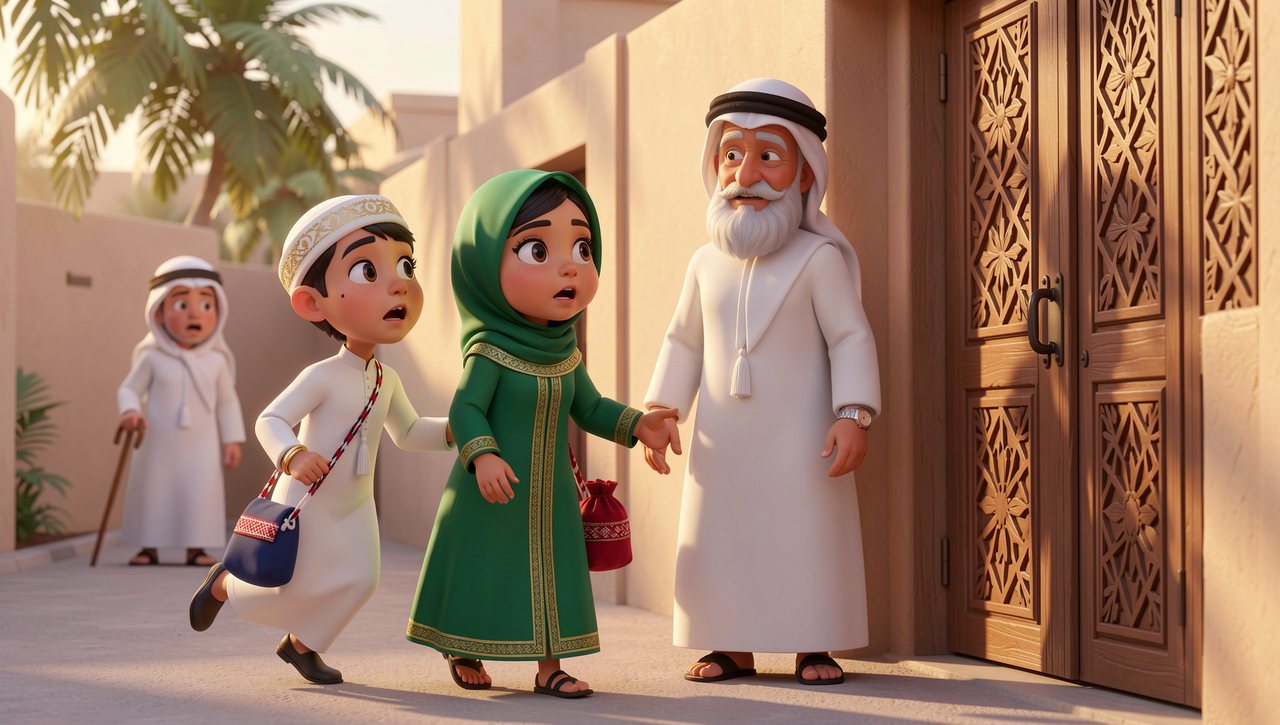
Keyframe review: All three wrong: extra old men or children in the background of every take, and Noora holds two bags in take 1. Takes 4-6 drawn. Takes 4-6 keep an extra old man in the background. Picked take 4: one crimson bag, Salem holding Noora's hand, Yaddi behind them, and the extra figure small.
Salem runs up, takes Noora's hand and speaks as the camera moves in to a close two-shot, with Yaddi smiling behind. With the voice held, the unrequested dissolve of the first render is gone and the move is continuous. The extra old man from the keyframe stays in the background.
Shot 18 (12 s): Salem and Noora
Two-shot facing the gate: Salem and Noora sing the chant together, loud and sing-song, clapping in rhythm. Voices only, no instruments. Two singers in one frame make this the harder lip-sync case.
عطونا الله يعطيكم، بيت مكة يوديكم. عطونا الله يعطيكم، بيت مكة يوديكم.
Sung in Arabic: Give us, and God will give to you; may He take you to His House in Makkah.
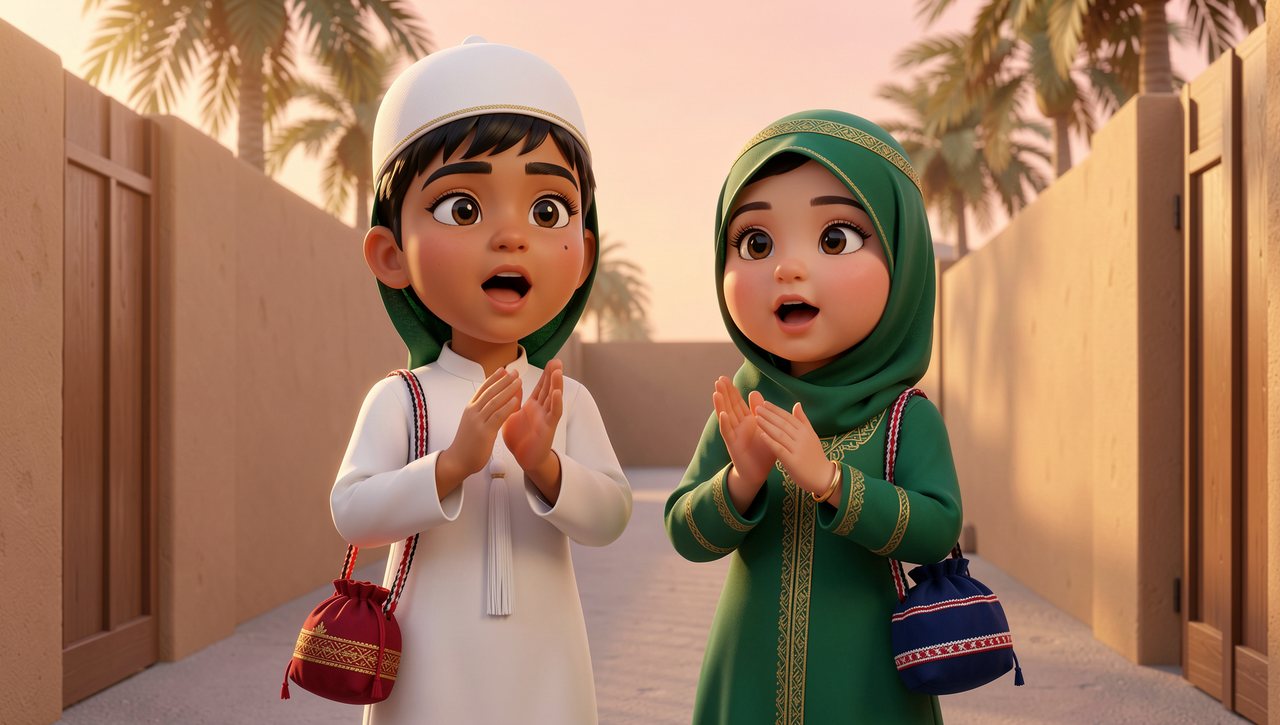
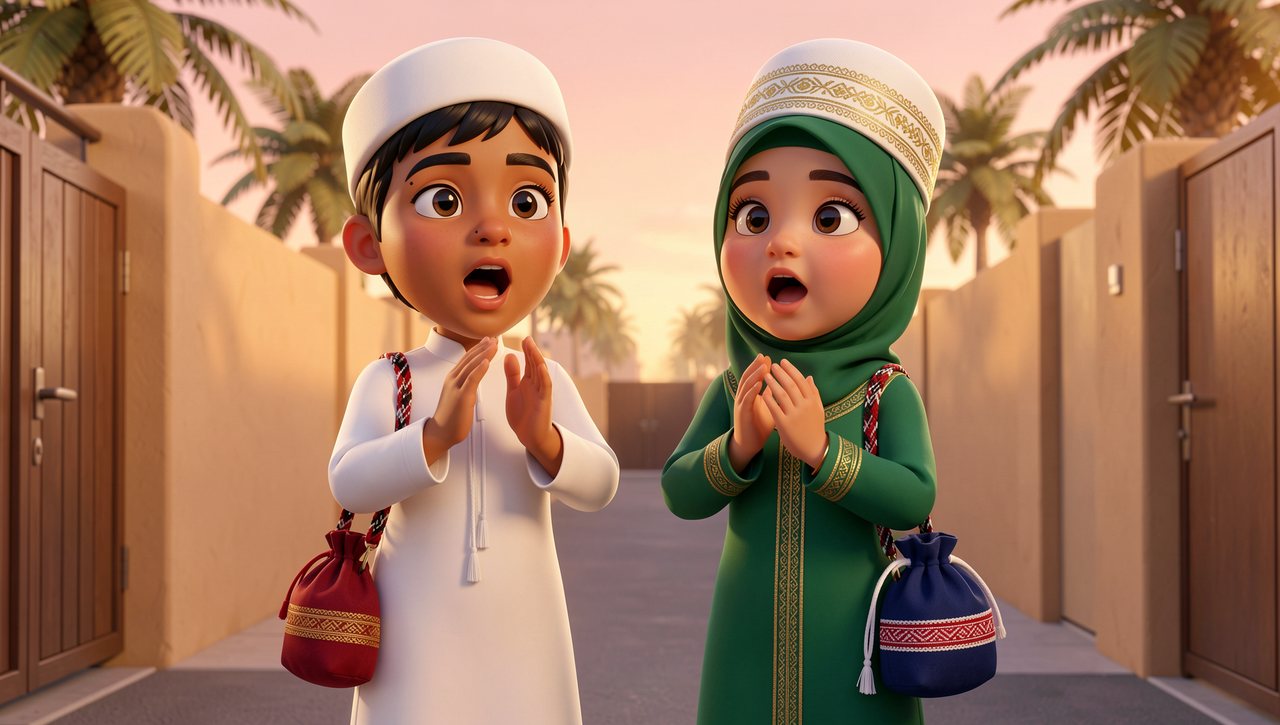
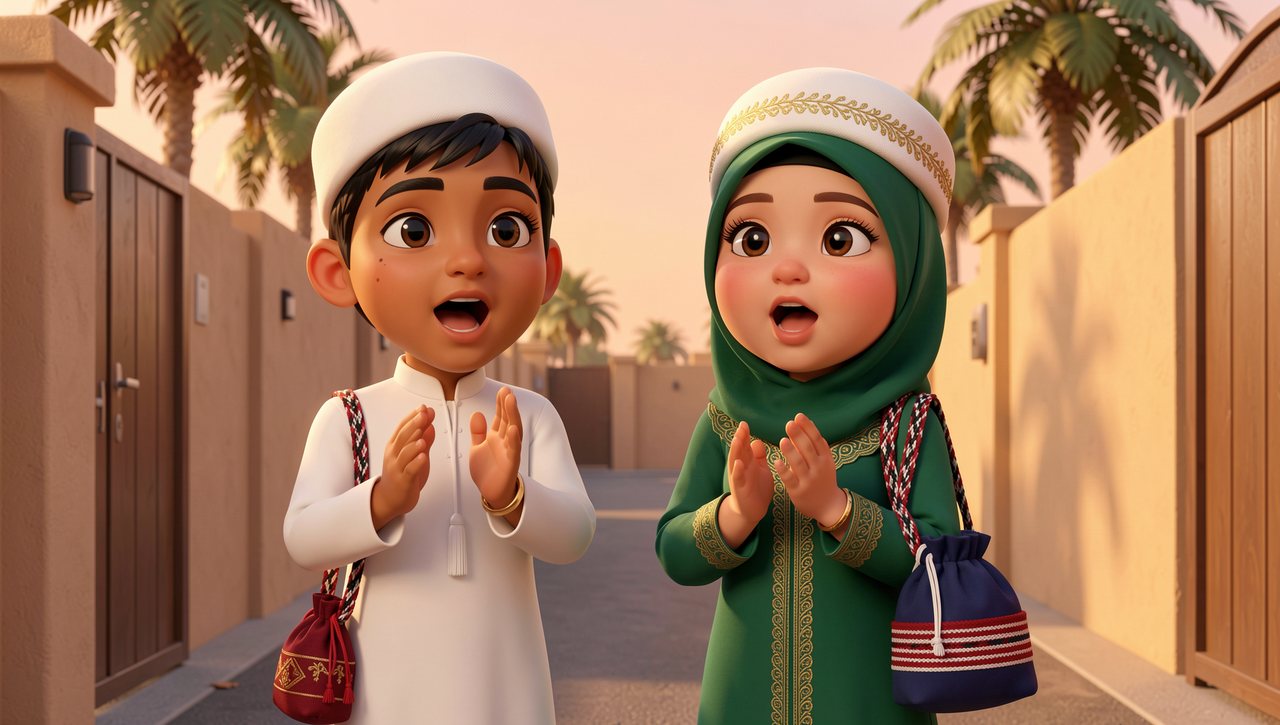
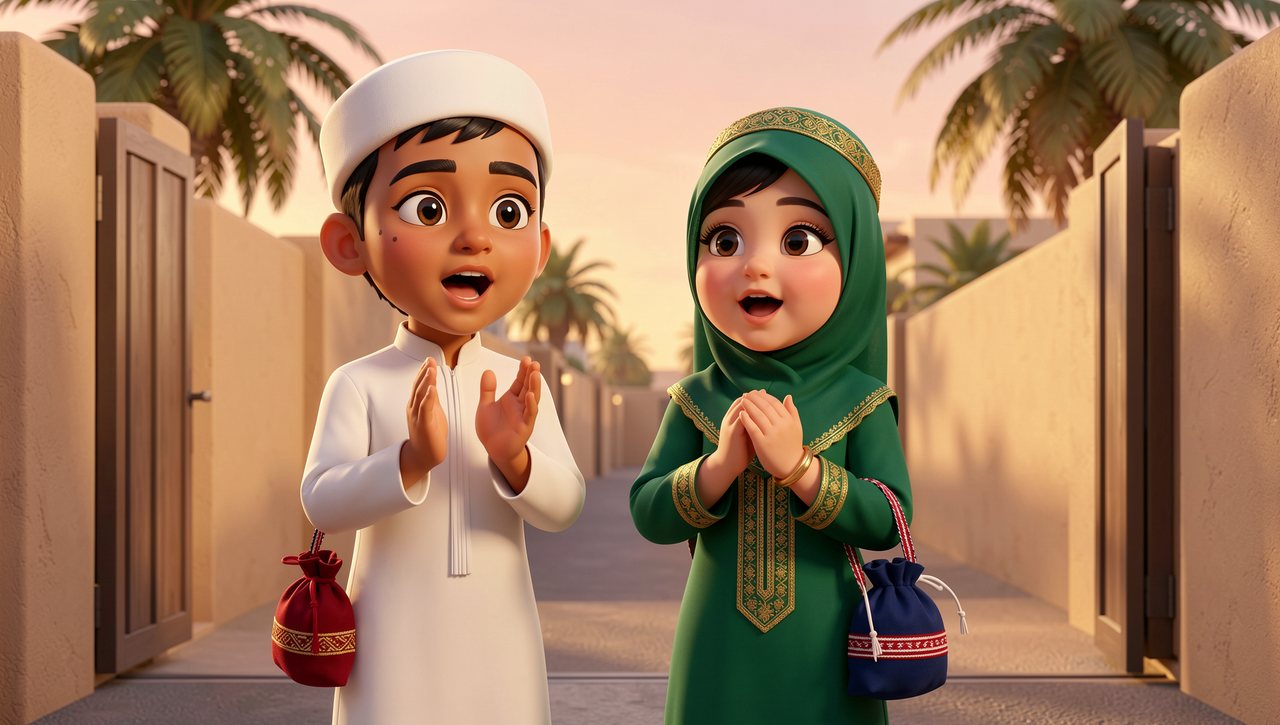
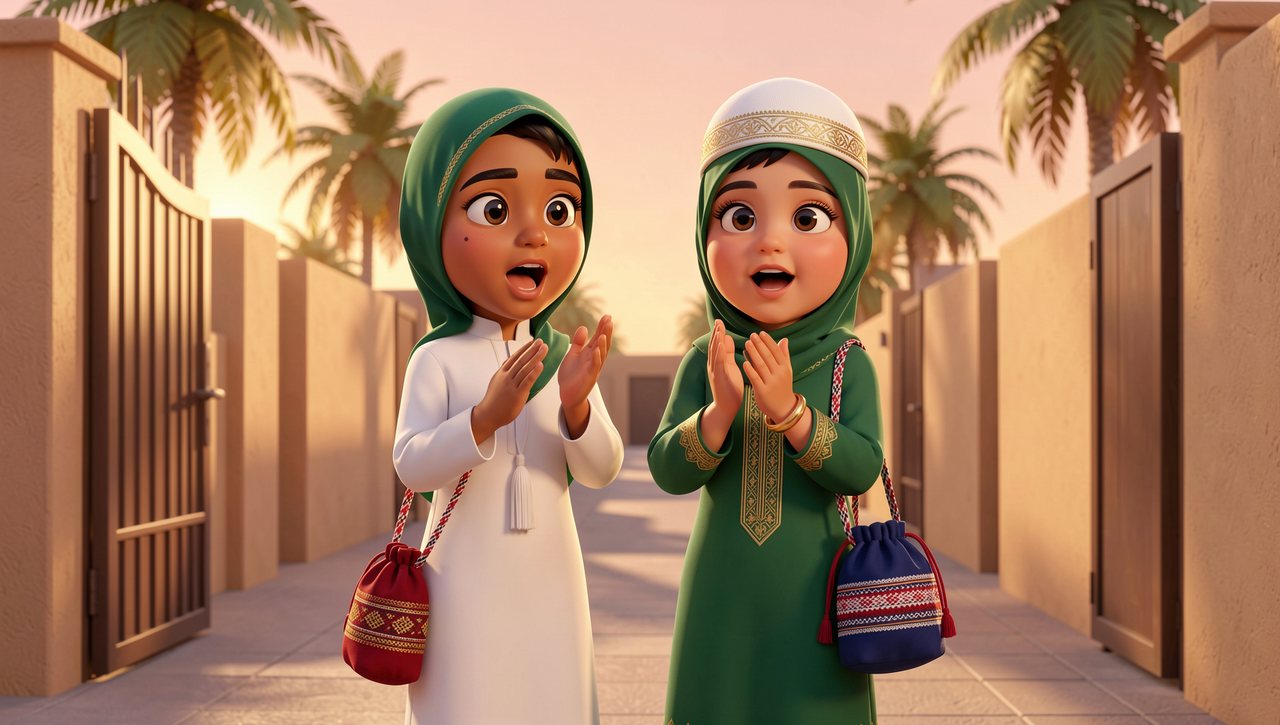
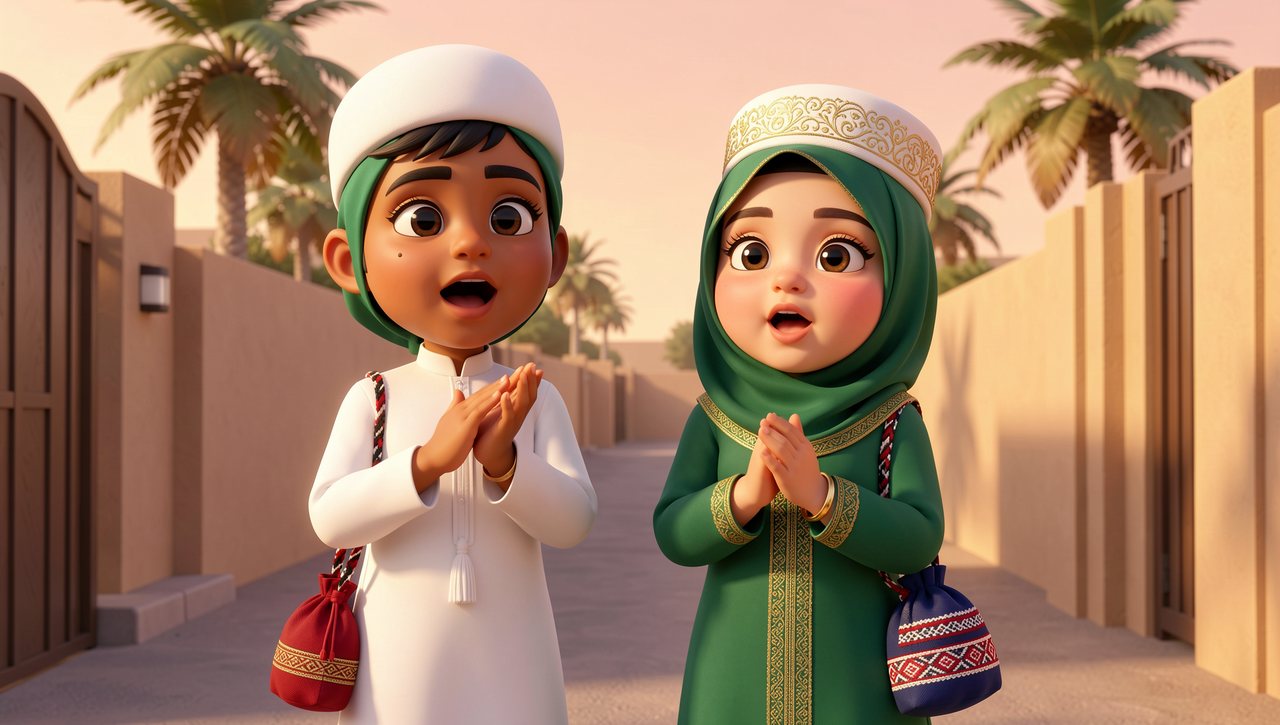
Keyframe review: All three wrong: the children's bags are swapped in every take (Noora's is crimson), and Noora wears Salem's skullcap in takes 2 and 3. Takes 4-6 drawn. The bags are swapped in all six takes (Salem crimson, Noora indigo), and takes 5 and 6 swap the head coverings. Picked take 4, the only one with both children's headwear right; the bag swap stays.
The clip: both children sing and clap as the camera pushes in slowly, and their faces hold. Their hands smear into shapeless blurs on the fast claps, and Salem's single mole becomes several spots by the end. No chant audio went in, so their mouths move without a sung track to follow.
Shot 19 (8 s): Noora
The carved gate has swung open onto warm light. A neighbour in a white kandura, seen only from the chest down, tips mixed nuts and small wrapped sweets from a brass bowl into each khareetah in turn, and the bags bulge. The children stay outside the gate.
مشكور يا عمّي!
Thank you, Uncle!
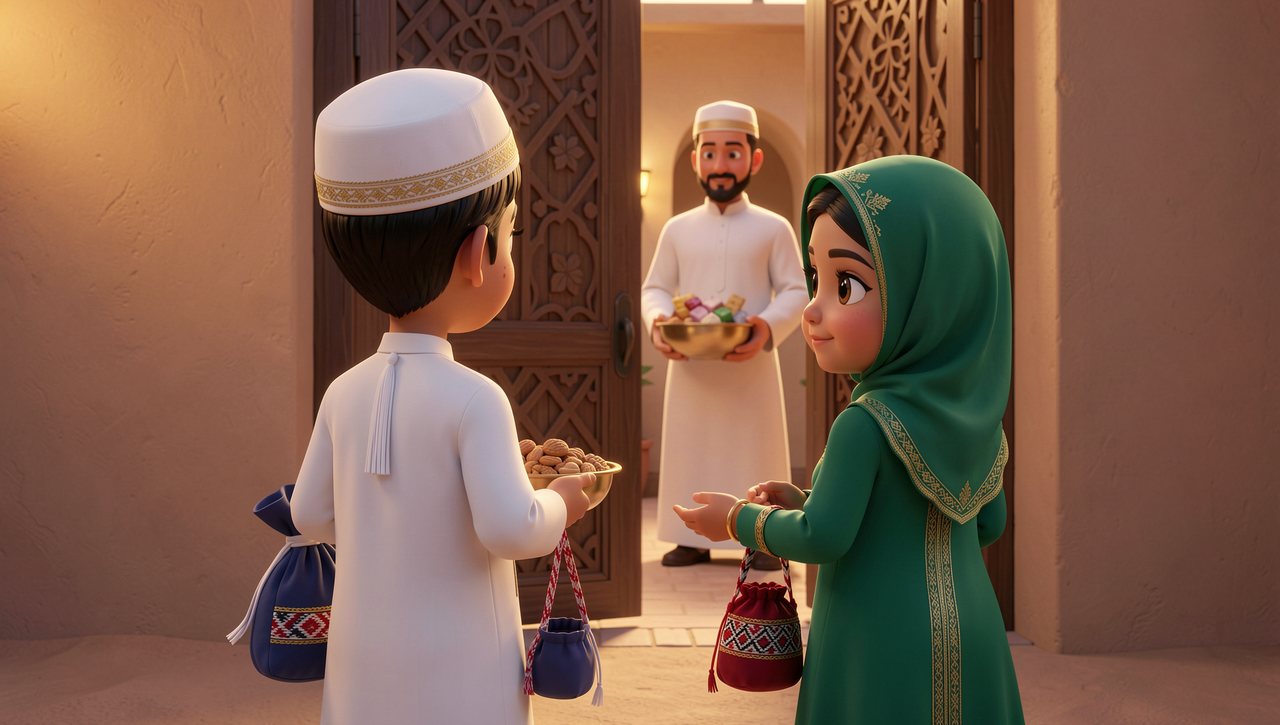
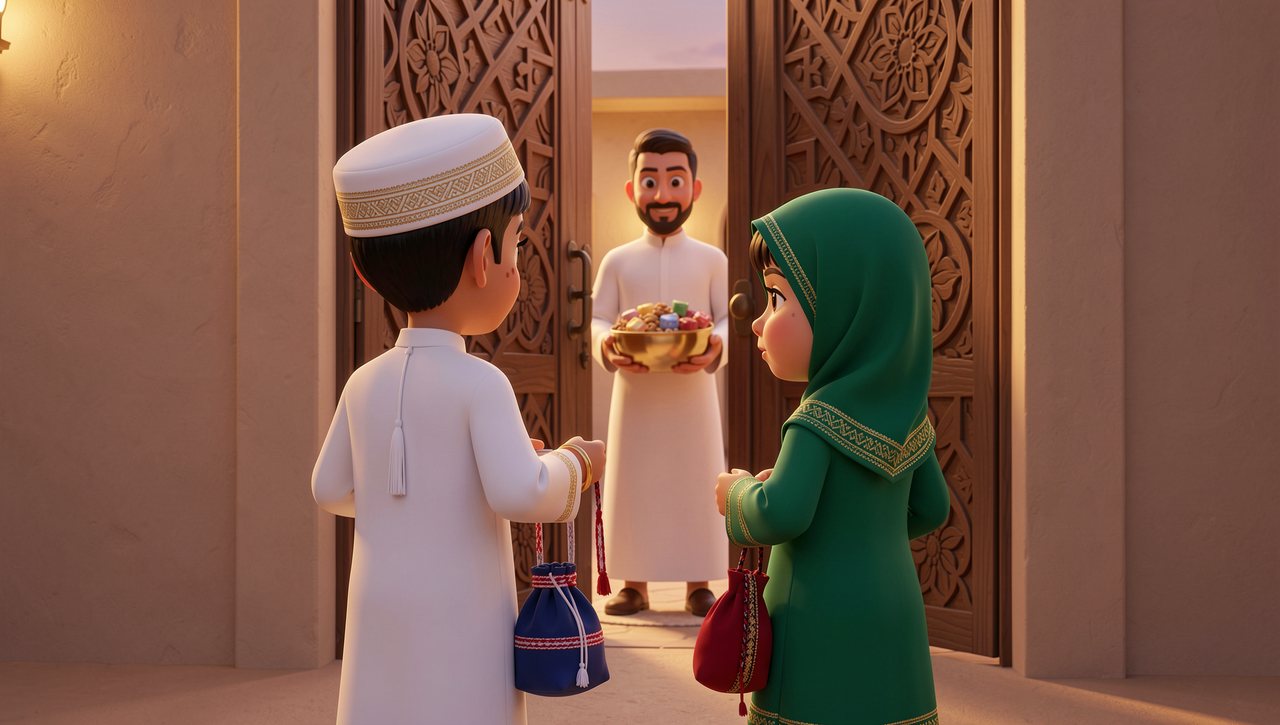
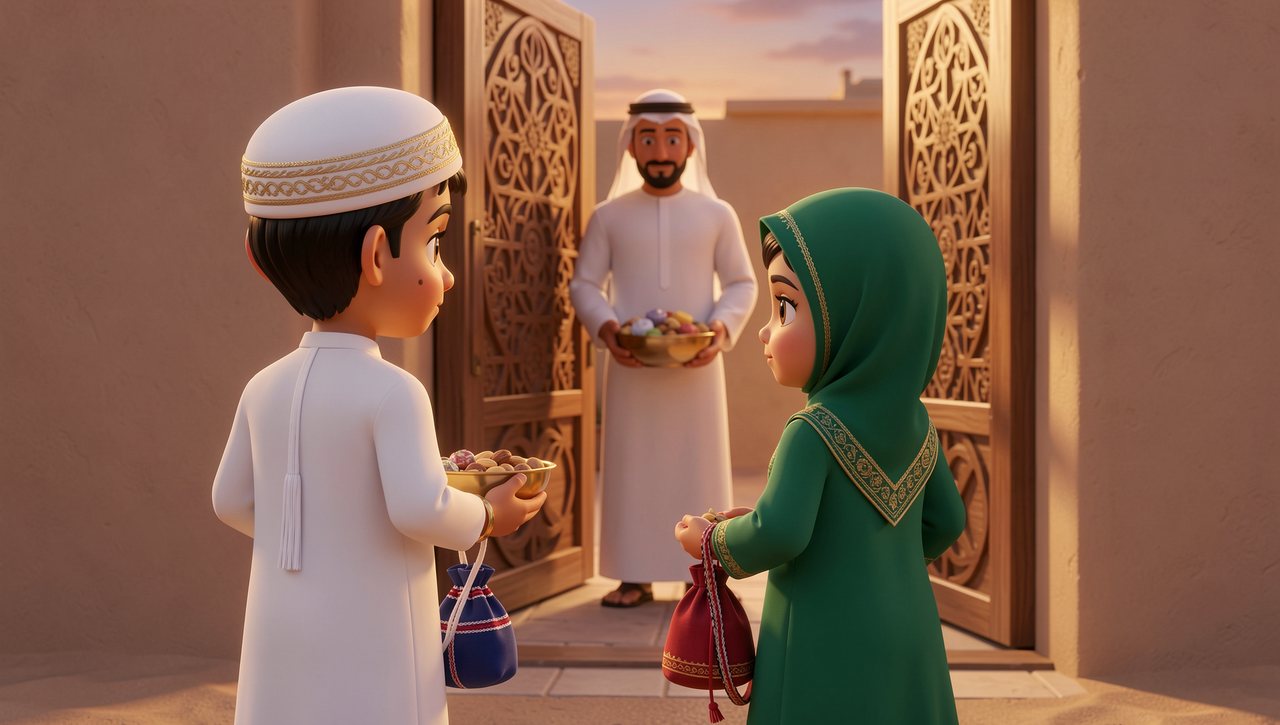
Keyframe review: Take 2: the only take with both bags right. The neighbour's face shows in every take, where only his chest down should be in frame.
The neighbour steps forward and tips sweets from the bowl into the bags, then the children turn toward the camera, delighted. Continuity slips at the end: Salem's skullcap disappears as he turns, he briefly holds two indigo bags, and Noora's head covering changes shape. The neighbour's face is fully visible where the script keeps him chest-down.
Shot 20 (8 s): Noora
Wide shot, blue dusk after sunset, lamps glowing by the gates and in the windows. Salem and Noora walk home hand in hand down the lane with their khareetahs full and round, and Yaddi a few steps behind; far behind them a small group of children with an adult heads home too. Noora looks up at her brother as she speaks.
يوم إنت ويّاي، ما أستحي.
When you're with me, I'm not shy.
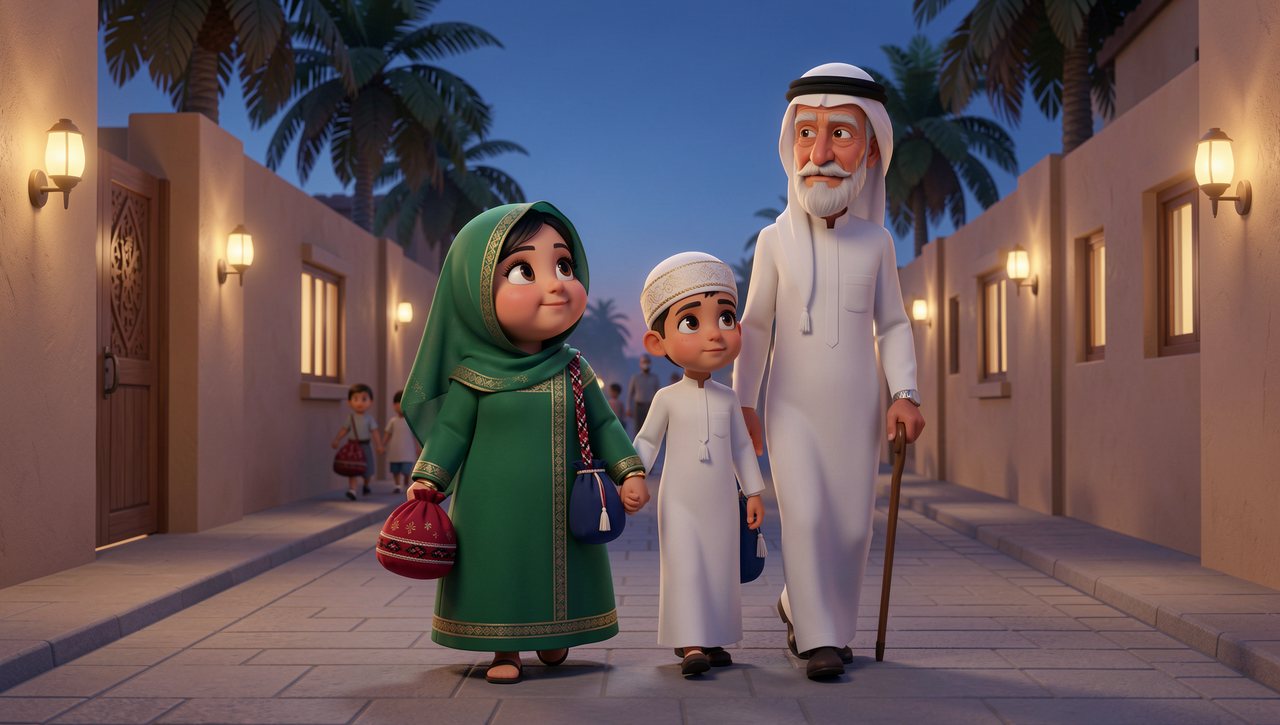
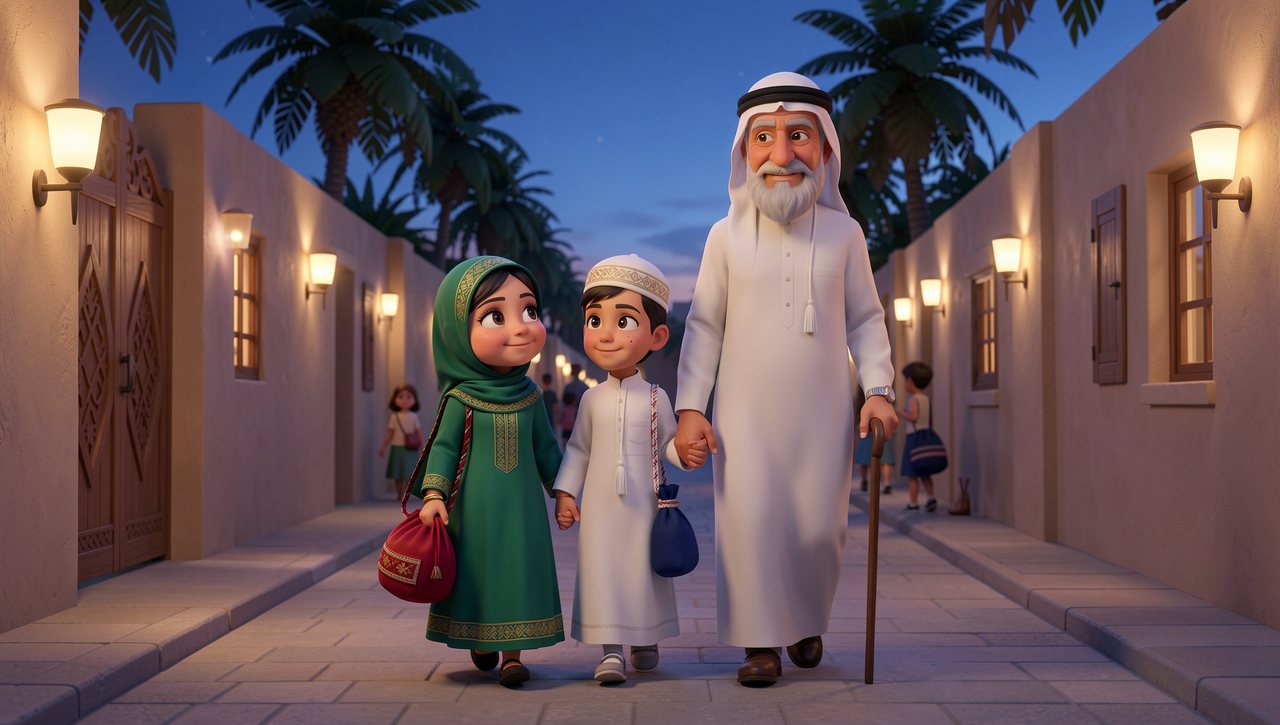
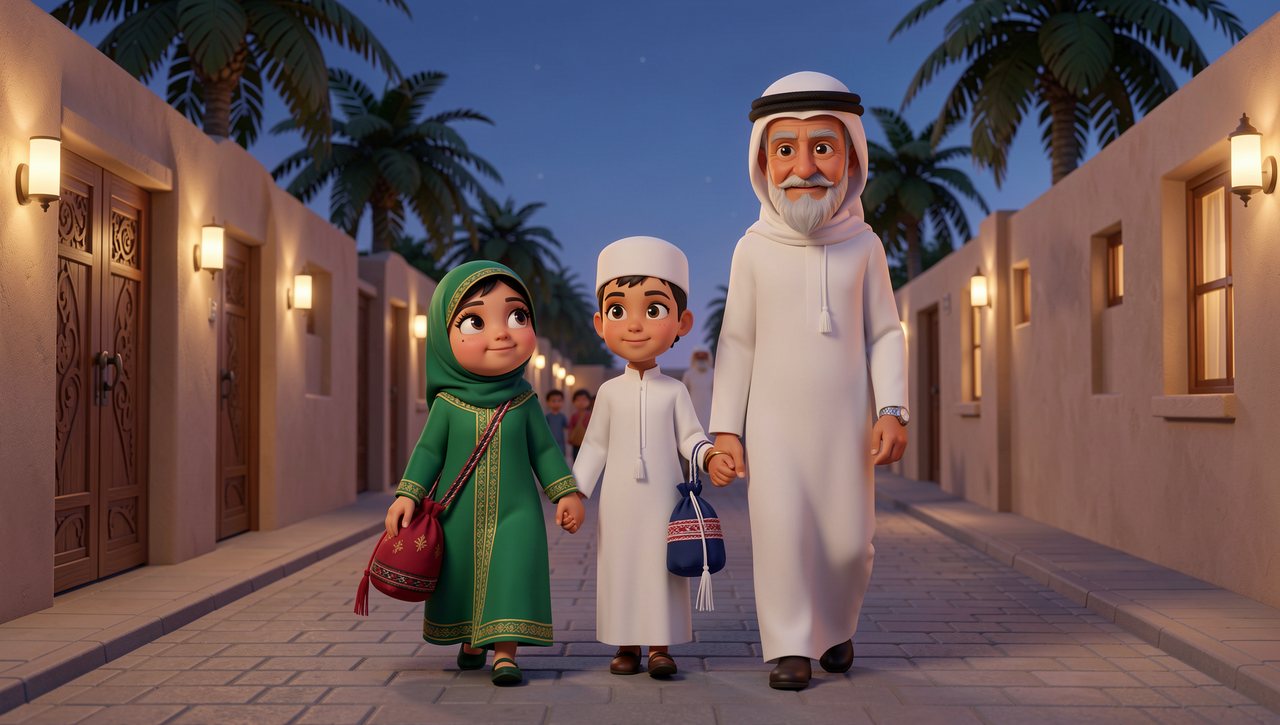
Keyframe review: Take 1: the children hand in hand, Noora's face clear for her line. Yaddi walks beside them, not behind, in all three.
The walk home under the lamps: the camera tracks back ahead of the three of them, Noora speaks her line as they come close, and everyone stays consistent. One of the best clips of the night.
Shot 21 (7 s): Noora
The majlis by lamplight. Salem and Noora kneel on the carpet in front of Yadda and tip their khareetahs into a wide brass tray before her. Nuts and wrapped sweets spill out.
يدّه! هذا كلّه لج!
Yadda! This is all for you!
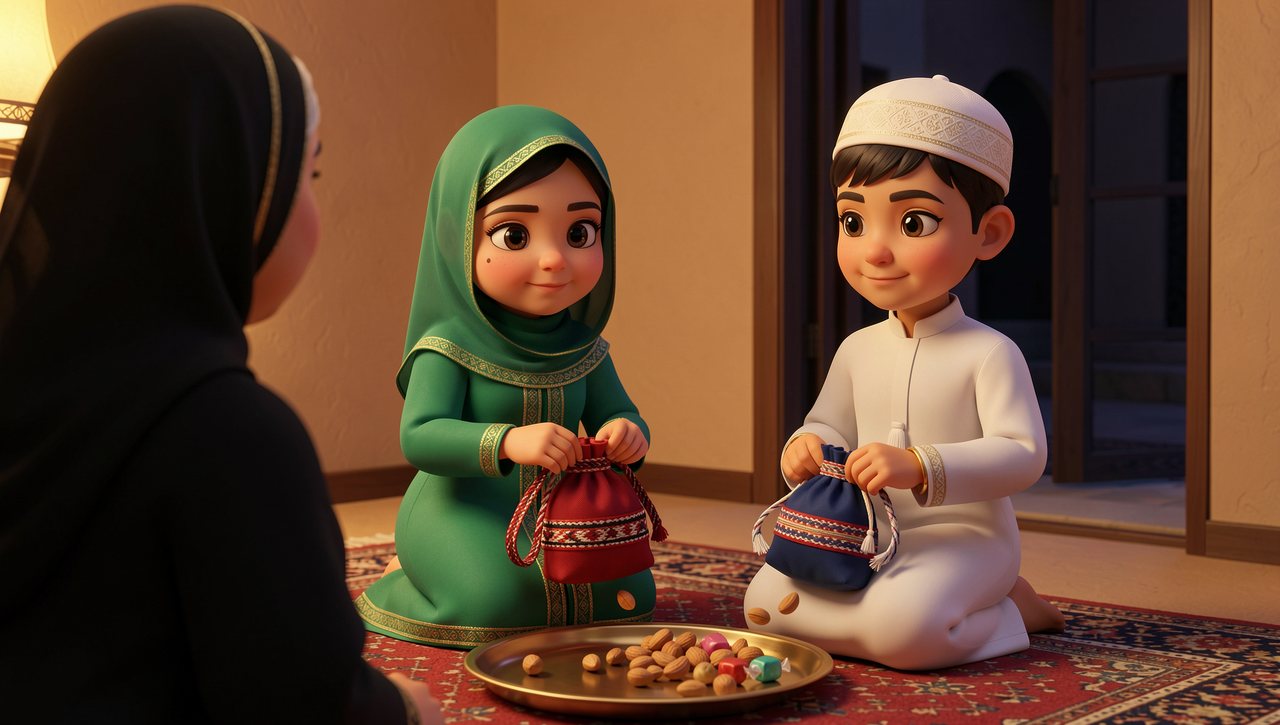
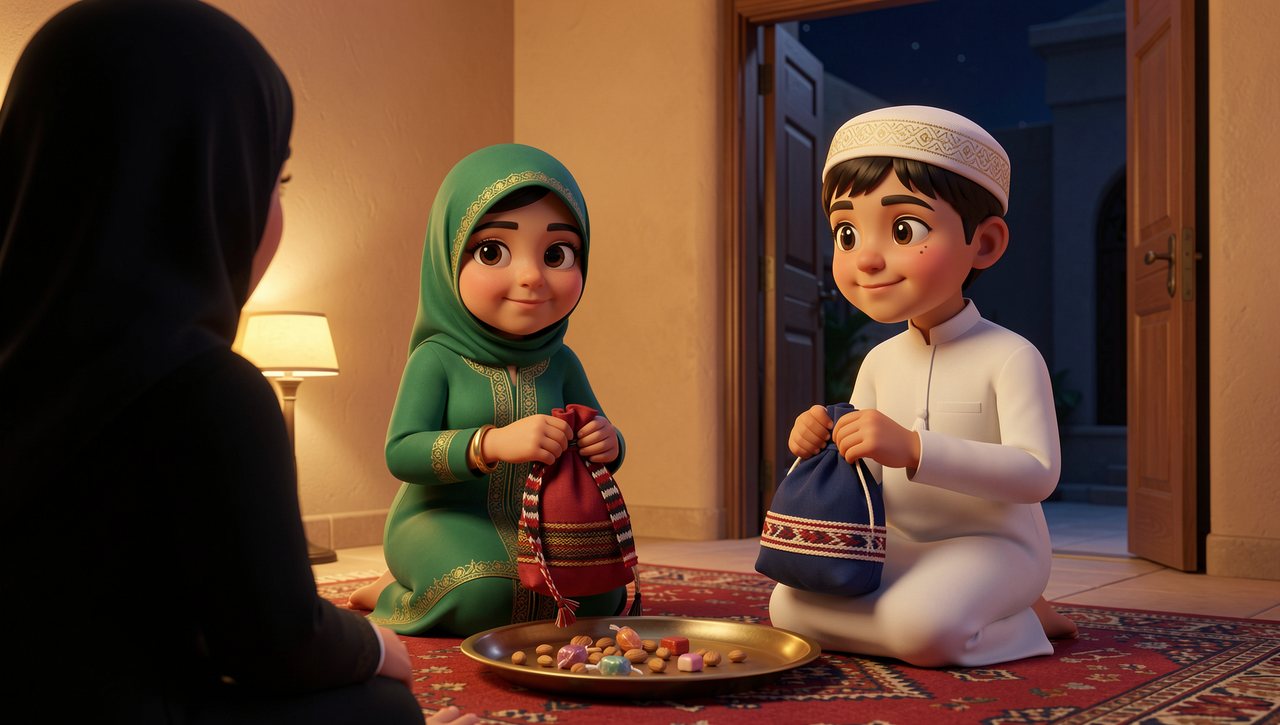
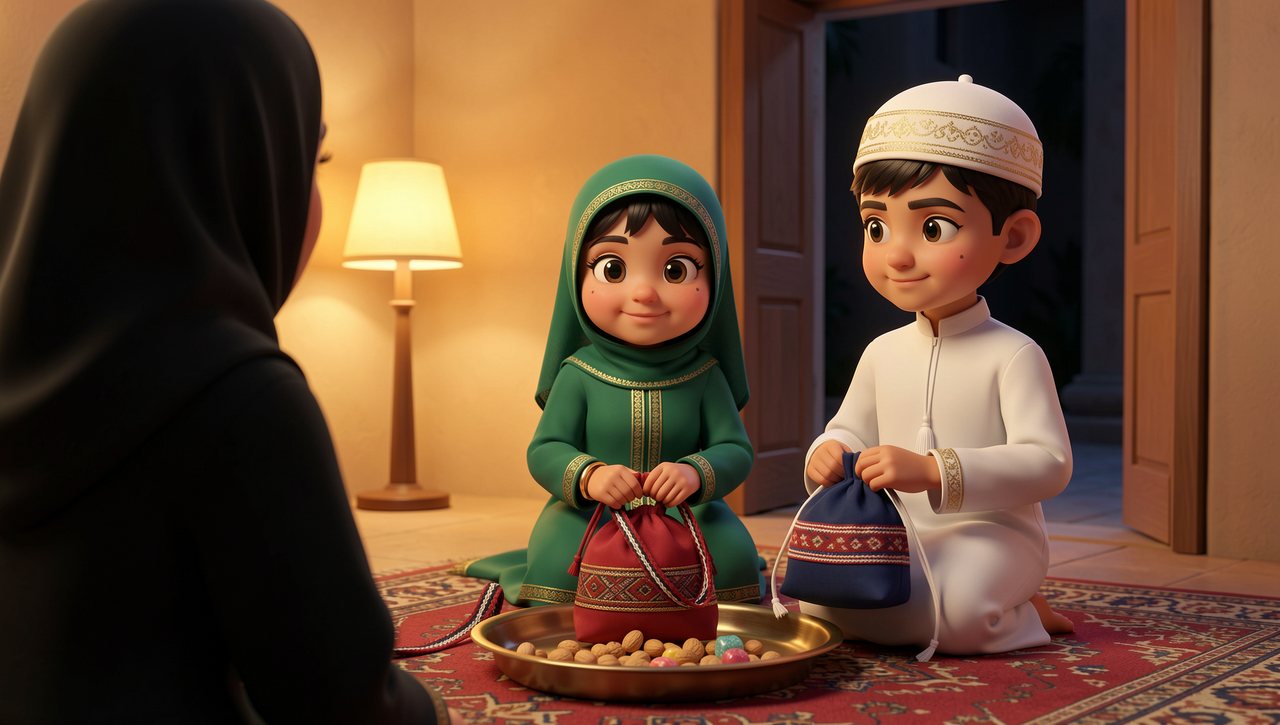
Keyframe review: Take 2: both bags right, both faces clear.
Seen over Yadda's shoulder, Salem and Noora kneel at the brass tray and work their bags open over it while Noora speaks. The sweets are already on the tray at the start rather than spilling out of the bags, so the moment of emptying them is lost.
Shot 22 (10 s): Yadda
Close-up: Yadda, eyes shining, rests her henna-stained right hand still on Noora's head covering and looks from one child to the other.
الخريطة ردّت متروسة… وقلبي بعد، يوم شفتكم ويا بعض.
The khareetah came back full… and so is my heart, seeing you two together.
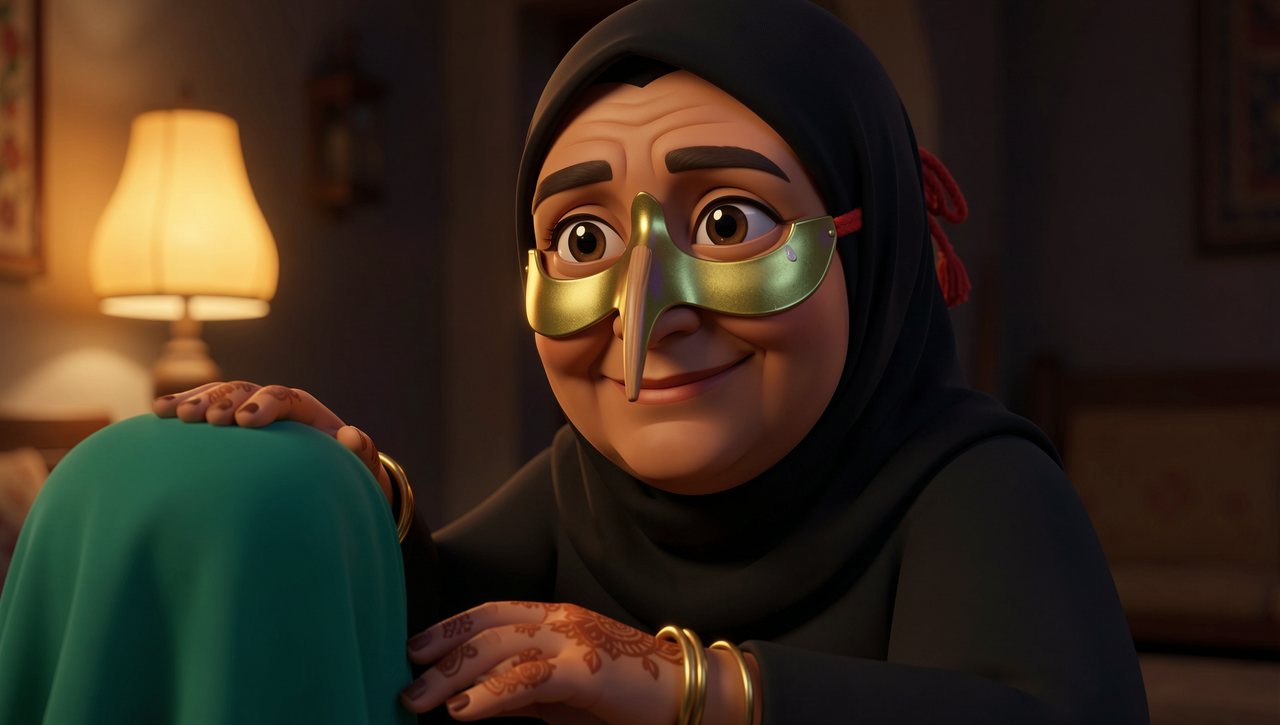
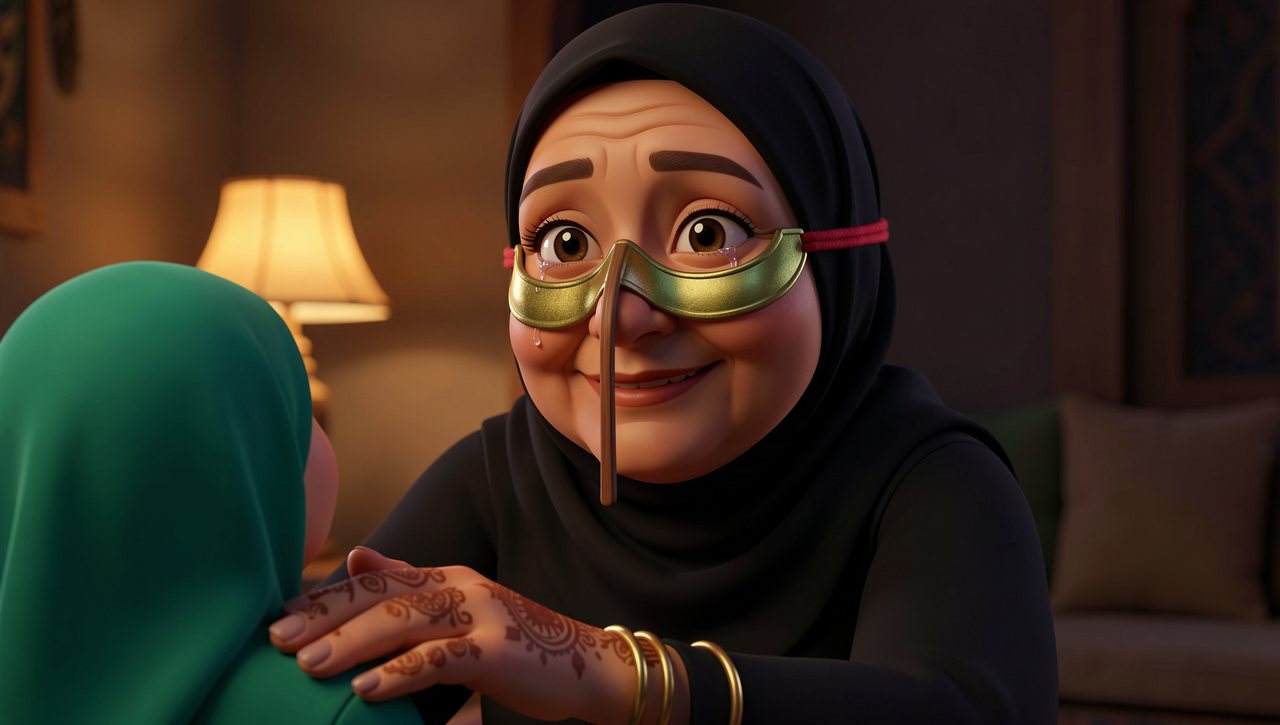
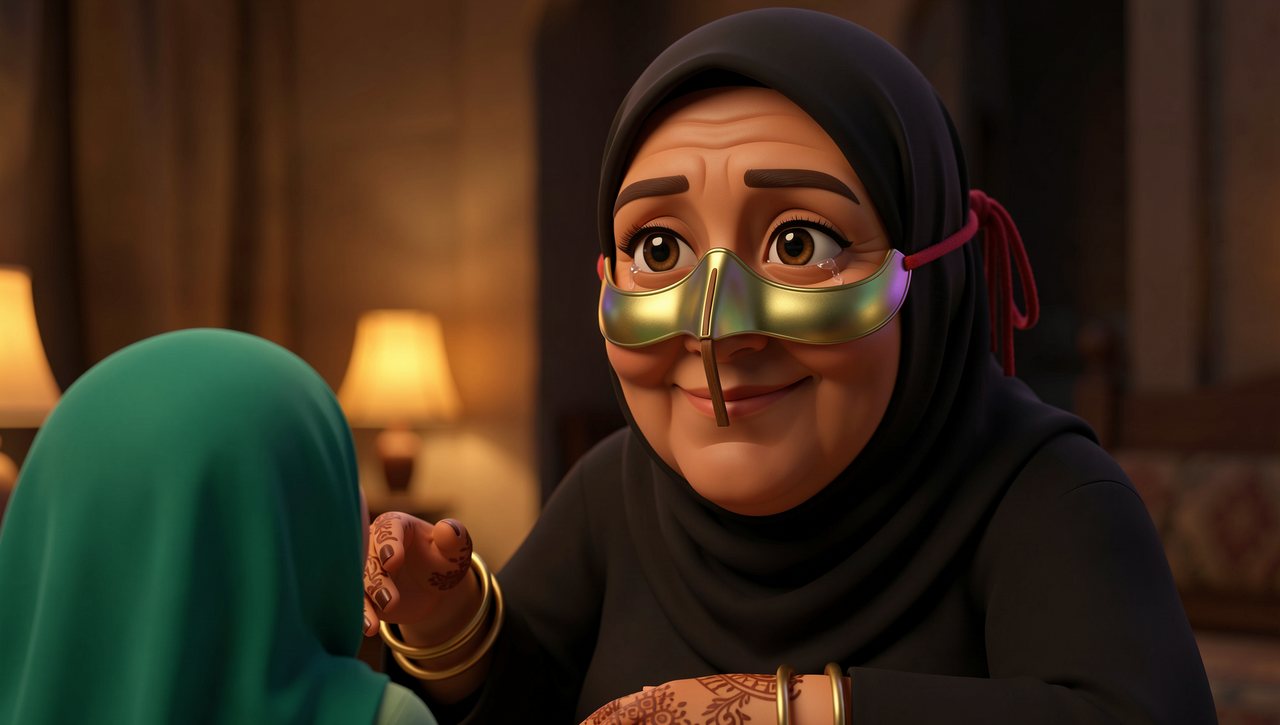
Keyframe review: Take 1: the rib stops at her nose, so her mouth is clear, and her hand rests on Noora's head covering. Take 2's rib crosses her mouth.
Yadda speaks her line in the first five seconds with her mouth visible below the battoulah, her hand resting on Noora's head covering, then smiles as the camera moves in slowly. As it moves in, the mask's rib stretches down past her lips, which would hide them if she were still speaking.
Shot 23 (13 s): Yaddi
Medium shot: Salem stands as gahwaji again, dallah in his LEFT hand with his thumb on top, and pours a small splash for Yaddi first. Yaddi takes it with his RIGHT hand, sips, gives the cup a gentle shake and hands it back with his RIGHT hand. As Yaddi speaks, Salem sets the dallah and finjans down on the tray and kneels beside him, and Yaddi rests his RIGHT hand on Salem's cap.
يزاك الله خير يا سالم. اليوم صدق كبرت.
May God reward you, Salem. Today you truly grew up.
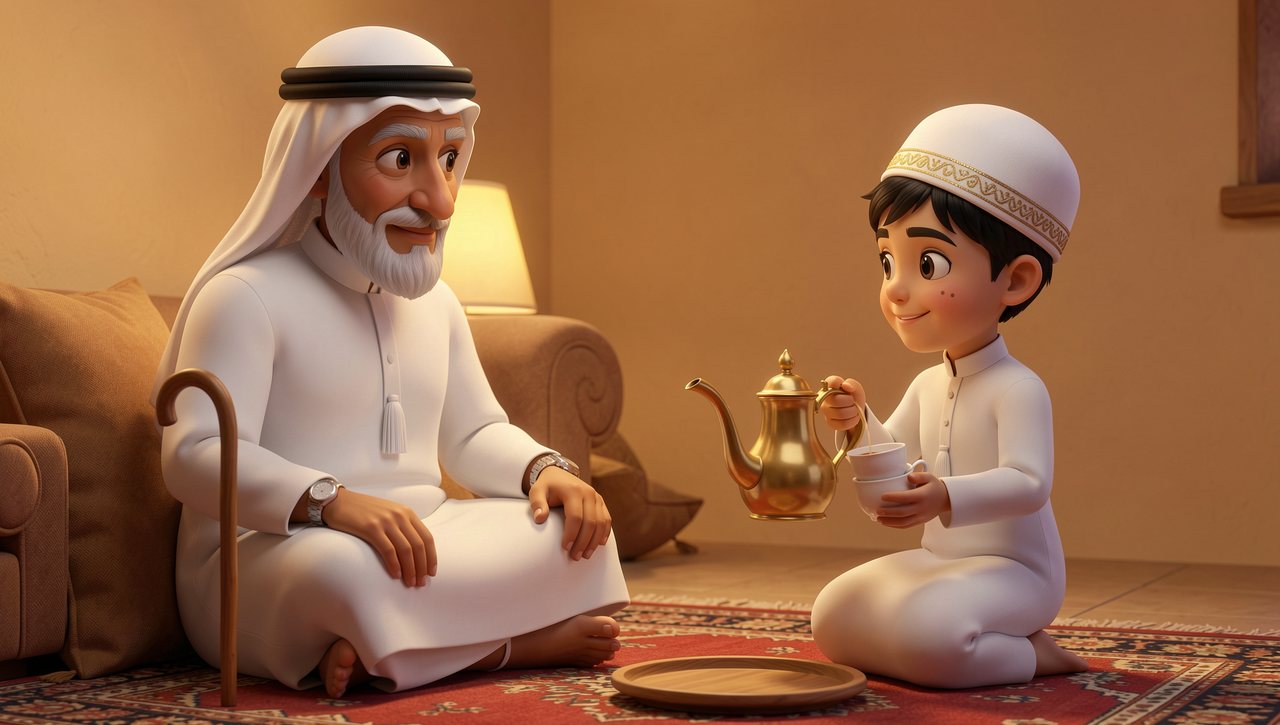
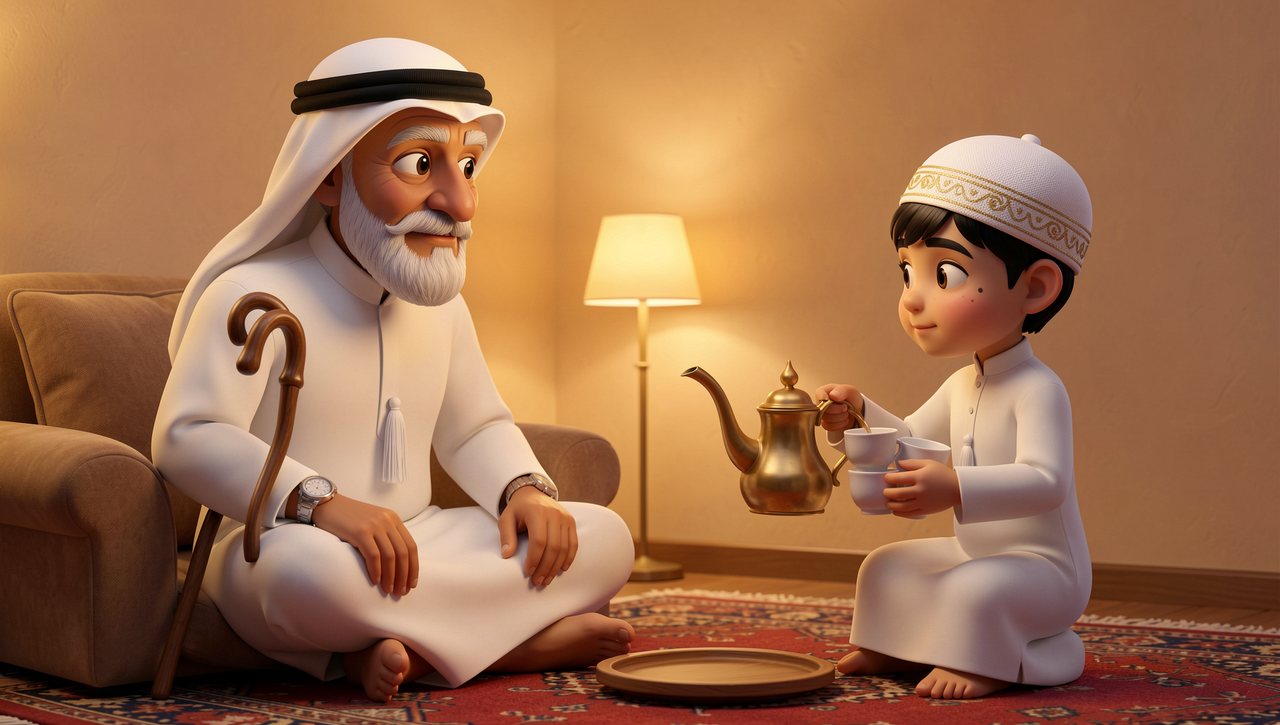
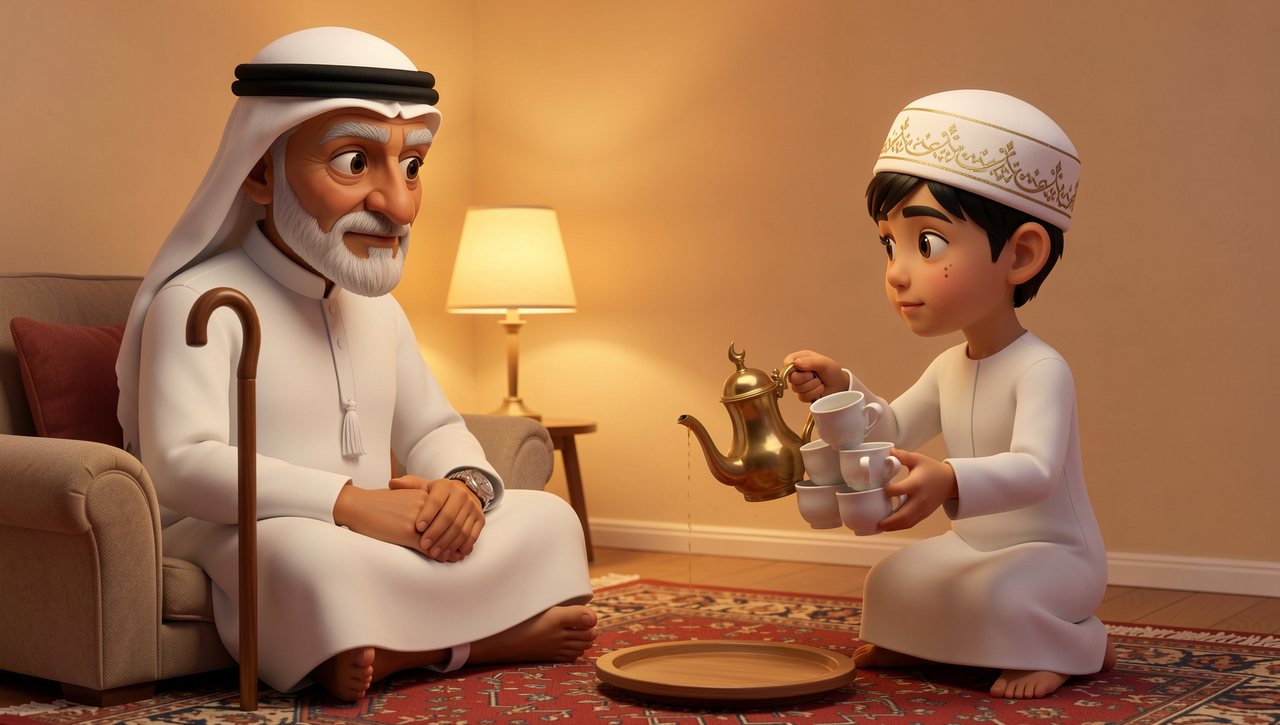
Keyframe review: Take 1. Salem kneels instead of standing in every take.
With the voice held, Yaddi's mouth stays closed until his line and moves through it (about 7.25-8.75 s) in both languages, and the two versions diverge after the line, as renders driven by different audio should. Both share a serious defect: in the last few seconds a second small boy in a ghutra appears between Yaddi and Salem beside the tray.
Shot 24 (9 s)
A little later. Wide shot of the lamplit majlis, the door open to the dark courtyard. Yadda scoops a handful of nuts from the brass tray and drops it back into each child's empty khareetah. Noora laughs and leans on her shoulder, Salem kneels beside them, and Yaddi watches from the head of the room, smiling. Hold.
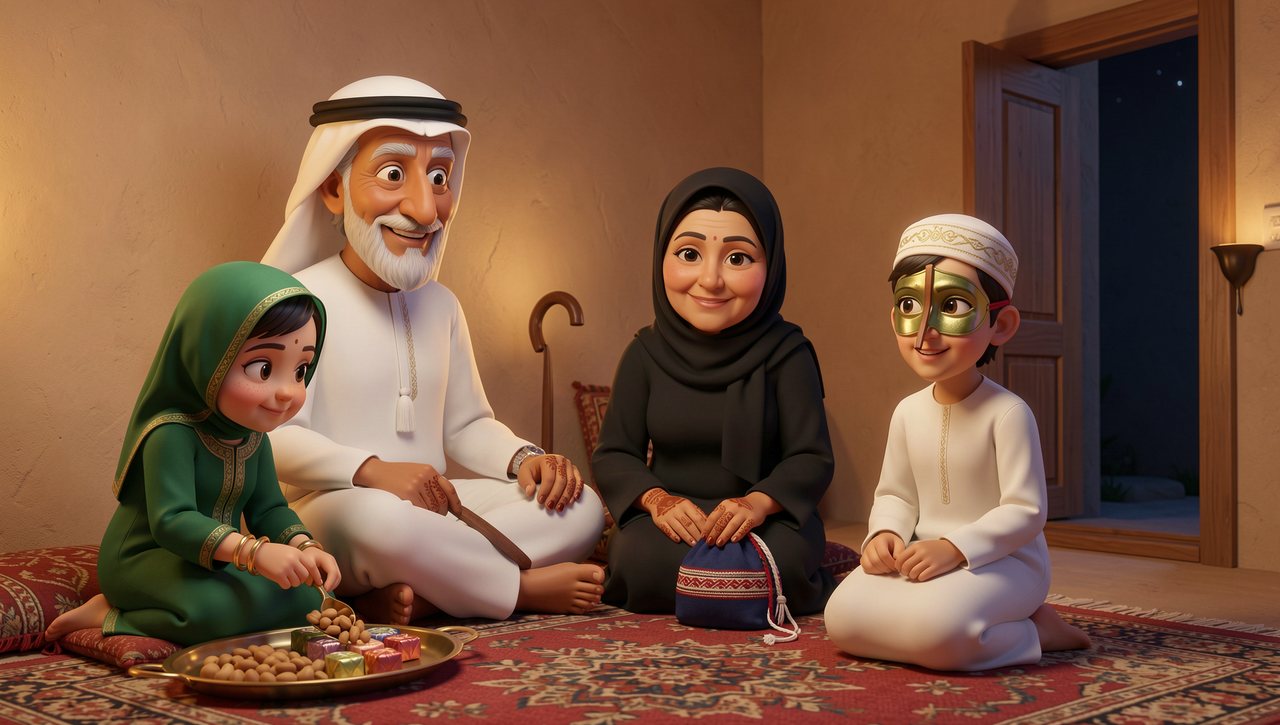
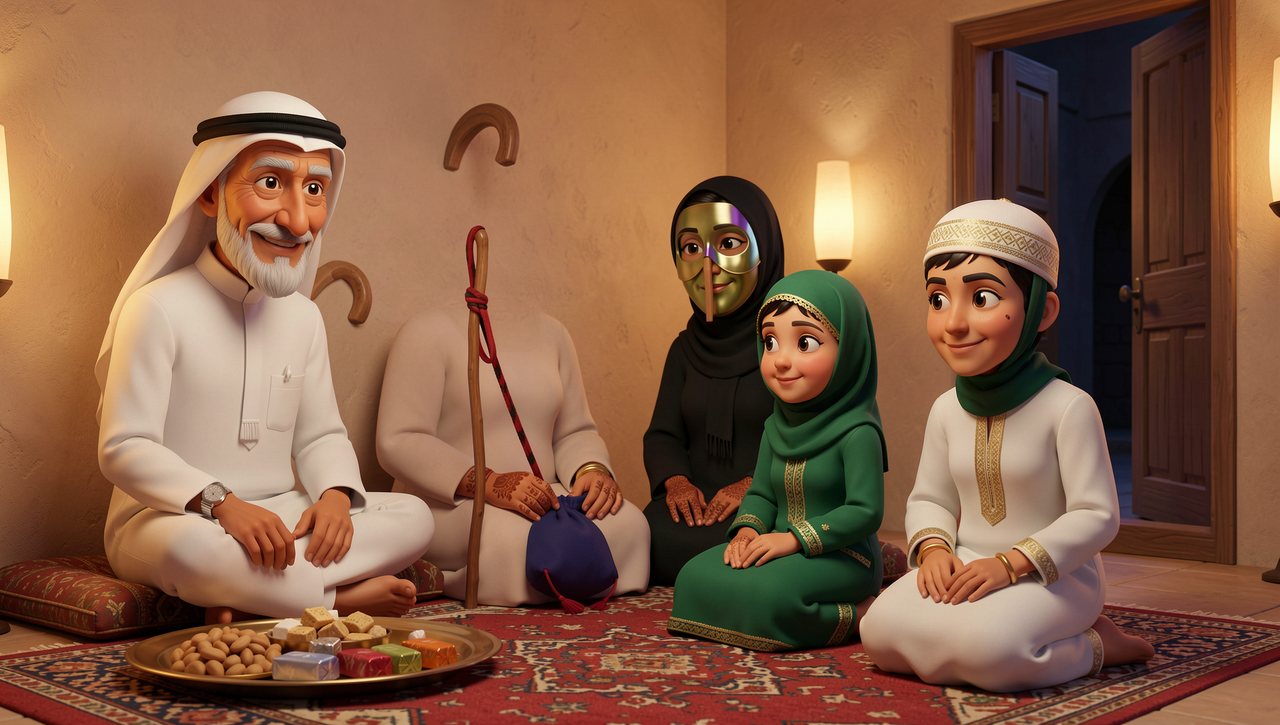
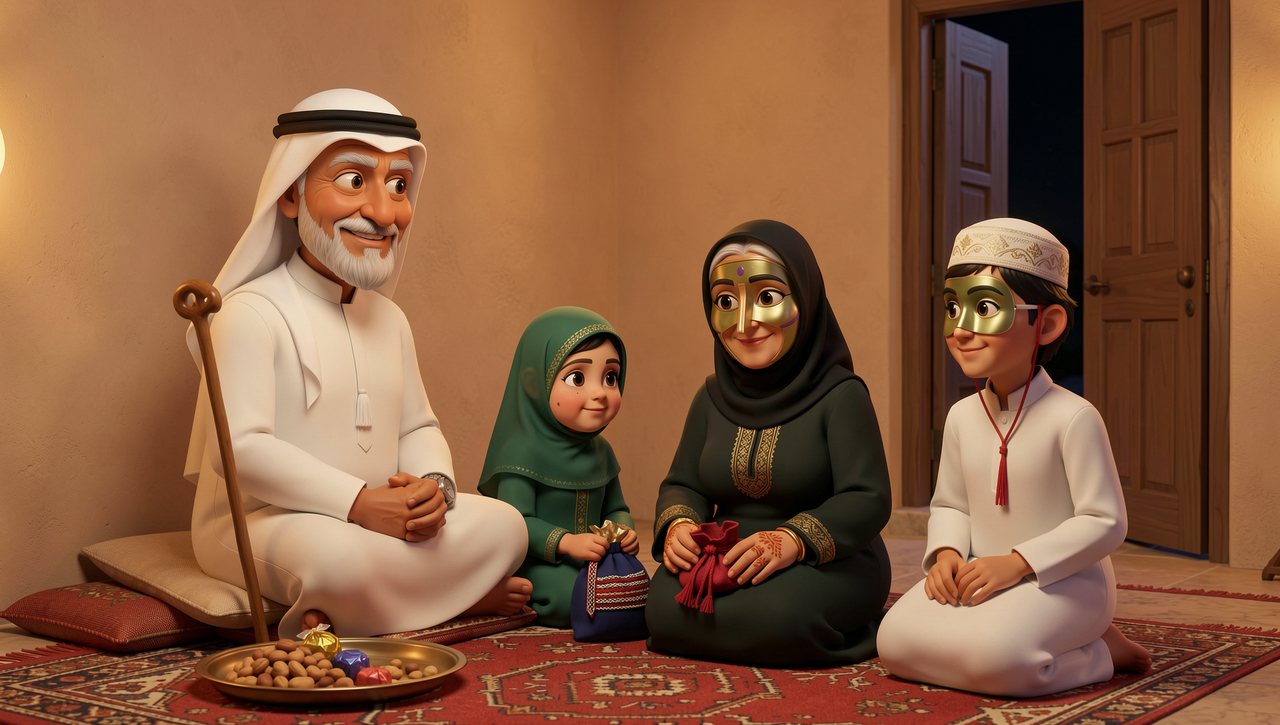
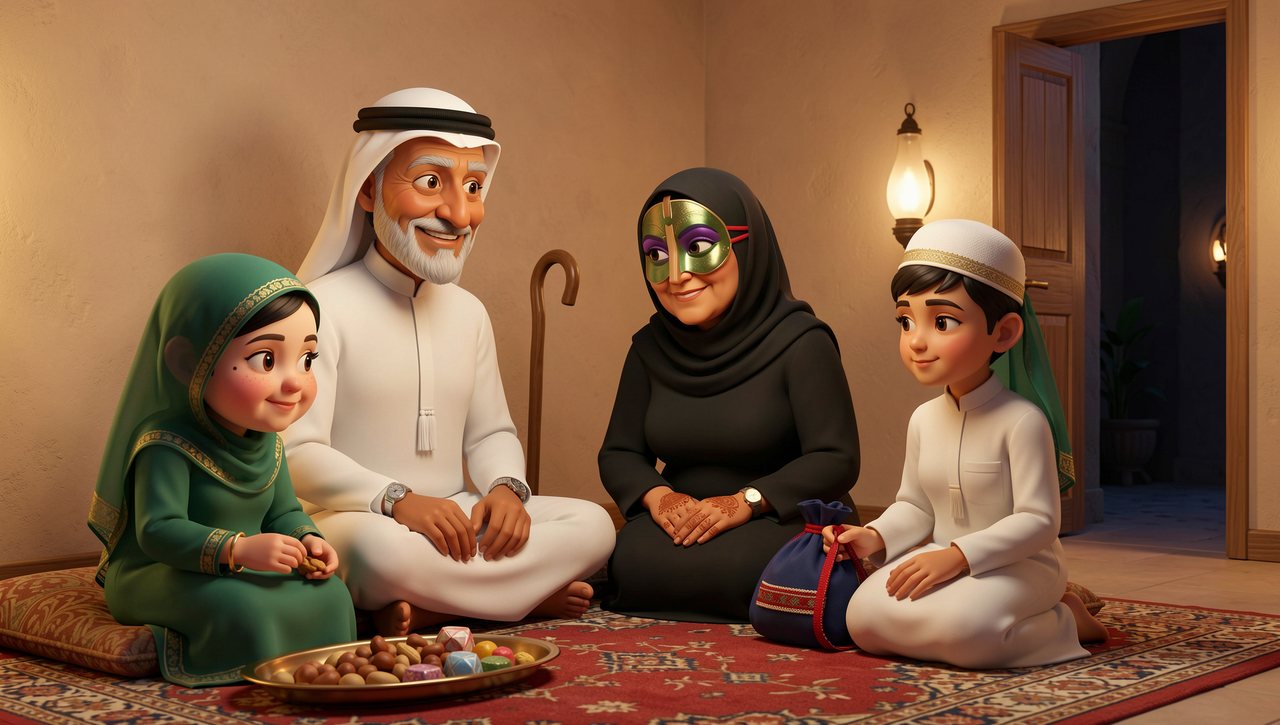
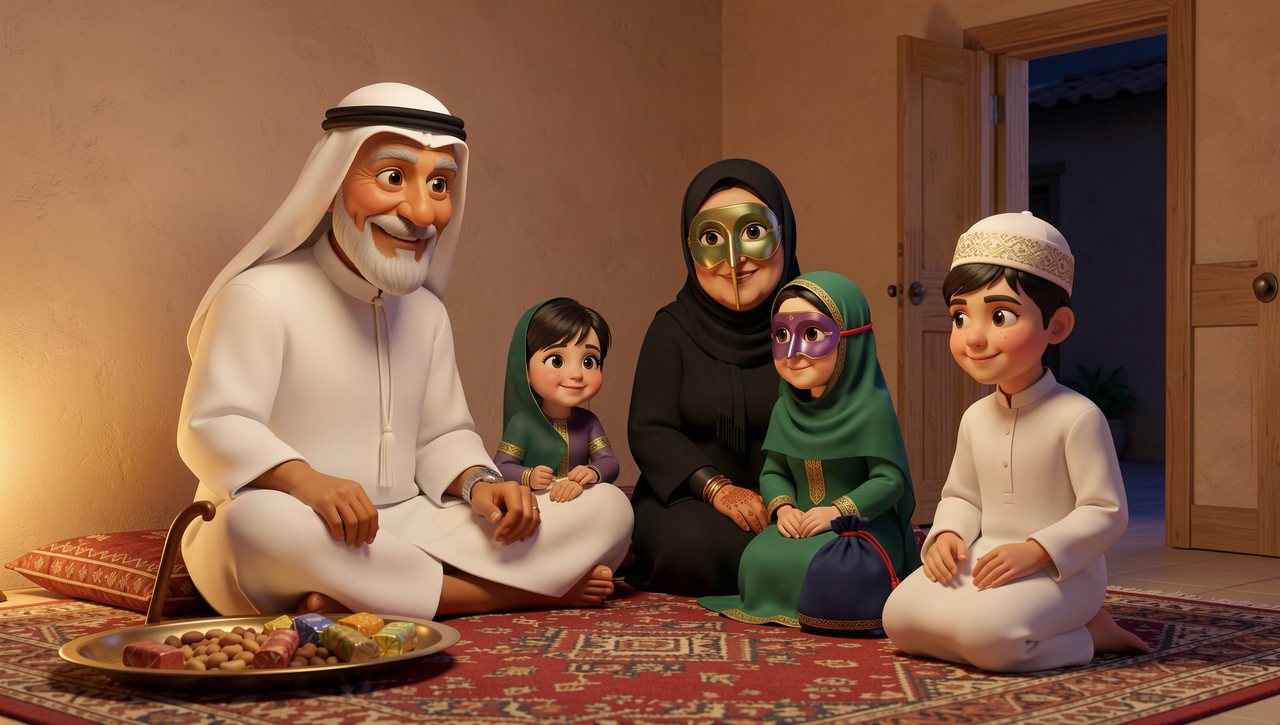
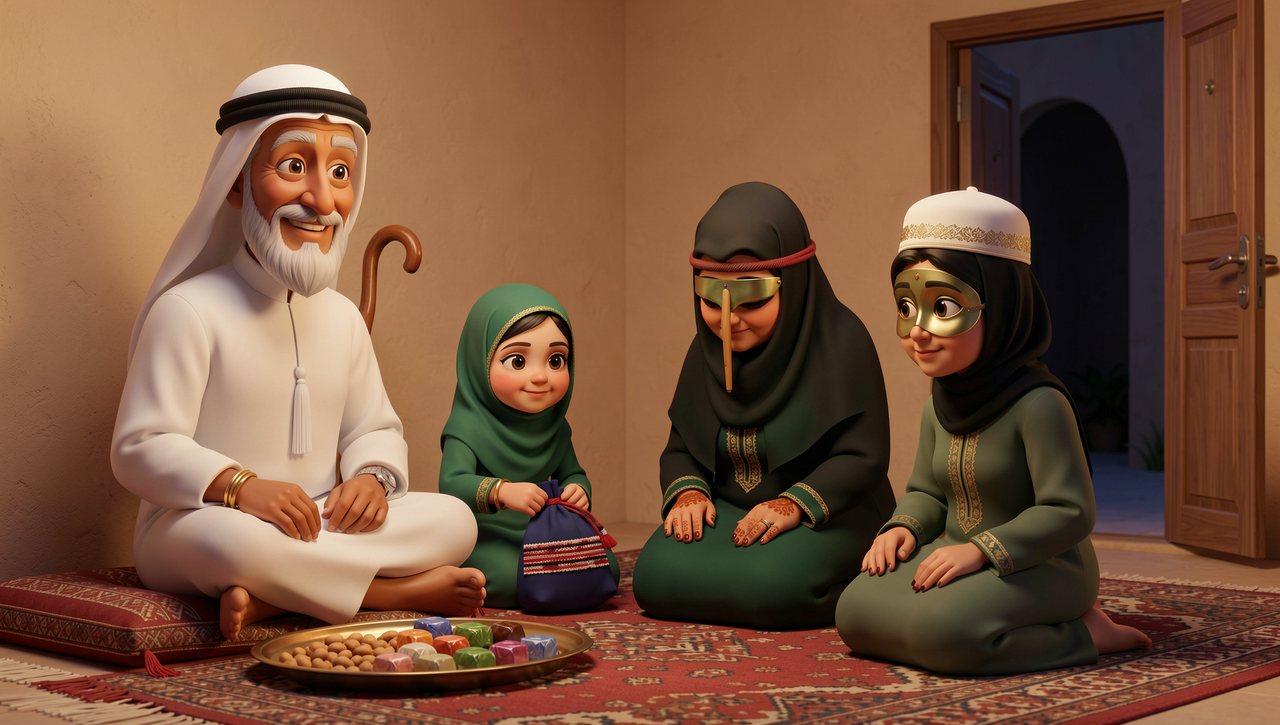
Keyframe review: All three wrong: Salem wears the battoulah in takes 1 and 3, and take 2 has an extra faceless figure. Takes 4-6 drawn. Picked take 4: right in every way that matters, four people, the battoulah on Yadda only, Salem in his skullcap.
The closing shot keeps all four characters recognisable and ends on Noora laughing, which is the right note. It departs from the direction in two ways: the camera pushes in where the shot asks for a slow pull-back, and Noora reaches for the tray and leans toward her grandfather instead of Yadda filling the bags and Noora leaning on her shoulder.
What is not right yet
- Characters in group shots. FLUX.2 [klein] 9B drawing from text alone gets the right person wrong when several characters share a frame: the battoulah lands on a child, the children’s bags swap, an extra person appears. Six of the 24 shots had no correct take in three, and three of those still had no fully correct take in six. The single-character shots were fine.
- The battoulah. The model draws the traditional face mask as a masquerade-style eye mask, and its central rib often hangs down across the mouth. On a speaking shot that hides the lips.
- Continuity details. Salem kneels where he should stand, a modern paved street stands in for the old sand lanes, sofas stand in for floor cushions, and people and props appear or change within a clip: an adult’s arm where Salem’s should be, a second small boy beside the tray, a cane standing on its own, Salem’s skullcap vanishing.
- Hands in fast motion. Clapping smears the children’s hands into blurs.
- Unasked-for edits. One clip, shot 16, came back with a hard cut inside it, and some camera moves go further or somewhere other than the shot asks.
- The chant. Shots 12 and 18 have no audio yet, because a text-to-speech model cannot sing it. The children’s mouths move with nothing to follow.
- The Arabic. The Emirati Arabic lines and the synthetic voices have not yet been checked by a native speaker, and the speech-recognition check we used reads dialect words in standard spelling, so it can only confirm that the words are roughly there.
- No ambience or sound effects, and no colour pass. The music bed is a first pick from six takes, not a score.
Next
- Draw group shots with reference images of the chosen character sheets, which FLUX.2 [klein] supports, instead of from text alone, and rewrite the battoulah description so the mouth stays uncovered.
- Test the dedicated audio-driven lip-sync models we have downloaded against LTX-2.5 on the speaking shots.
- Record or generate the Hag Al Laila chant and render the two chant shots against it.
- Have a native Emirati speaker review every Arabic line and voice take.
- Choose the music take by ear, then add ambience and sound effects and re-cut.
Earlier in this series: five self-hosted image models drawing the same character sheets and eight self-hosted voice models in Arabic and English.
The Stories of Wulfa series, in order
- Five self-hosted image models draw the same character sheets
- Eight self-hosted voice models in Arabic and English
- The animated pilot overnight: three video models, then 24 shots in Arabic and English (this post)
- Pass 2: reference pictures, the chant, lip sync and other voice-driven video models (latest)
Quick Search Our Blogs
Type in keywords and get instant access to related blog posts.